
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Image Generation
41 article(s) found · Clear tag
MiniMax H3 Max: fal's Post-trained Real-time Video Model — Faster than Real-time, No Benchmarks Published
H3 Max is a hosted service built on the open-source H3 base model. It suits teams that want to integrate video generation into real-time content production workflows, as well as individual users looki...
Luna-TTS – A Text-to-Speech Large Model from VUI Labs
Luna-TTS is a text-to-speech large model independently developed by VUI Labs, a startup company affiliated with Shanghai Jiao Tong University. This model abandons the mainstream autoregressive generat...
Wan-Animate-2 – The Next-Generation Character Animation Model Open-Sourced by WanXiang Team
Wan-Animate-2 is the next-generation character animation model open-sourced by the WanXiang team, representing a major architectural upgrade from Wan-Animate. It employs an end-to-end dual-branch Diff...
JoyAI-Video-Edit – JD.com's Open-Source Real-Time Streaming Video Editing Model
JoyAI-Video-Edit is a real-time streaming video editing model developed and open-sourced by JD.com. It is based on a self-regressive diffusion architecture with 16B parameters, achieving end-to-end in...
LLaDA2.2-flash – InclusionAI's Open-Source Diffusion Language Model
LLaDA2.2-flash is a diffusion language model (dLLM) open-sourced by InclusionAI. It employs a Mixture-of-Experts (MoE) architecture with approximately 100B total parameters and natively supports a 128...
MAI-Image-2.5-Pro – Microsoft's High-Precision Image Generation Model
MAI-Image-2.5-Pro is a high-precision image generation model developed by Microsoft's AI team, focusing on generating high-quality main visual images, realistic photographs, and commercial design mate...
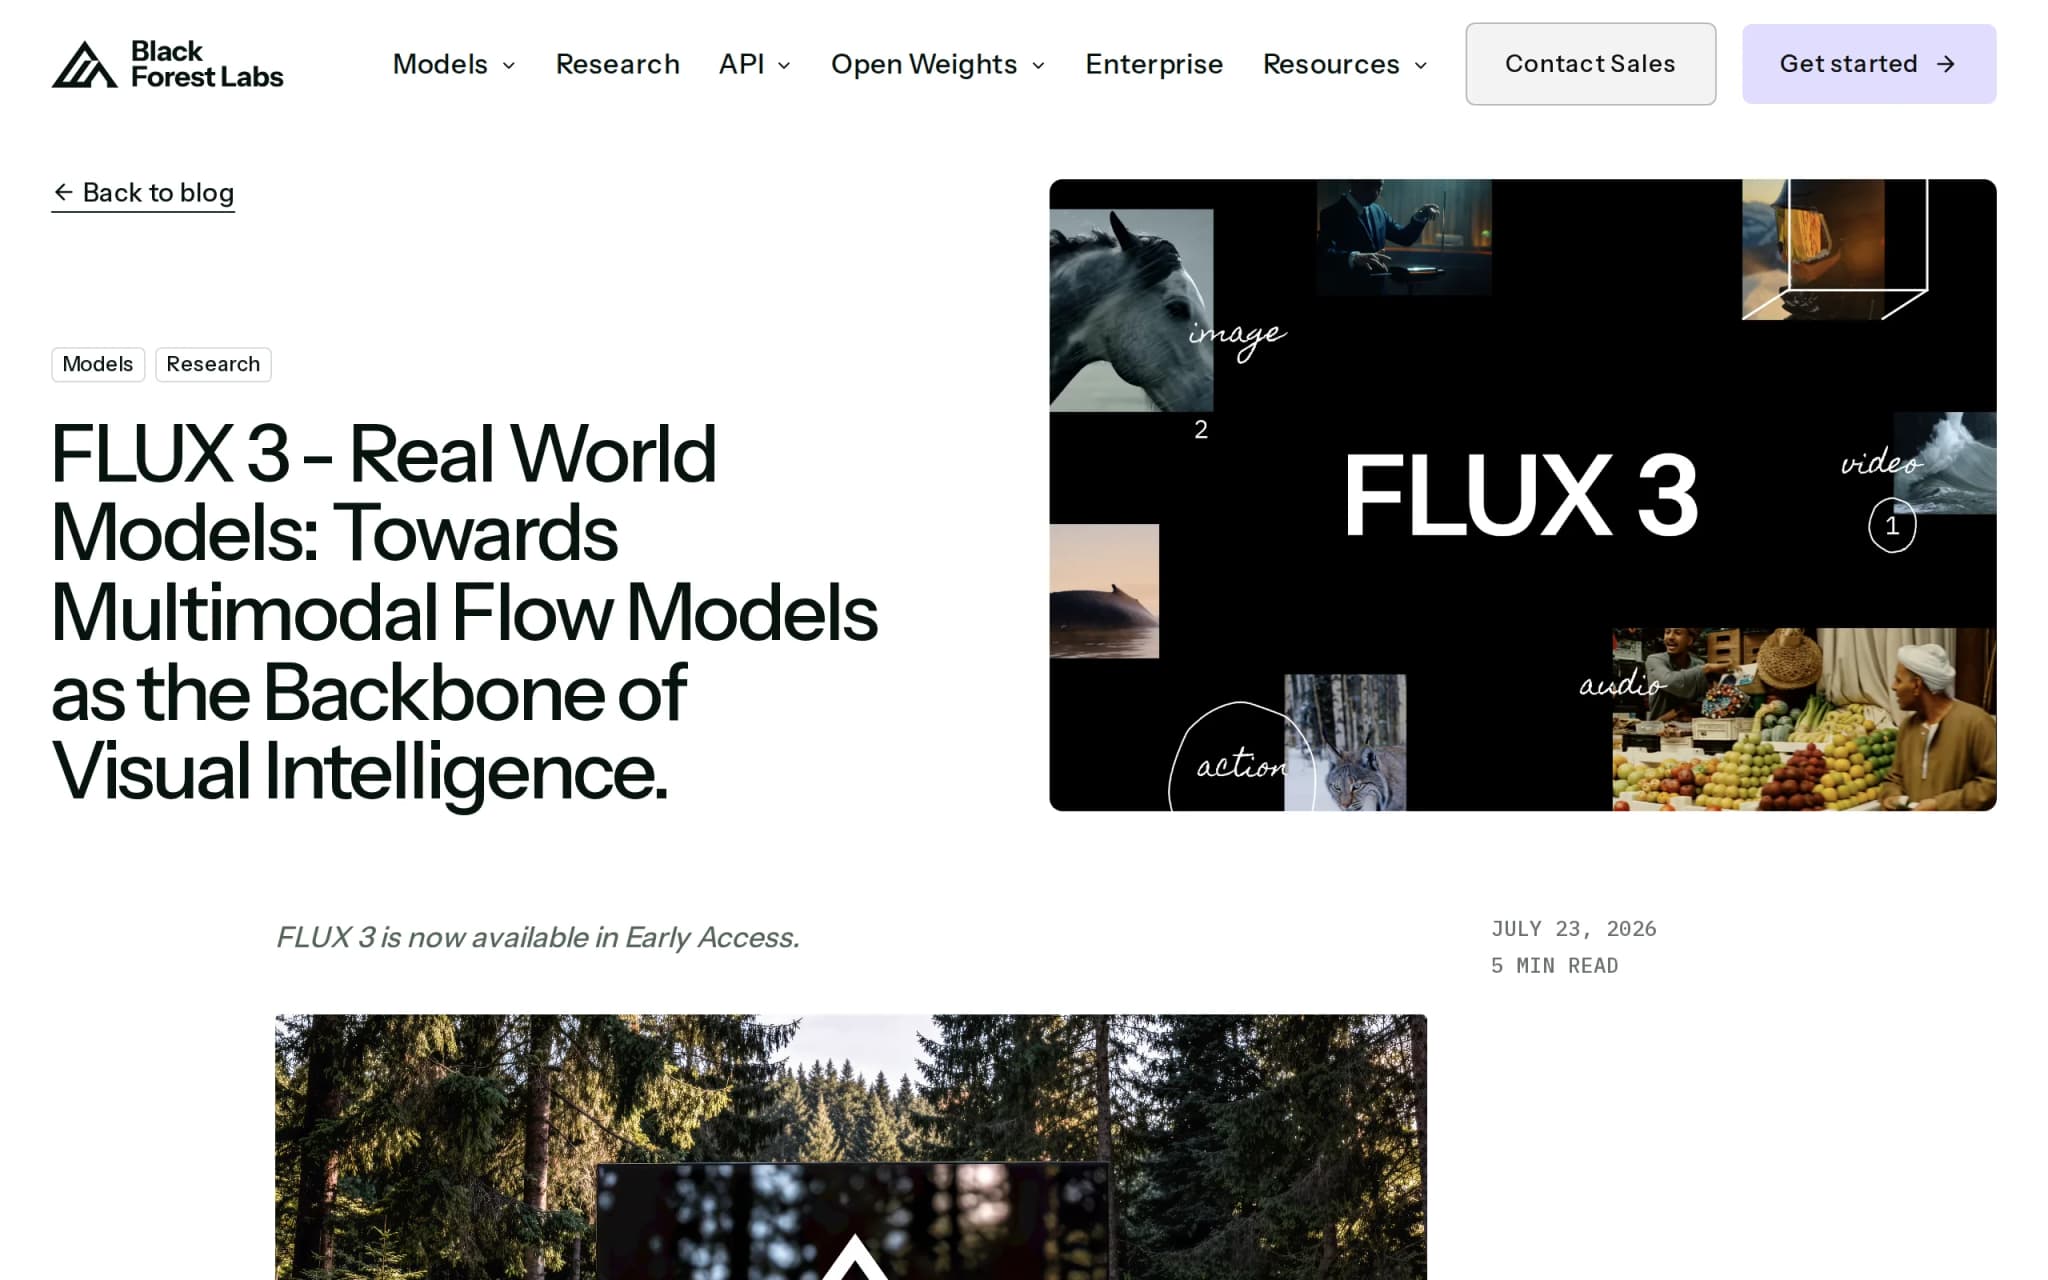
FLUX 3 – A Multimodal Foundation Model Launched by Black Forest Labs
FLUX 3 is a multimodal foundation model launched by Black Forest Labs, which for the first time jointly learns images, videos, and audio under a unified architecture. Based on Self-Flow technology, th...
Cosmos 3 Edge – NVIDIA's 4B Parameter Open-Source World Model
Cosmos 3 Edge is a 4B parameter open-source world model introduced by NVIDIA, specifically designed for real-time inference in robotics and edge AI. Based on the Nemotron architecture, the model integ...

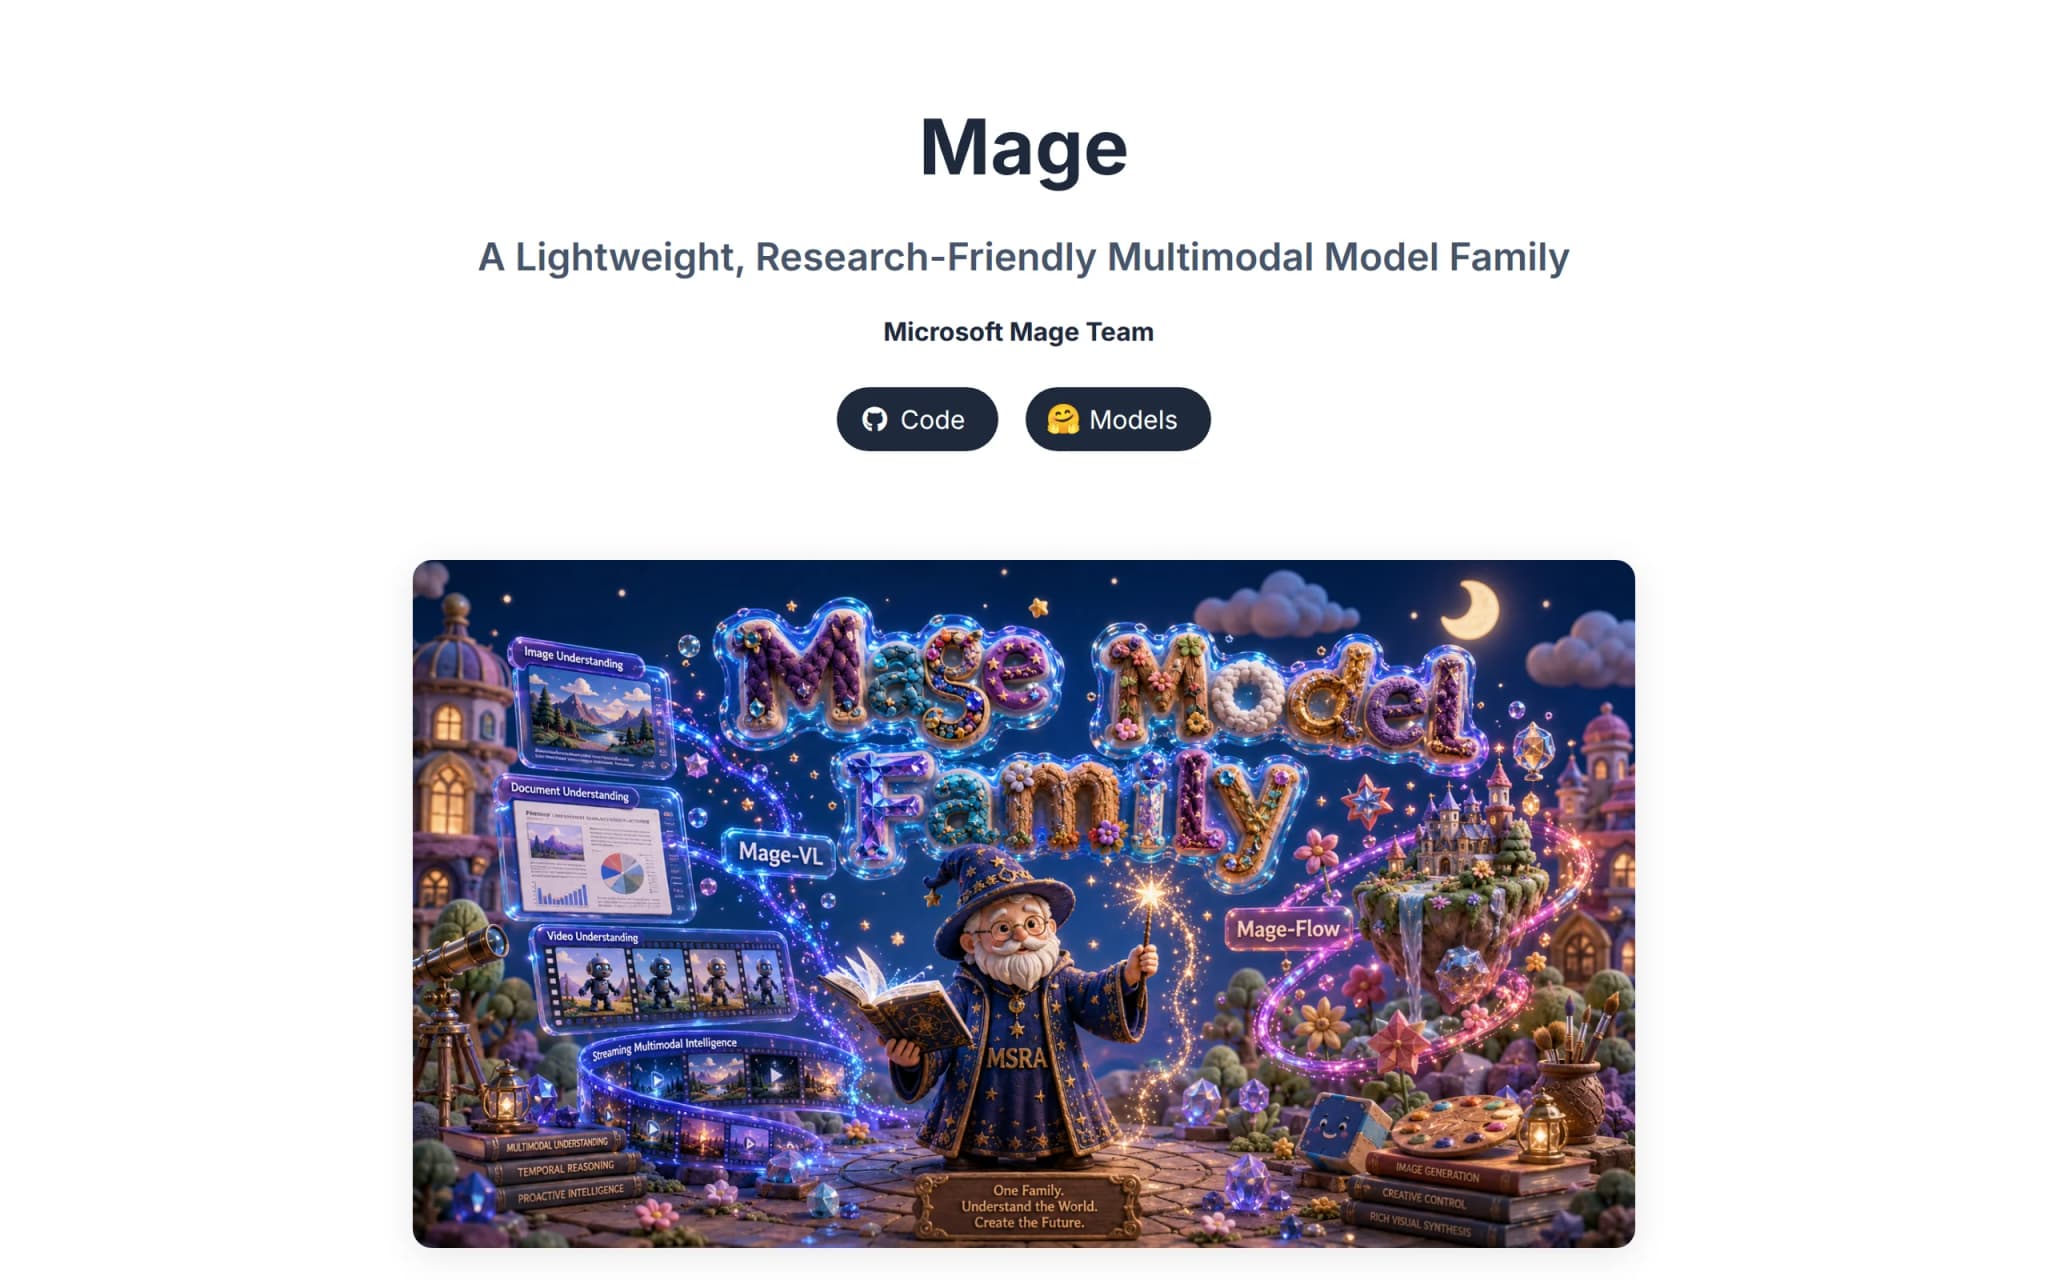
Mage-Flow – Microsoft's Open-Source Lightweight Multimodal Image Generation Model Series
Mage-Flow is a lightweight multimodal image generation model series open-sourced by Microsoft, based on a flow-matching architecture and featuring only 4B parameters. The model includes four variants:...
SeFi-Image – Open-Source Text-to-Image Model Based on Semantic-Priority Diffusion
SeFi-Image is an open-source text-to-image generation model based on a semantic-priority diffusion architecture, offering three parameter configurations: 1B, 2B, and 5B. This model separates high-leve...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.