
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: LLM
81 article(s) found · Clear tag
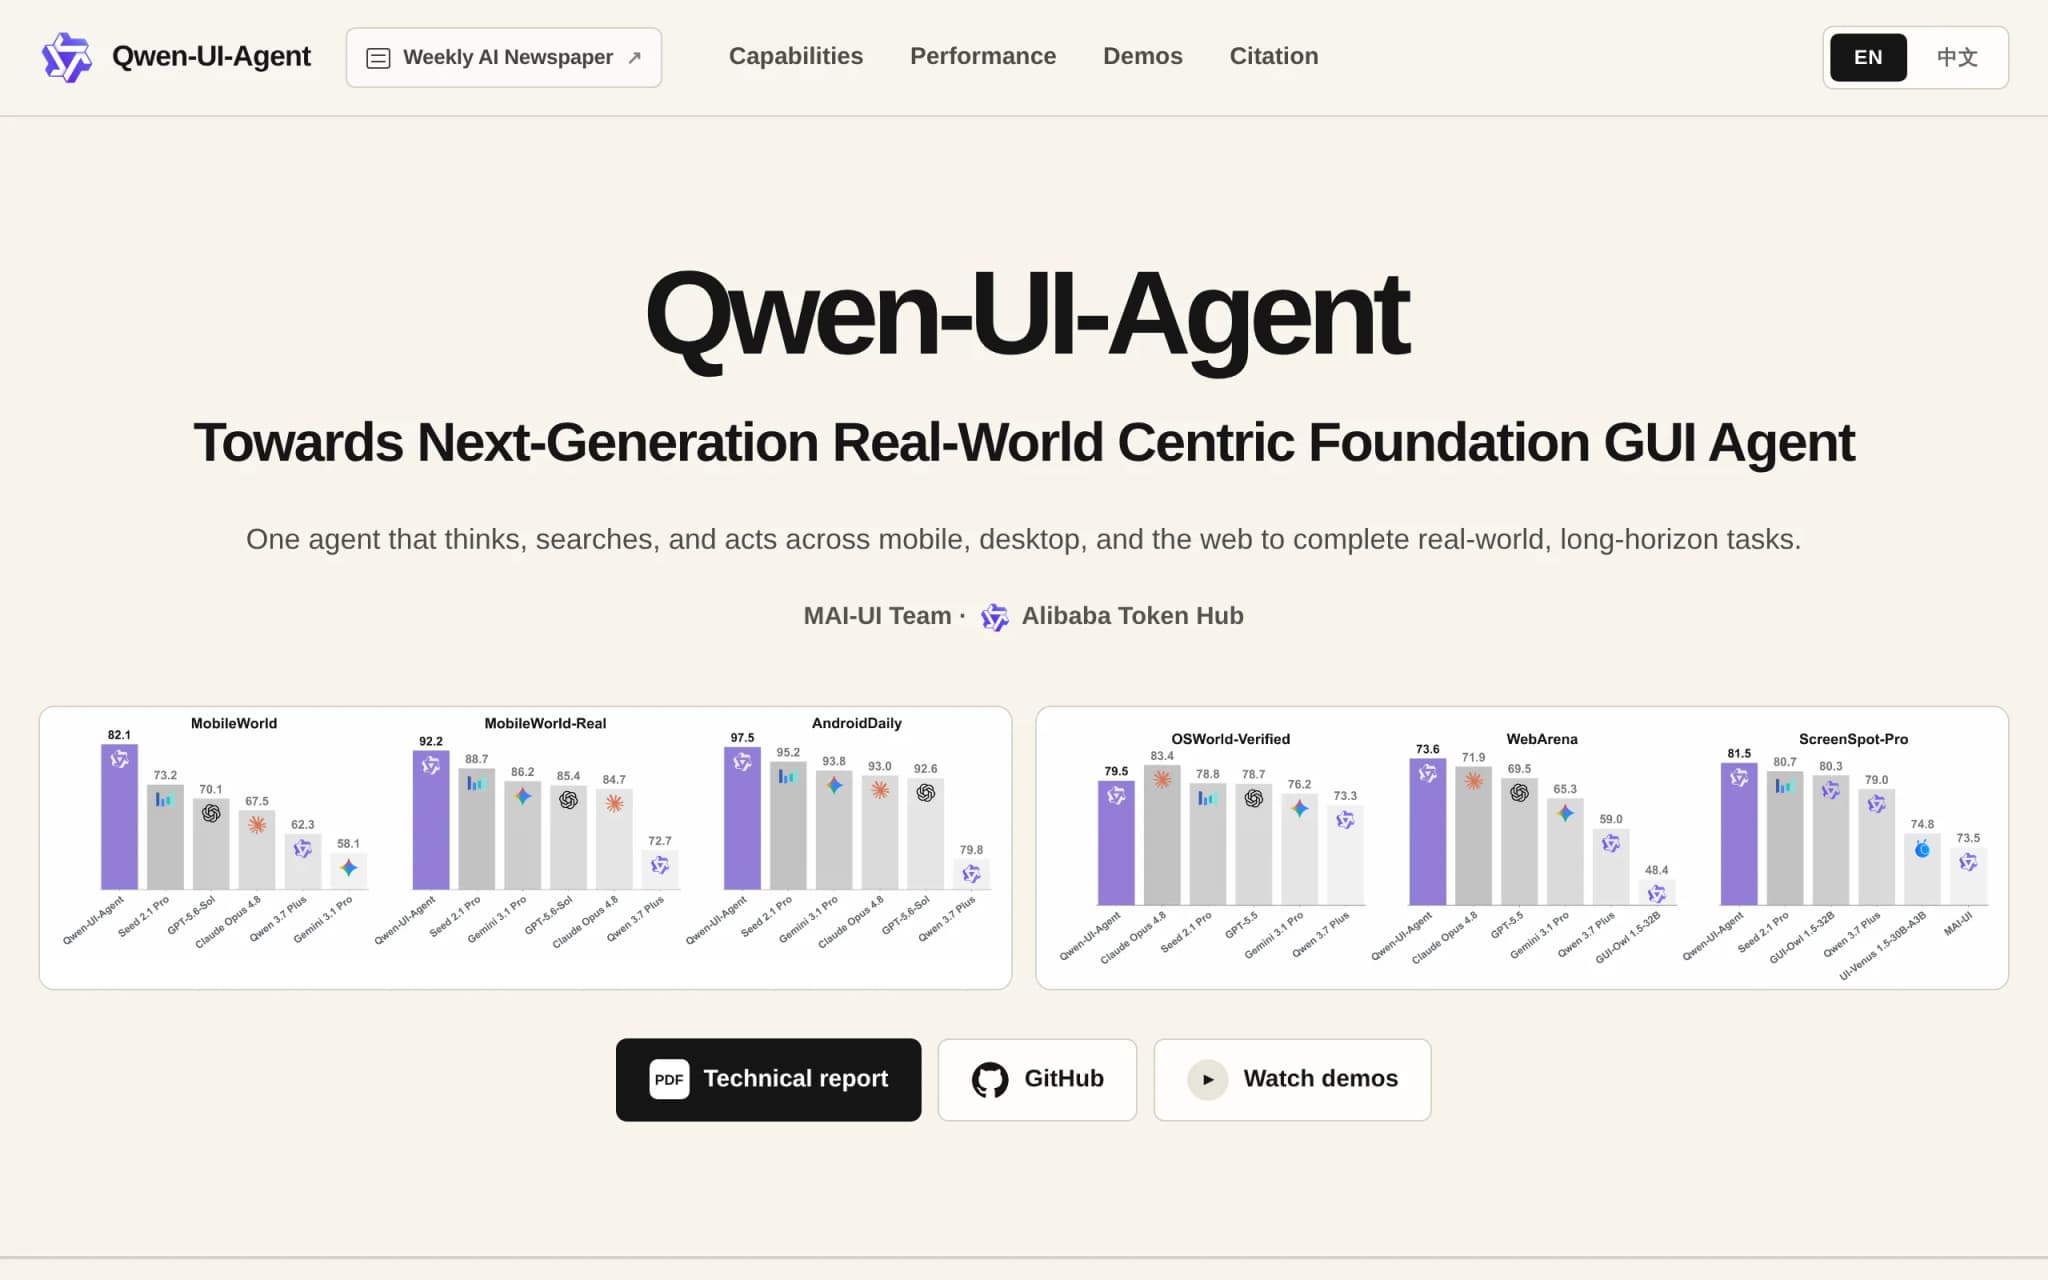
Qwen-UI-Agent – The GUI Agent Foundation Model Launched by Alibaba Tongyi
Qwen-UI-Agent is a GUI agent foundation model launched by the Alibaba Tongyi team, capable of operating interfaces on mobile phones, computers, and web browsers just like a real person. Trained on a r...
WeLM – WeChat's Self-Developed Large Language Model
WeLM (WeChat Language Model) is a large language model self-developed by the WeChat team, now iterated to version V4. The model employs a highly sparse MoE (Mixture of Experts) architecture, with a pa...
HiDream-O1-World – A Full-Modal Interactive World Model from HiDream.ai
HiDream-O1-World is a full-modal interactive world model launched by HiDream.ai, built upon its proprietary UiT architecture. This model supports multi-modal inputs such as text, images, and interacti...
GLM-5.3 – Zhipu AI's Most Open-Source Foundation Model, Programming Ability Improved by 50%
GLM-5.3 is the latest open-source foundation model from Zhipu AI. Built upon the same foundation architecture as GLM-5.2, it significantly enhances its intelligence ceiling through advanced post-train...
MiniMax Music 3.0 – MiniMax's Open-Weight Music Generation Model
MiniMax Music 3.0 is the next-generation open-weight music generation model introduced by MiniMax. The model employs a hierarchical architecture combining an 8B Global LLM and a 0.6B Local LLM, and in...
In-Depth Review of Grok 4.6: The Triangular Balance of Performance, Speed, and Cost-Effectiveness in the Flagship Model
Grok 4.6 is the latest generation flagship large language model launched by SpaceXAI (xAI), based on a 1.5T parameter Mixture-of-Experts (MoE) architecture, with an ultra-long context window of 500K t...
LTX-2.5 – LTX's Open-Source AI Video Generation Foundation Model
LTX-2.5 is a professional-grade AI video generation foundation model open-sourced by Lightricks, an Israeli AI company. With 220 billion parameters, it provides full model weights upon release. The mo...
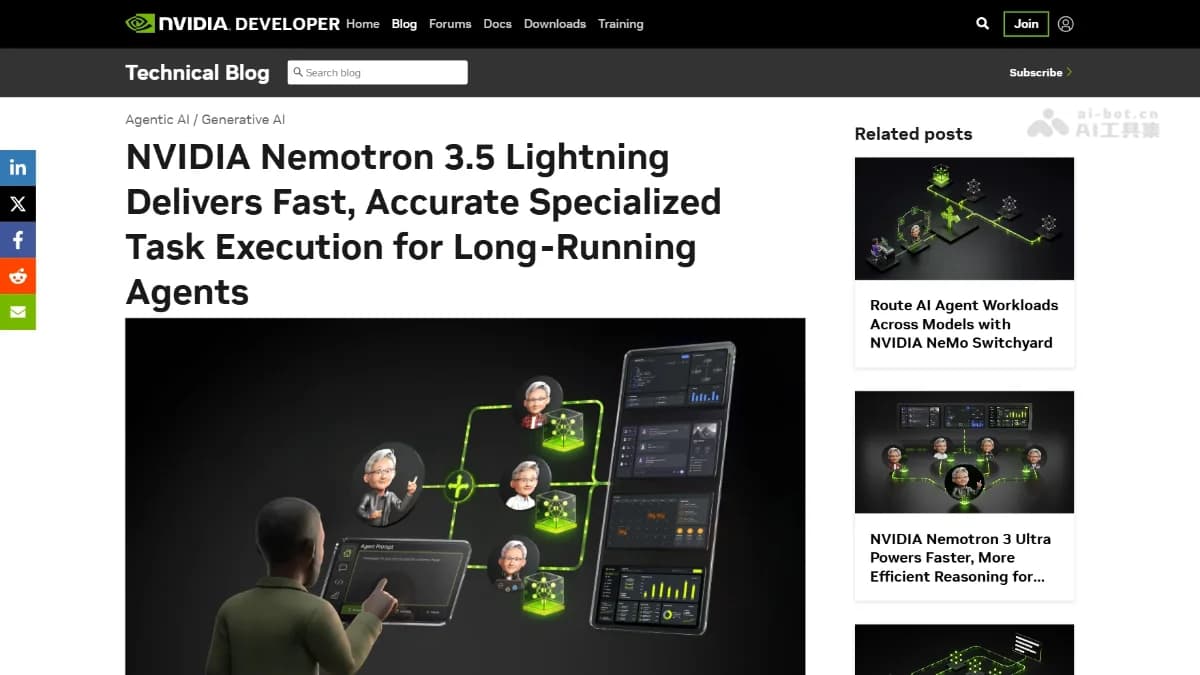
Nemotron 3.5 Lightning – NVIDIA's Open-Source MoE Model
Nemotron 3.5 Lightning is an open-source Mixture-of-Experts (MoE) model with 30B parameters launched by NVIDIA, specifically optimized for multi-agent systems. The model employs a sparse activation ar...
Wan-Animate-2 – The Next-Generation Character Animation Model Open-Sourced by WanXiang Team
Wan-Animate-2 is the next-generation character animation model open-sourced by the WanXiang team, representing a major architectural upgrade from Wan-Animate. It employs an end-to-end dual-branch Diff...
Ling-3.0-tiny – Ant Ling's Native Hybrid Inference Model
Ling-3.0-tiny is a native hybrid inference model introduced by the Ant Ling team, utilizing a sparse mixture-of-experts architecture (MoE). With a total of 7.9B parameters, it activates only 1.3B para...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.