
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Image Generation
41 article(s) found · Clear tag
Rodin Gen-2.5 – Hyper3D's 10M-Polygon AI 3D Model Generator
Rodin Gen-2.5 from Hyper3D (影眸科技) is marketed as the first commercial AI 3D tool to generate 10M+ polygons directly, built on SIGGRAPH 2025 Best Paper technology. Text, single-image, or multi-view inp...

Qwen-Image-Bench – Qwen Team's Text-to-Image Model Evaluation Benchmark
Qwen-Image-Bench is a standardized benchmark dataset from Alibaba's Qwen team (Tongyi Qianwen) for evaluating text-to-image models—1,000 carefully designed test samples covering Chinese and English pr...
MAI-Image-2.5 – Microsoft's Flagship Text-to-Image Model
MAI-Image-2.5 is a flagship text-to-image model from Microsoft Research and the strongest release in the MAI-Image family. On the Arena text-to-image leaderboard it climbed to #3 with 1,254 points—72 ...
Image-to-LoRA-V2 – ModelScope's Training-Free Style Transfer Tool
Image-to-LoRA-V2 (i2L-V2) is a training-free style transfer tool open-sourced by ModelScope's DiffSynth-Studio team. Upload 1–8 style-consistent reference images and the model predicts text-to-image L...
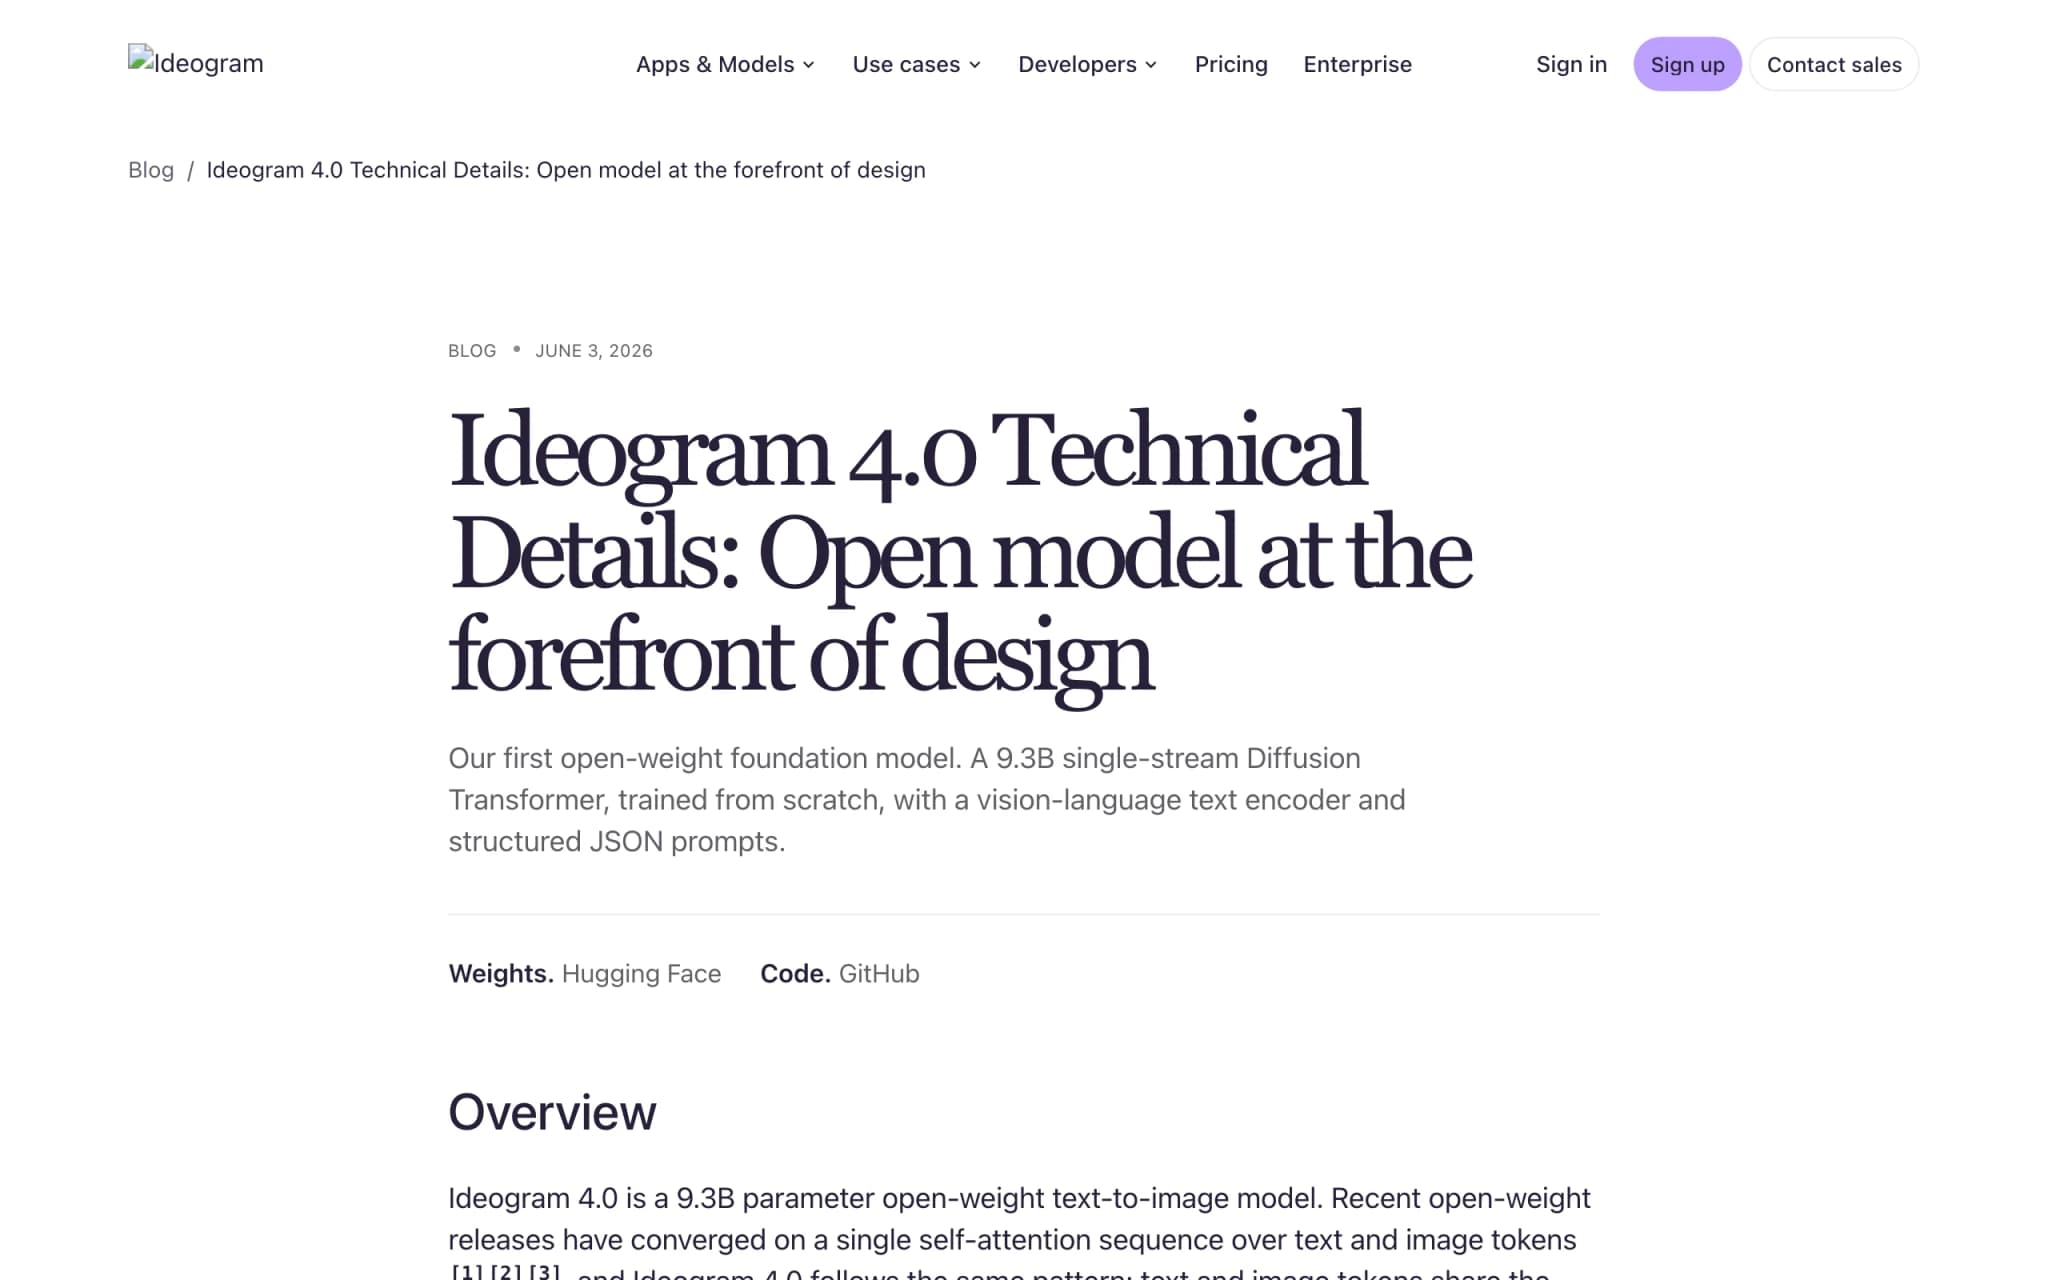
Ideogram 4 – Ideogram's Open-Source Text-to-Image Model for Design
Ideogram 4 is Ideogram's first open text-to-image model—9.3B parameters, trained from scratch rather than fine-tuned from an existing checkpoint. Built for high-quality design, marketing graphics, log...
HiDream-O1-Image-1.5 – HiDream.ai’s Commercial Image Generation Model
HiDream-O1-Image-1.5 is a commercial-grade text-to-image model from HiDream.ai (智象未来), built on the proprietary native unified-modality UiT (Unified Transformer) architecture. It scores ELO 1265 on Ar...
Guizang Social Card Skill – Open-Source Xiaohongshu & WeChat Image Card Skill
Guizang Social Card Skill is an open-source skill by independent developer Guizang (op7418) for Claude Code, Codex, and similar AI agent environments. It generates magazine-quality social image cards ...
EvoQuality – ByteDance's Open-Source Self-Evolving Image Quality Assessment Model
EvoQuality is a self-evolving vision-language model framework jointly developed by ByteDance and City University of Hong Kong, focused on no-reference image quality assessment (NR-IQA). Built on Qwen2...
DiffusionGemma – Google’s Experimental Open-Source Text Diffusion Model
DiffusionGemma is an experimental open-source text diffusion model from Google DeepMind, built on Gemma 4 architecture and Gemini Diffusion research. The 26B-parameter MoE design denoises 256-token te...
Bernini – ByteDance's Open-Source Unified Video Generation and Editing Framework
Bernini is ByteDance's open-source unified video generation and editing framework using a two-stage decoupled architecture: multimodal large language model (MLLM) semantic planning plus Diffusion Tran...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.