
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Speech AI
115 article(s) found · Clear tag
Qwen3.8-LiveTranslate – A Real-Time Simultaneous Interpretation Model Launched by Alibaba Tongyi
Qwen3.8-LiveTranslate is a real-time simultaneous interpretation large model launched by the Tongyi Qianwen team at Alibaba. Based on the Interleave single-stream architecture, it processes audio and ...
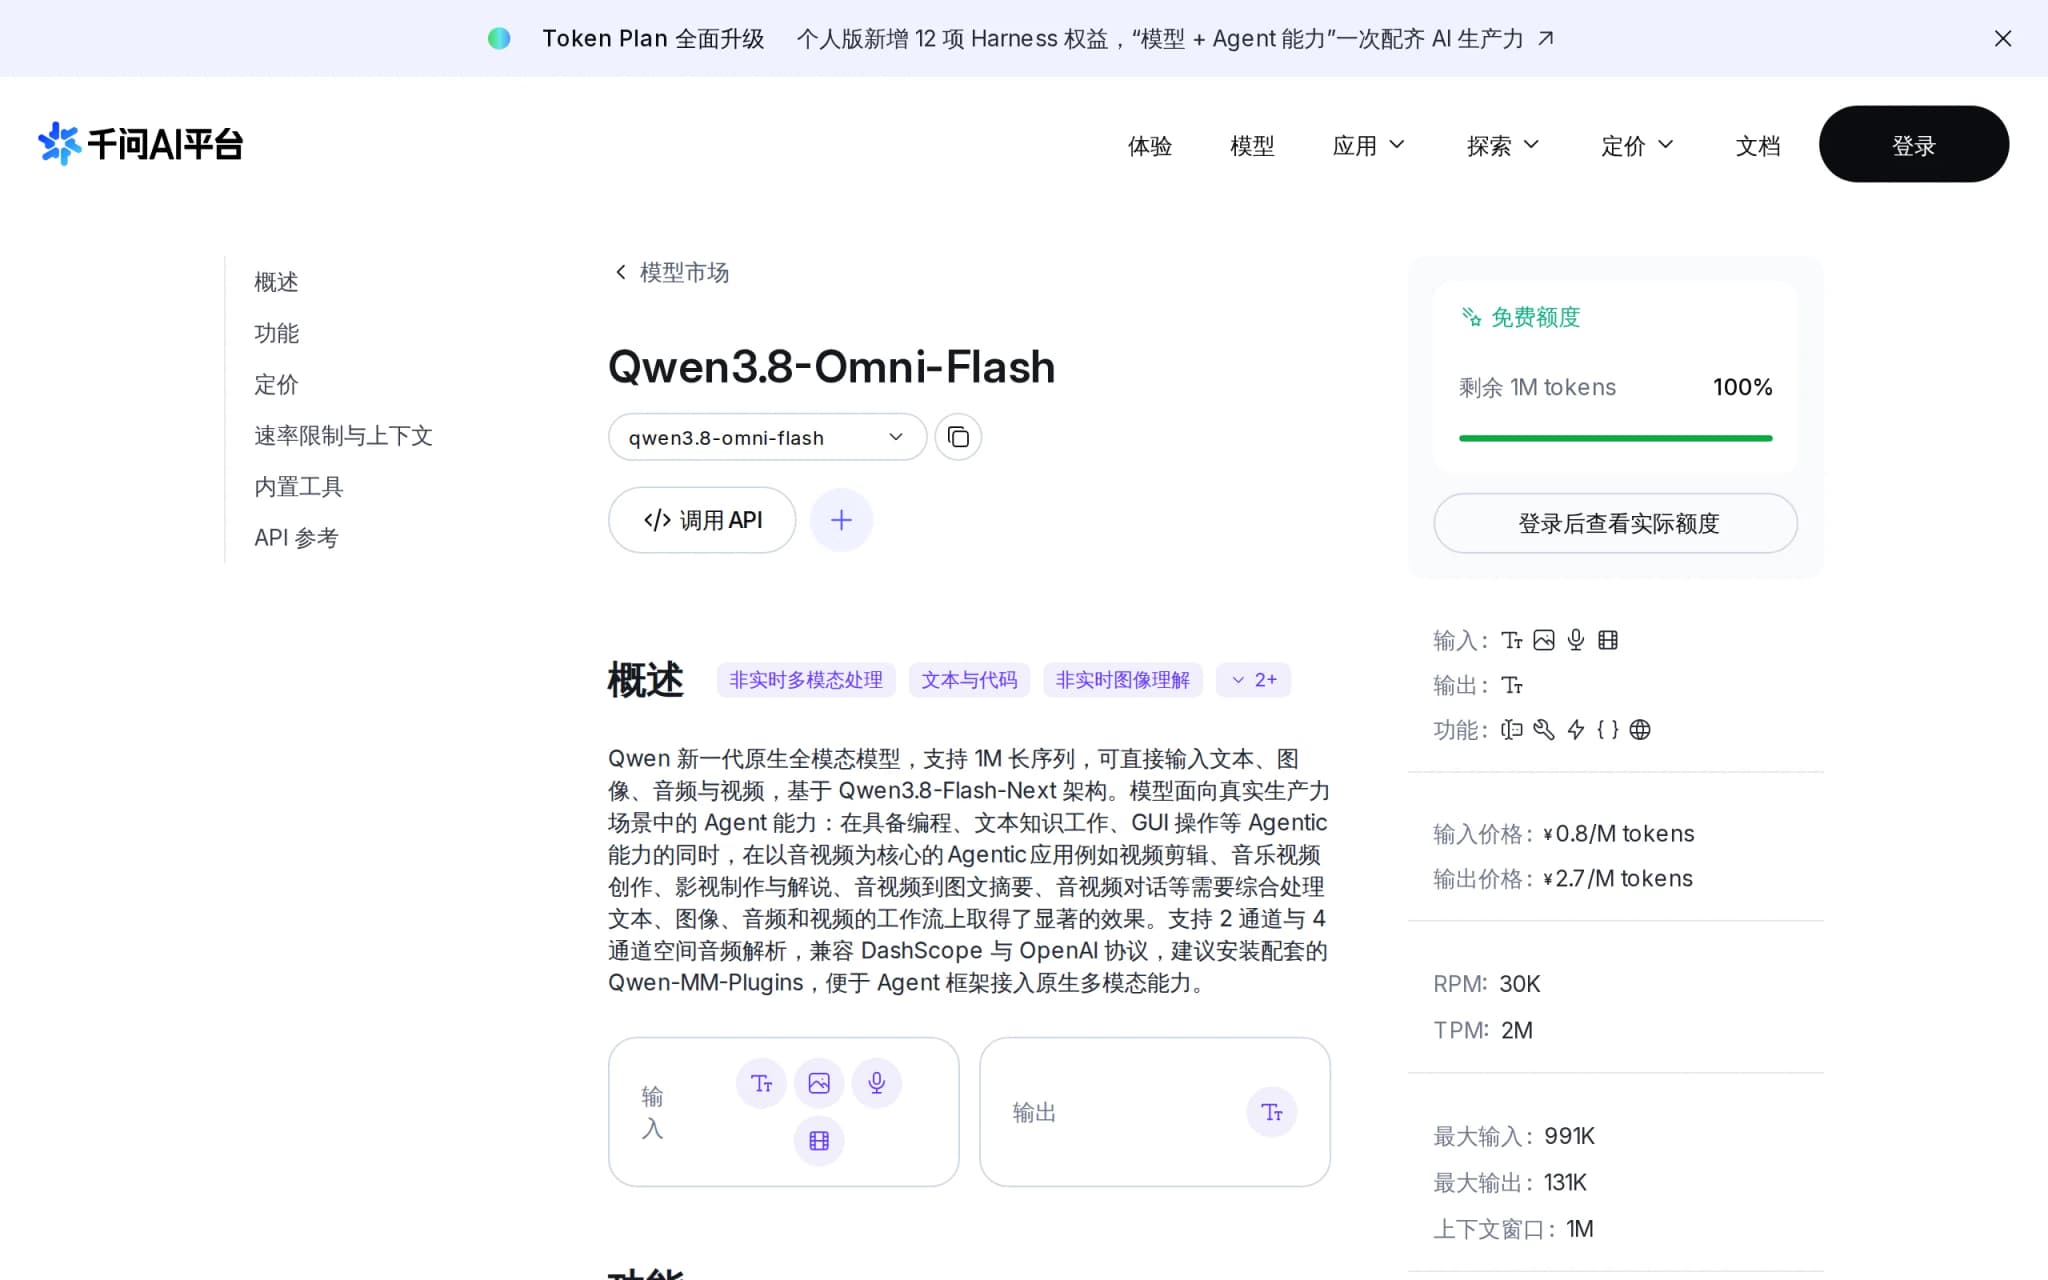
Qwen3.8-Omni-Flash – A Native Multimodal Model Launched by Alibaba Qwen
Qwen3.8-Omni-Flash is a native multimodal model launched by Alibaba Qwen. It jointly models four modalities—text, image, audio, and video—within a single architecture, supporting a context length of u...
Hypit – Open-Source AI Video Generation Tool, Automatically Replicates Viral Videos
Hypit is an open-source AI video generation tool, centered on the methodology of "Provide an Agent with a viral video, and it will automatically replicate the entire workflow." It breaks down viral vi...
Spark-Audio-1.0-Preview – iFLYTEK's Domestic-Developed Speech Foundation Model
Spark-Audio-1.0-Preview is a fully domestically developed speech foundation model launched by iFLYTEK. It employs a 0.65B audio encoder and a 30B-A3B MoE language model architecture, trained on 13 mil...
In-Depth Review of Gemini 3.8 Live – Google's Native Real-Time Speech Dialogue Model
Gemini 3.8 Live is a series of native real-time speech dialogue models launched by Google, which includes two variants: Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking. This series employs an en...
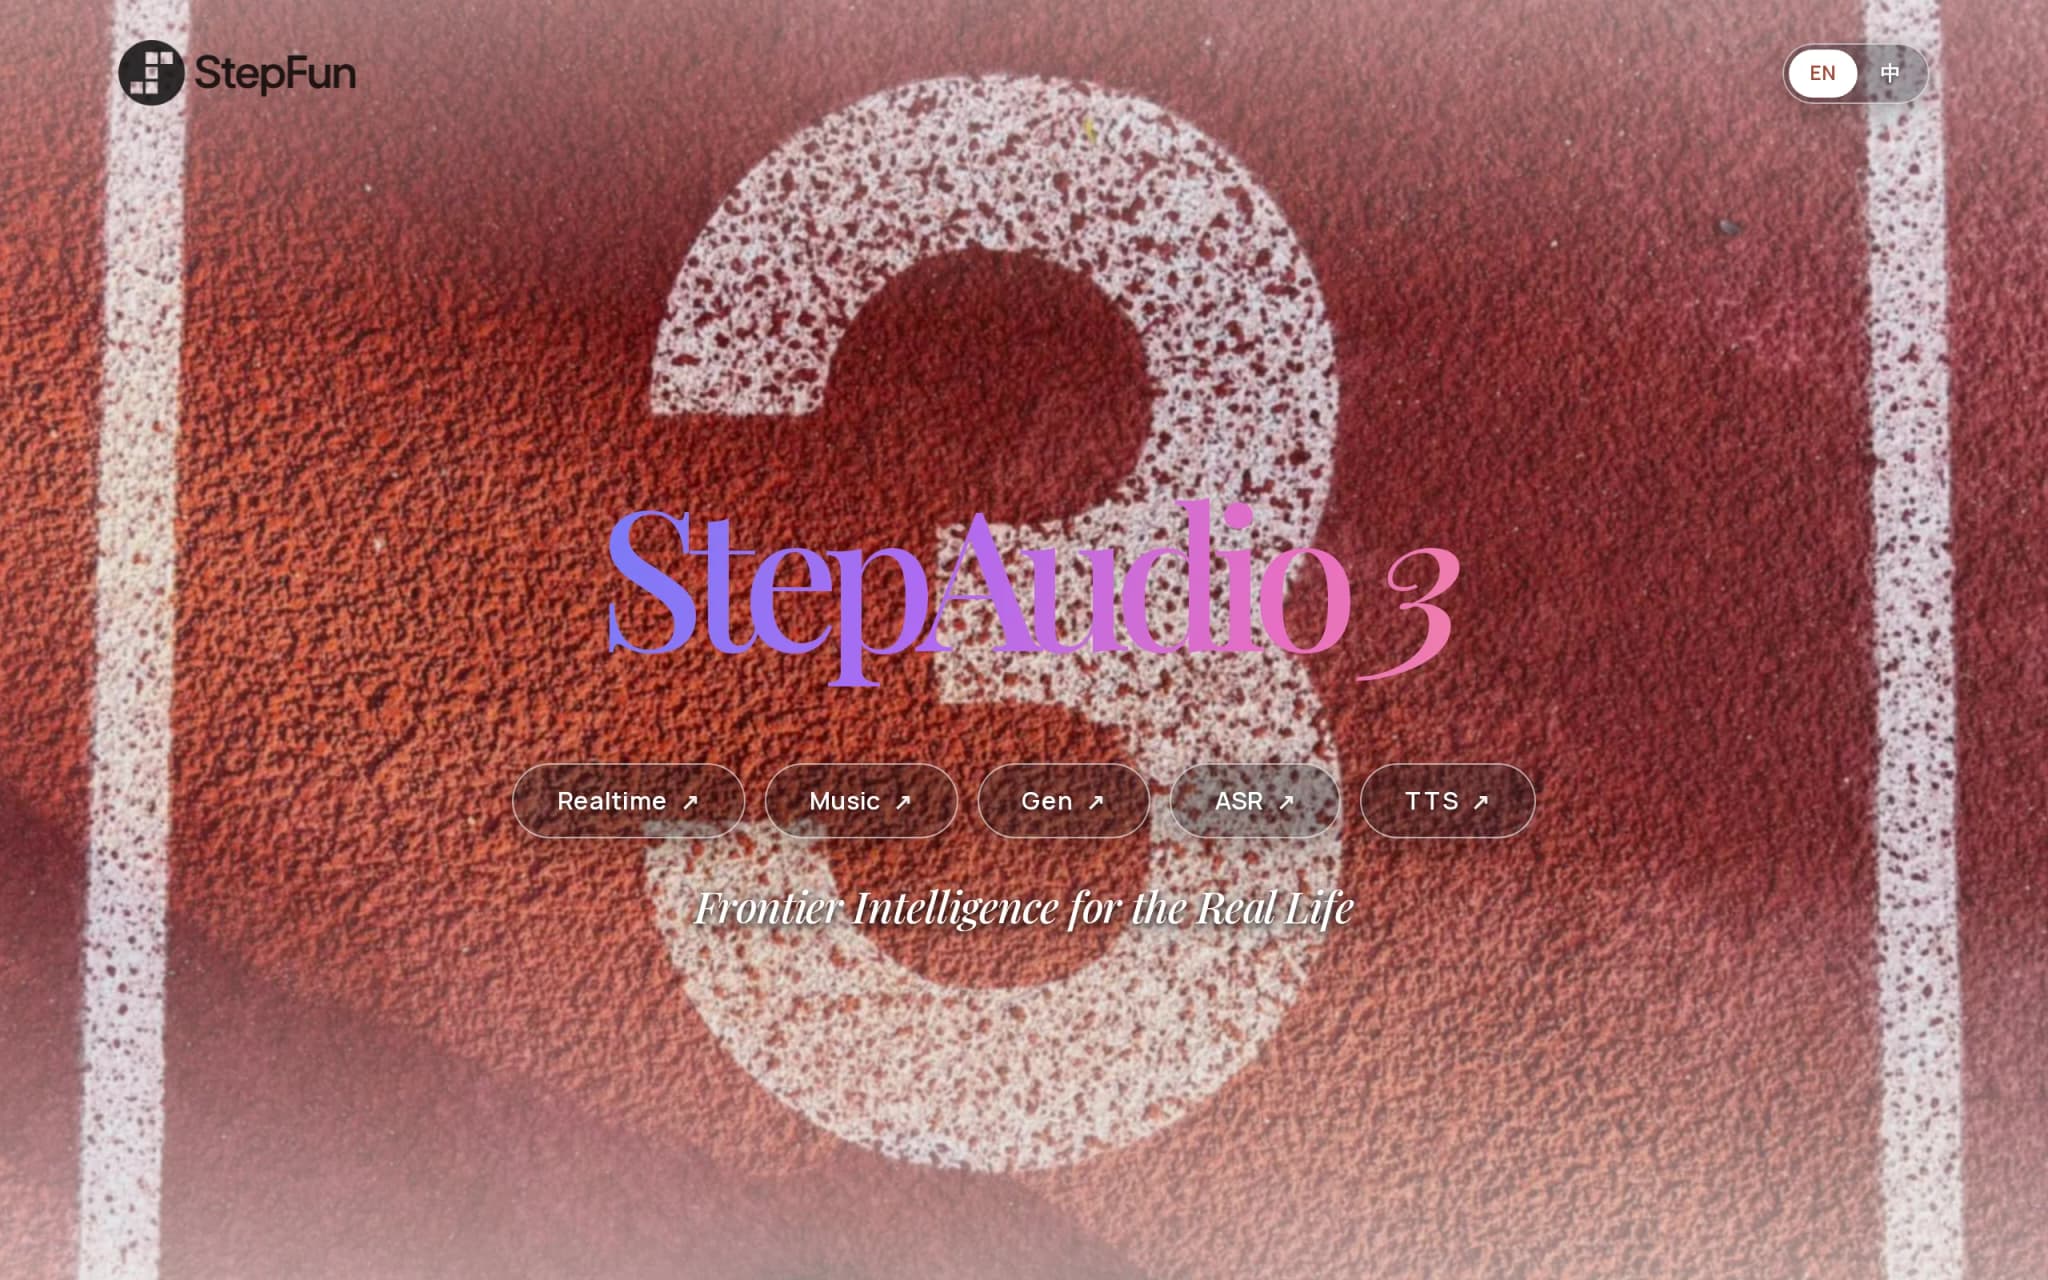
Step Audio 3 – StepFun's Voice Large Model Series
Step Audio 3 is a new generation of voice large model series introduced by StepFun. It derives five specialized models—Realtime, ASR, TTS, Gen, and Music—from a single technical foundation, covering t...
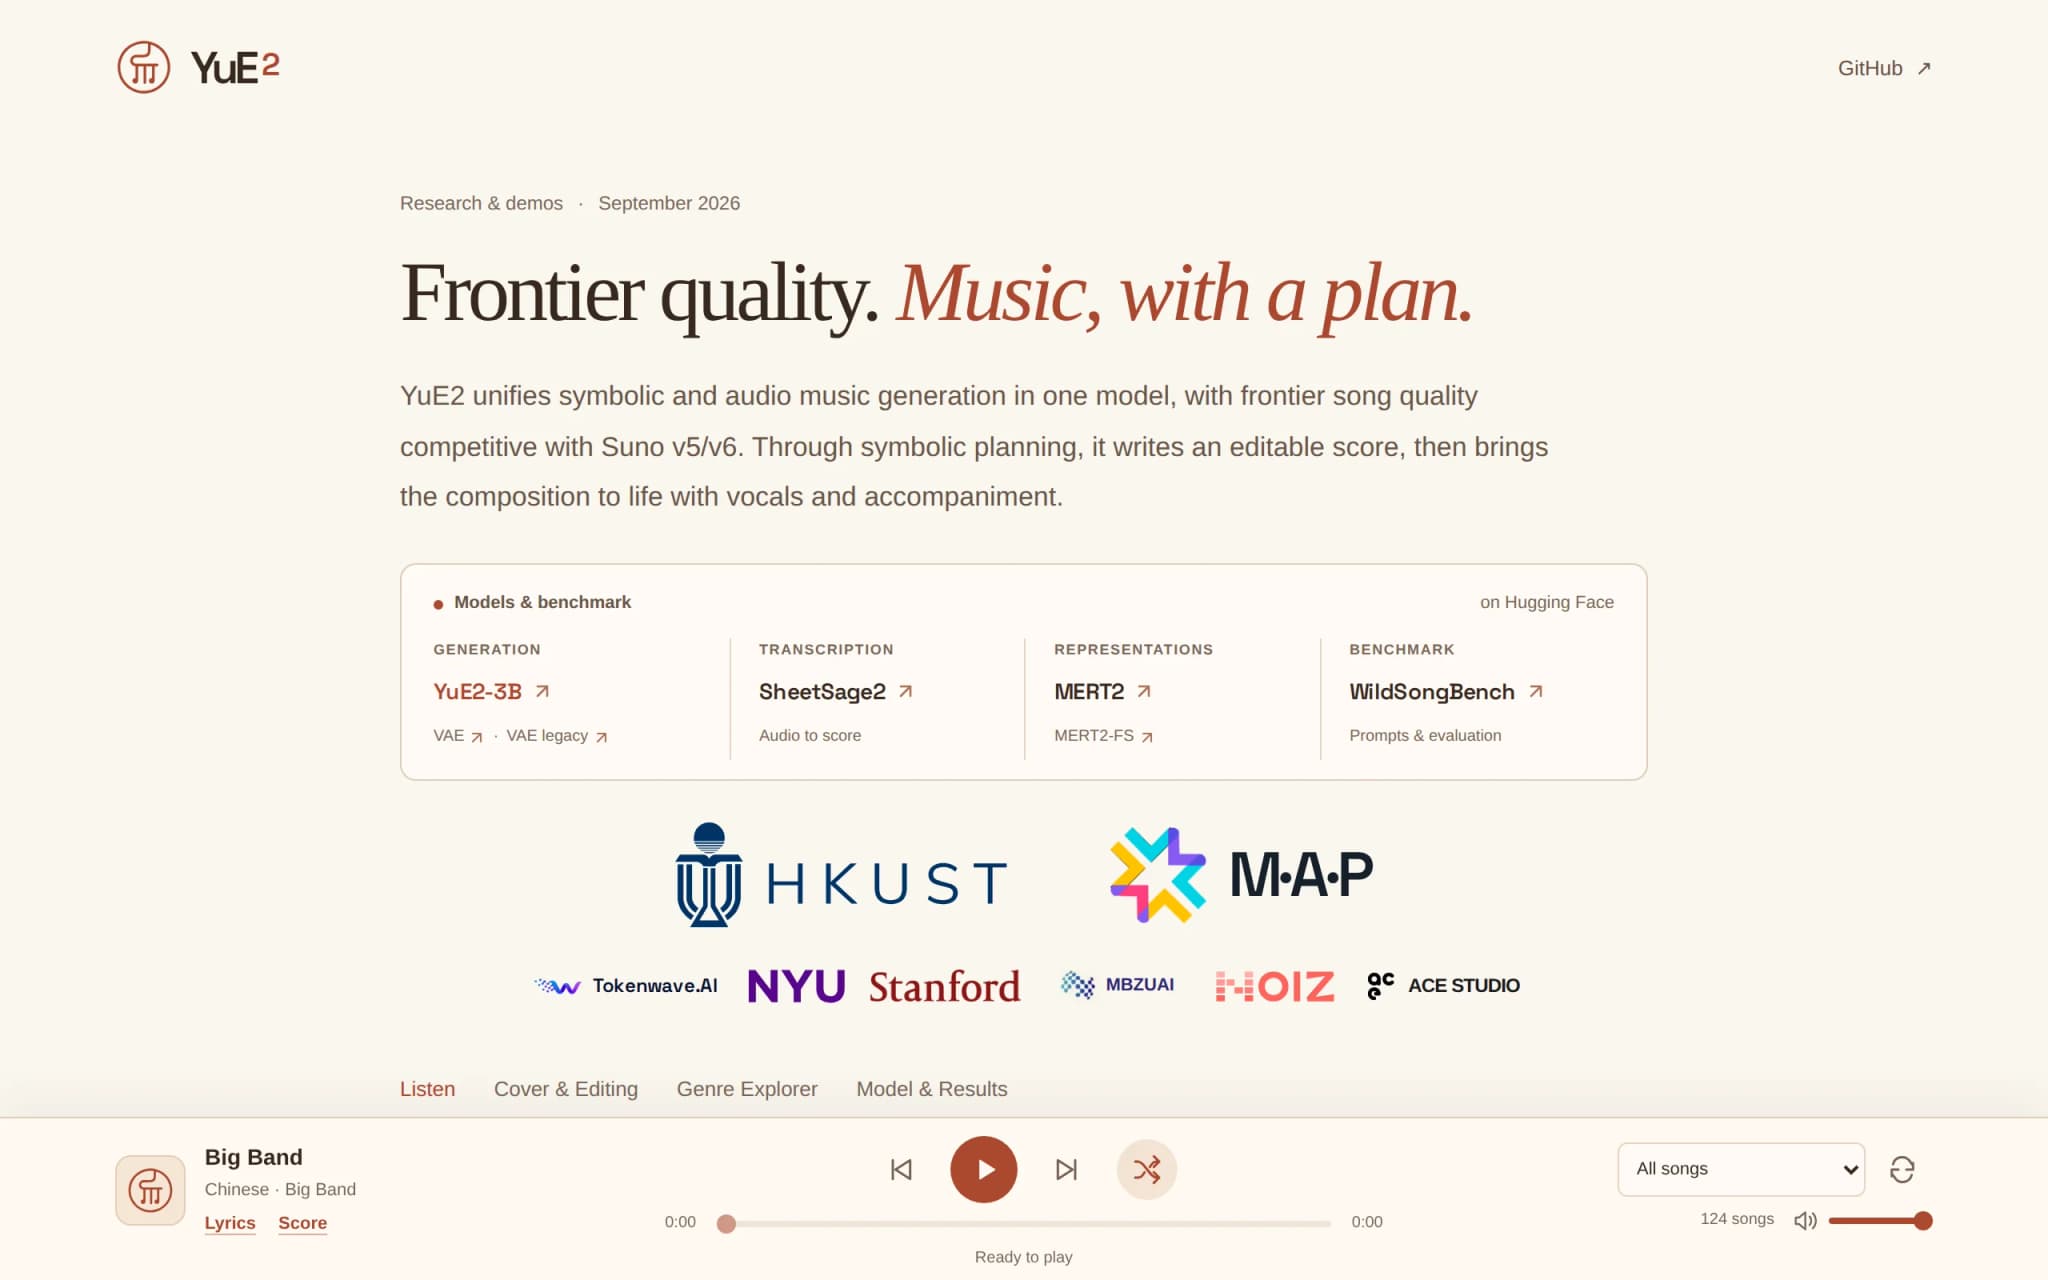
YuE2: In-Depth Evaluation of the Symbolic Planning-Based Music Generation Model Open-Sourced by Hong Kong University of Science and Technology and the M-A-P Team
YuE2 is an open-source music generation model jointly developed by the Hong Kong University of Science and Technology and the M-A-P team. Its core design concept introduces an explicit symbolic musica...
HiDream-O1-Video-1.0: In-Depth Evaluation of a Native Full-Modal Video Generation Model
HiDream-O1-Video-1.0 (shortened as HD-V1) is a native full-modal video generation model launched by HiDream.ai. It supports multi-modal inputs such as text, images, and videos, and can directly genera...
Xiaomi-CocktailASR-1: In-Depth Evaluation of a Target Speaker ASR Model Based on an End-to-End LLM Architecture
Xiaomi-CocktailASR-1 is Xiaomi's open-source Target Speaker ASR (TS-ASR) large model, designed using an end-to-end LLM architecture. It uses a reference speech as a speaker embedding prompt to accurat...
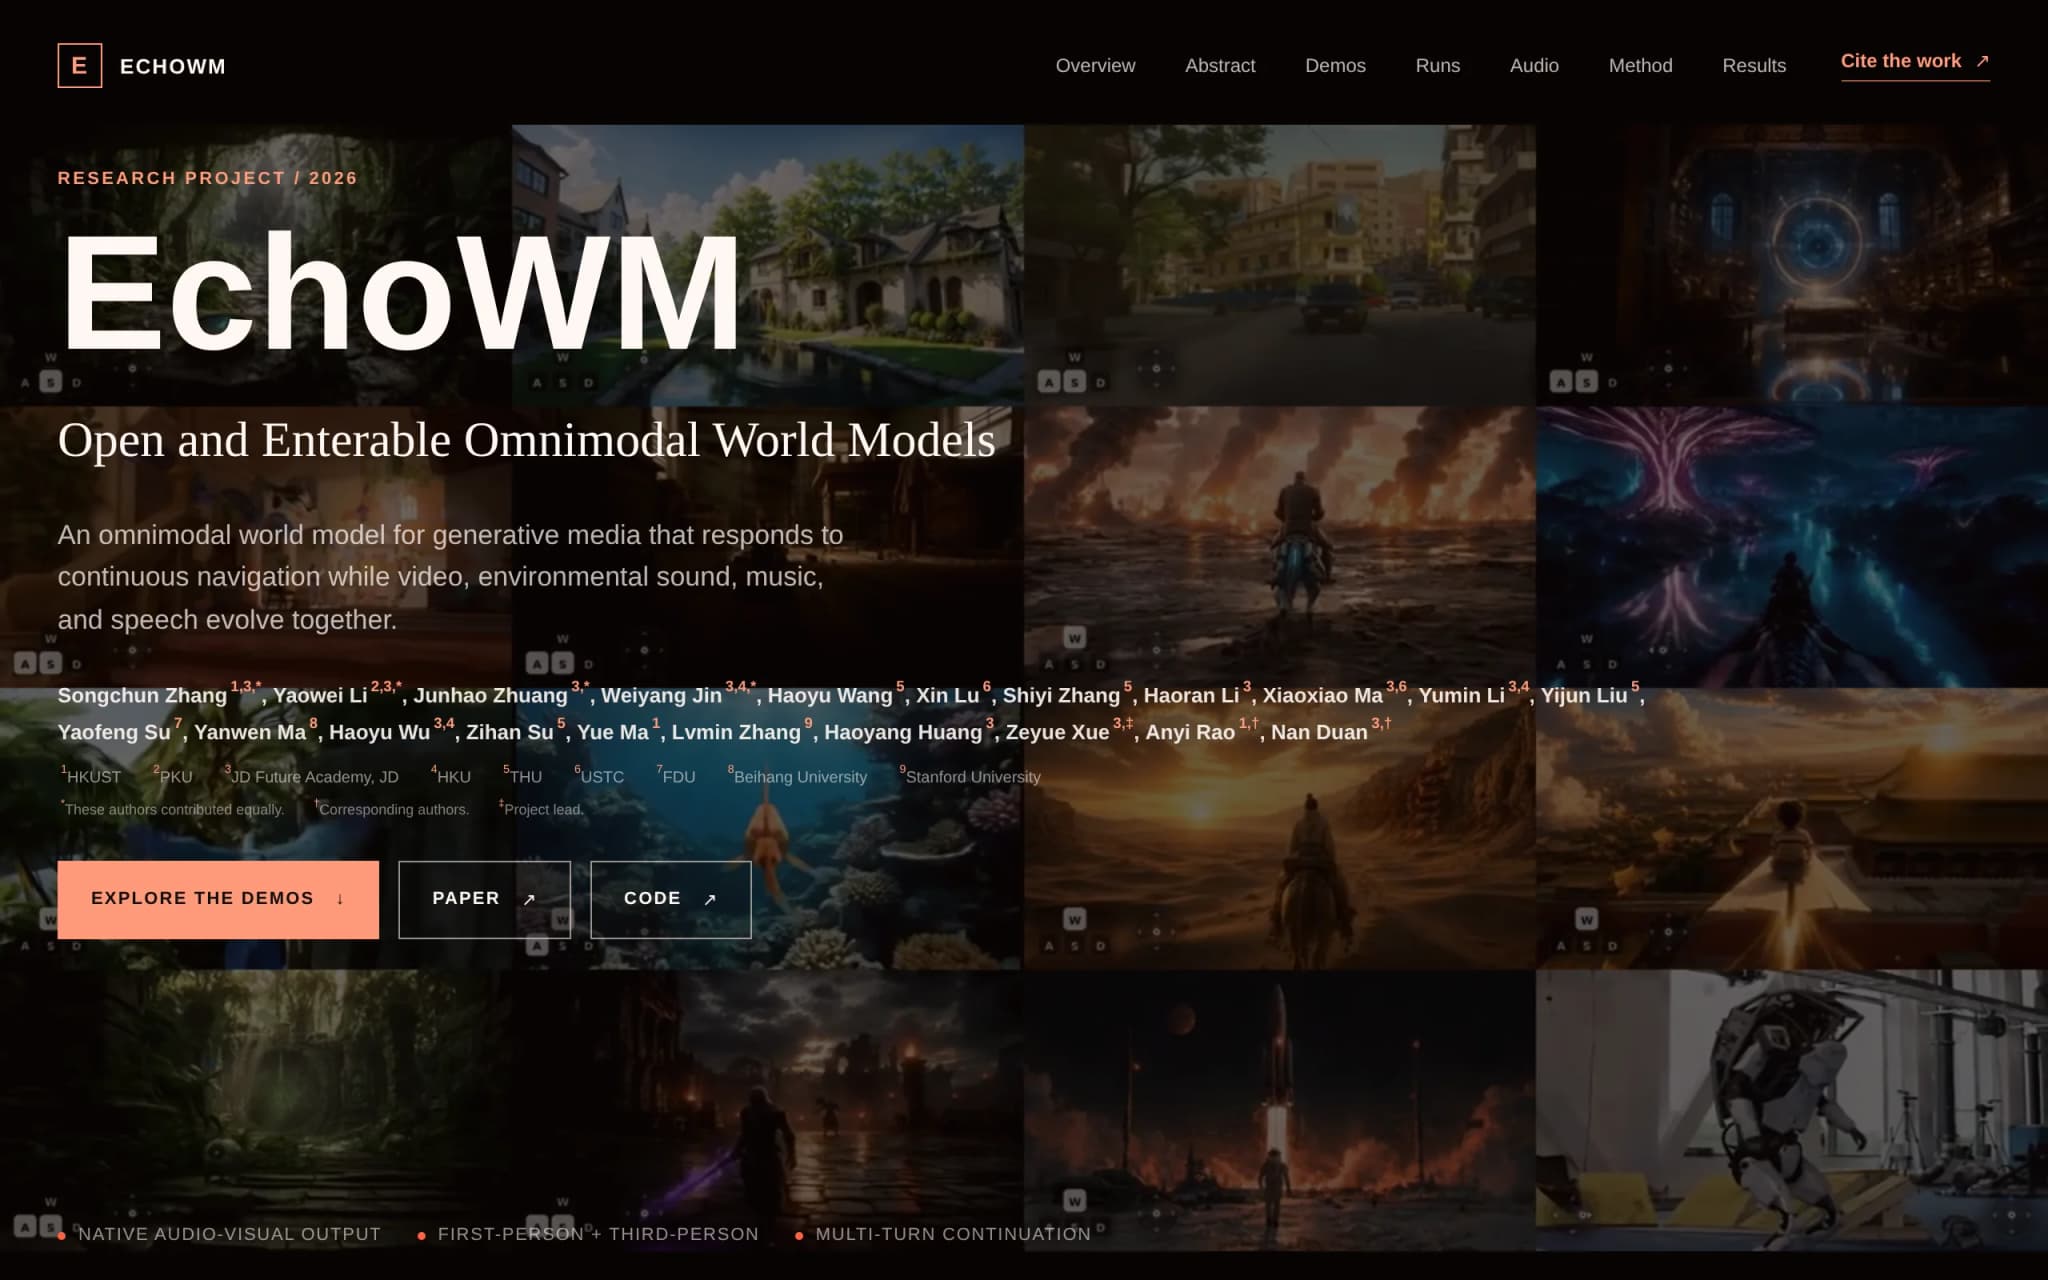
EchoWM – Interactive Audio-Visual World Model Open-Sourced by JD.com
EchoWM is an interactive audio-visual world model open-sourced by the JD.com Exploration Research Institute. It continues the native audio-visual generation capabilities of JoyAI-Echo, allowing users ...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.