
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Speech AI
115 article(s) found · Clear tag
Suno v6 – The Next-Generation Hierarchical Model Series for AI Music Generation
Suno v6 is a new generation of model series introduced by the AI music generation platform Suno. It includes the flagship model v6 (targeted at Pro/Premier paying users), the experimental model v6-wil...
AuK – Tencent HunYuan's Open-Source Foundation Model for Speech Generation and Editing
AuK is an open-source foundation model for speech generation and editing developed by the Tencent HunYuan team, featuring 1.5 billion parameters and utilizing a flow-matching diffusion architecture in...
MiniCPM5-2B – End-to-End Native Audio Modeling Architecture Open-Sourced by RWKV and Tsinghua University
MiniCPM5-2B is an end-side language foundation model open-sourced jointly by RWKV, the OpenBMB community, and Tsinghua University. With approximately 2.5 billion parameters, it supports a context leng...
MiniMax H3 Max: Live-level Speed and Ecosystem Evolution in Real-time Video Generation
MiniMax H3 Max is a real-time video generation model introduced by MiniMax, based on the open-source H3 model, with post-training and inference optimization. This model supports two input methods: tex...
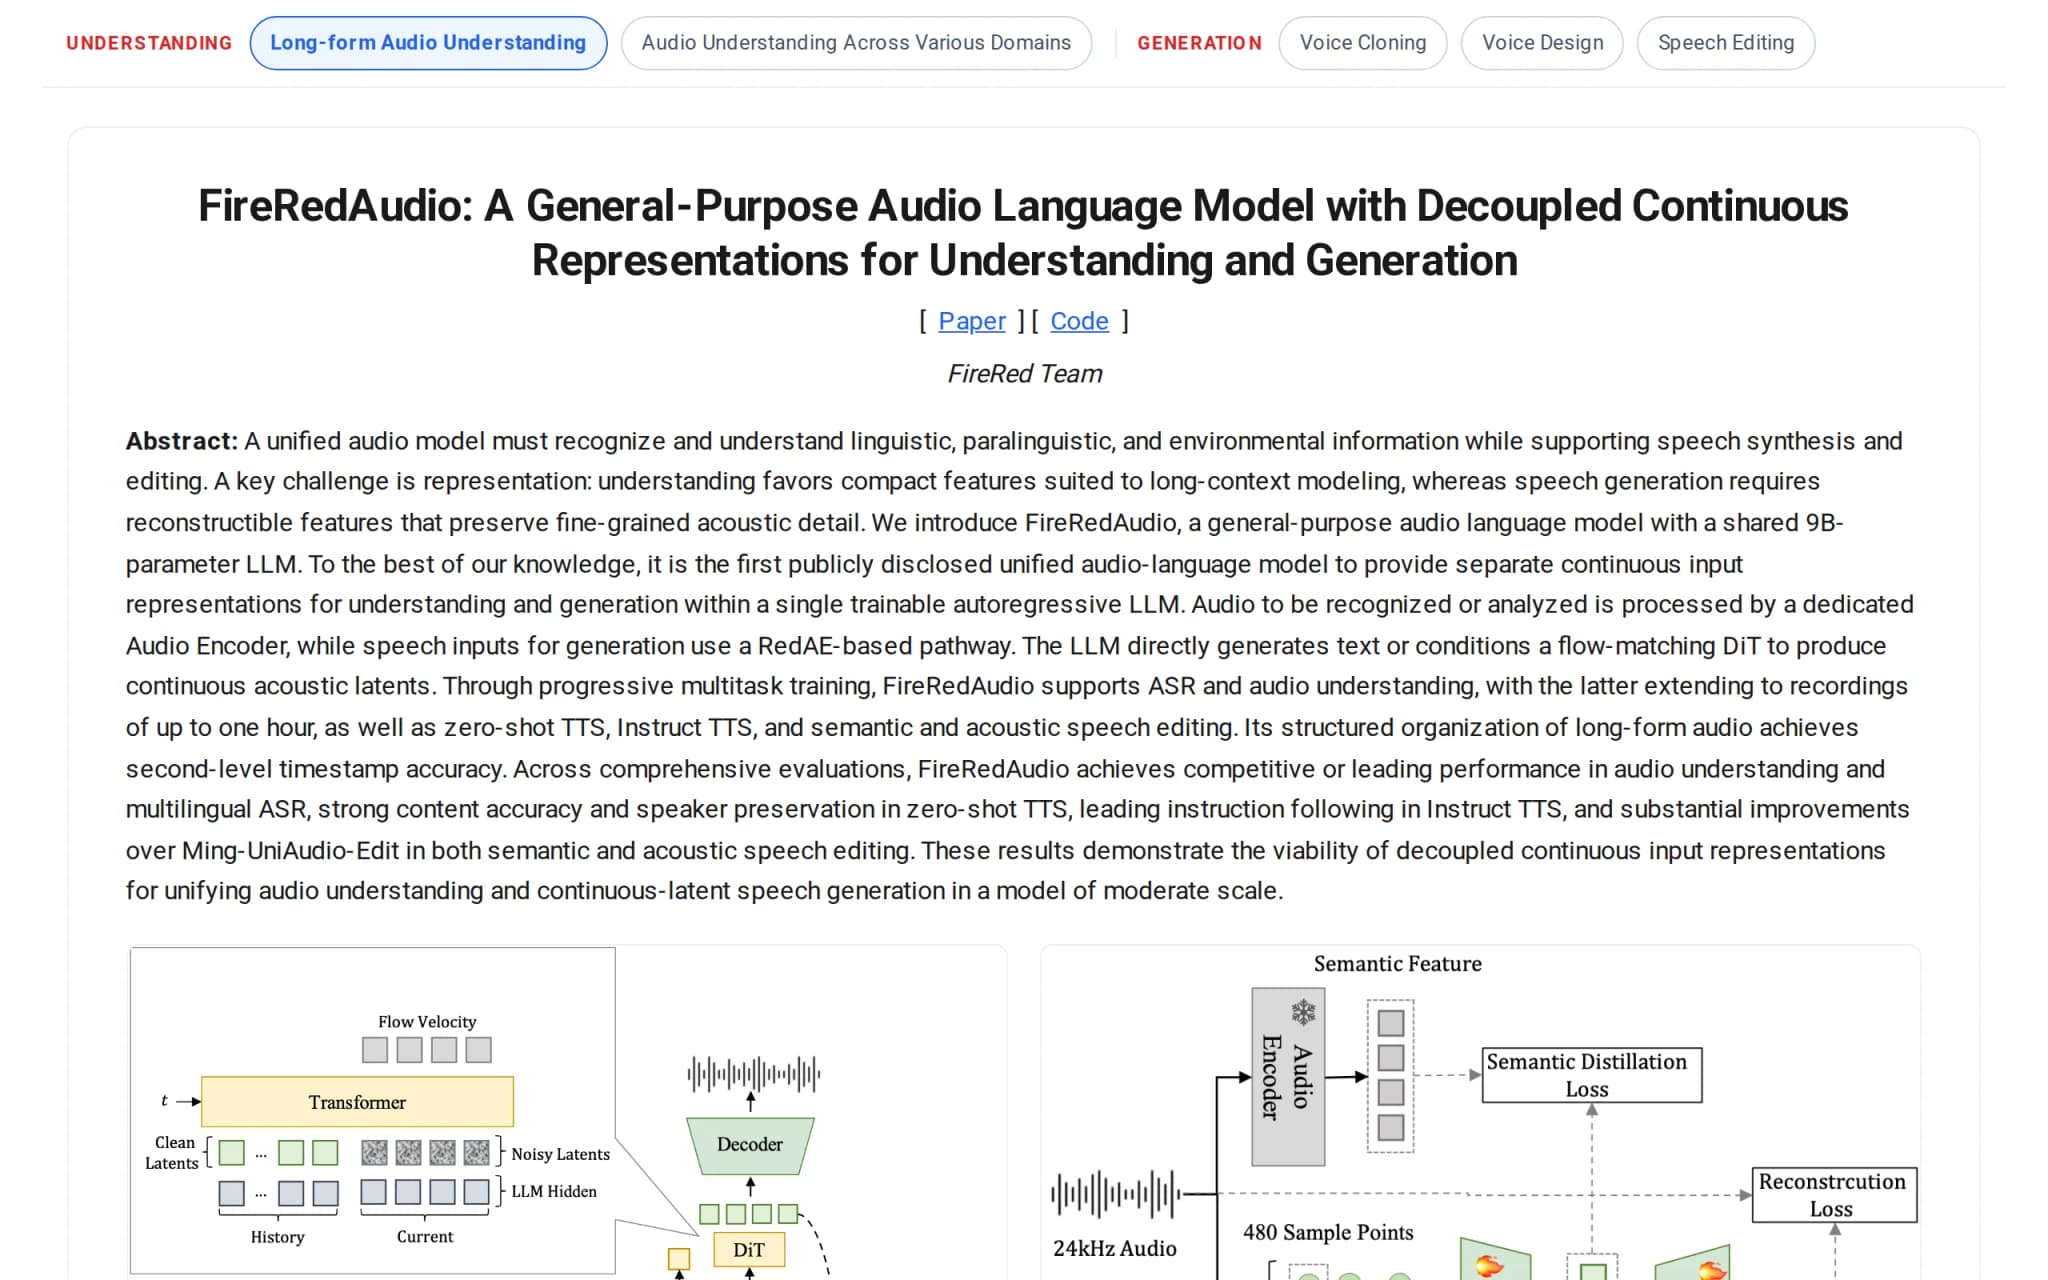
FireRedAudio – In-Depth Review of Xiaohongshu FireRed's General-Purpose Audio Language Model
FireRedAudio is a general-purpose audio language model open-sourced by the FireRed team at Xiaohongshu in August 2026. It is built upon the Qwen3.5 autoregressive large language model with 9B paramete...
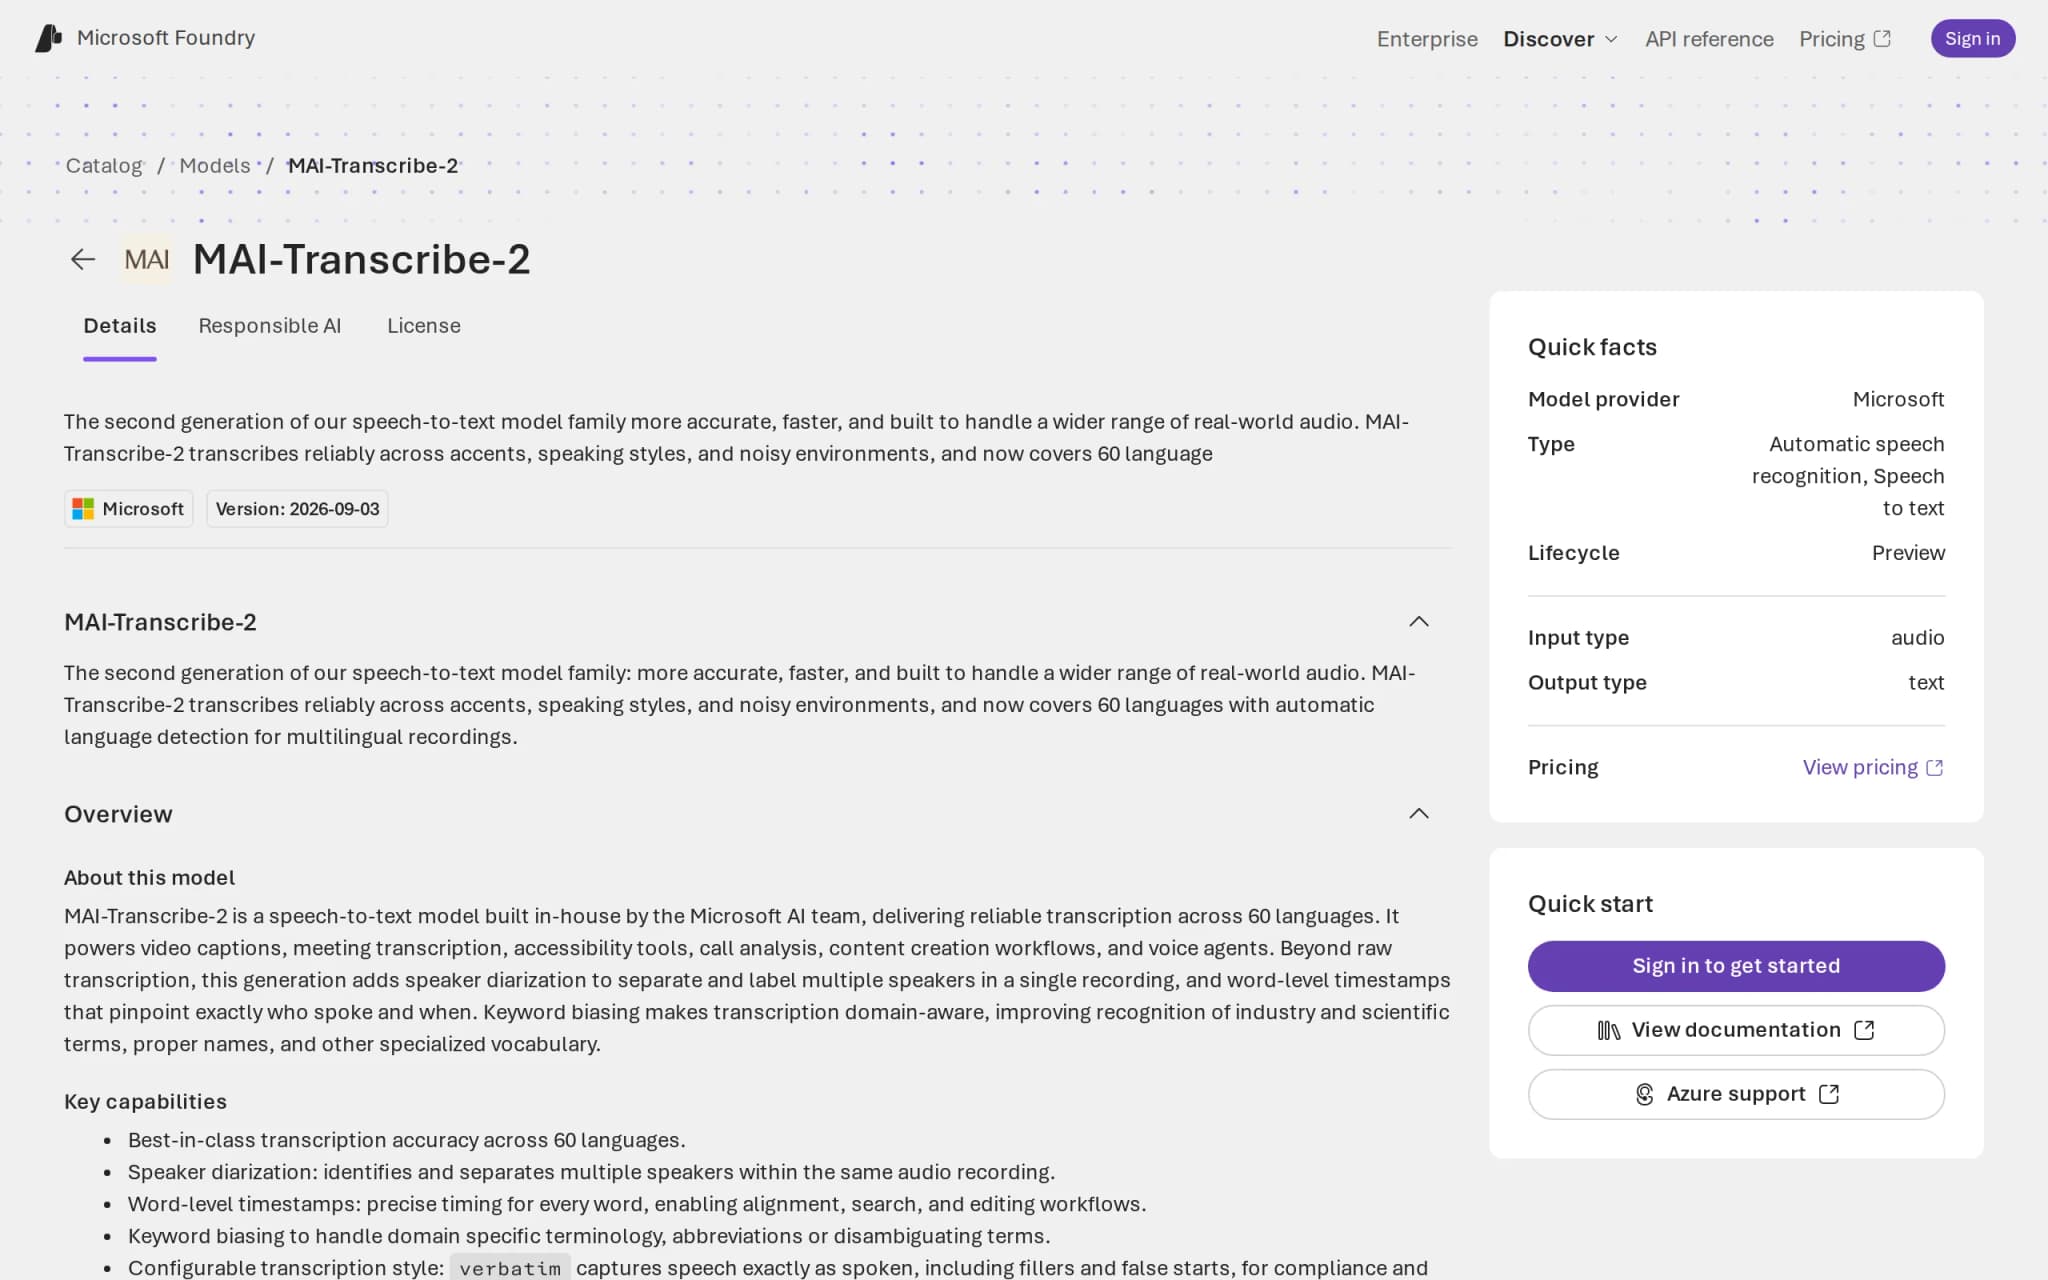
MAI-Transcribe-2 – Microsoft's Most Advanced AI Speech-to-Text Model
MAI-Transcribe-2 is an AI speech-to-text (STT/ASR) model launched by Microsoft, achieving comprehensive leadership in three core dimensions: accuracy, speed, and cost. The model supports 60 languages,...
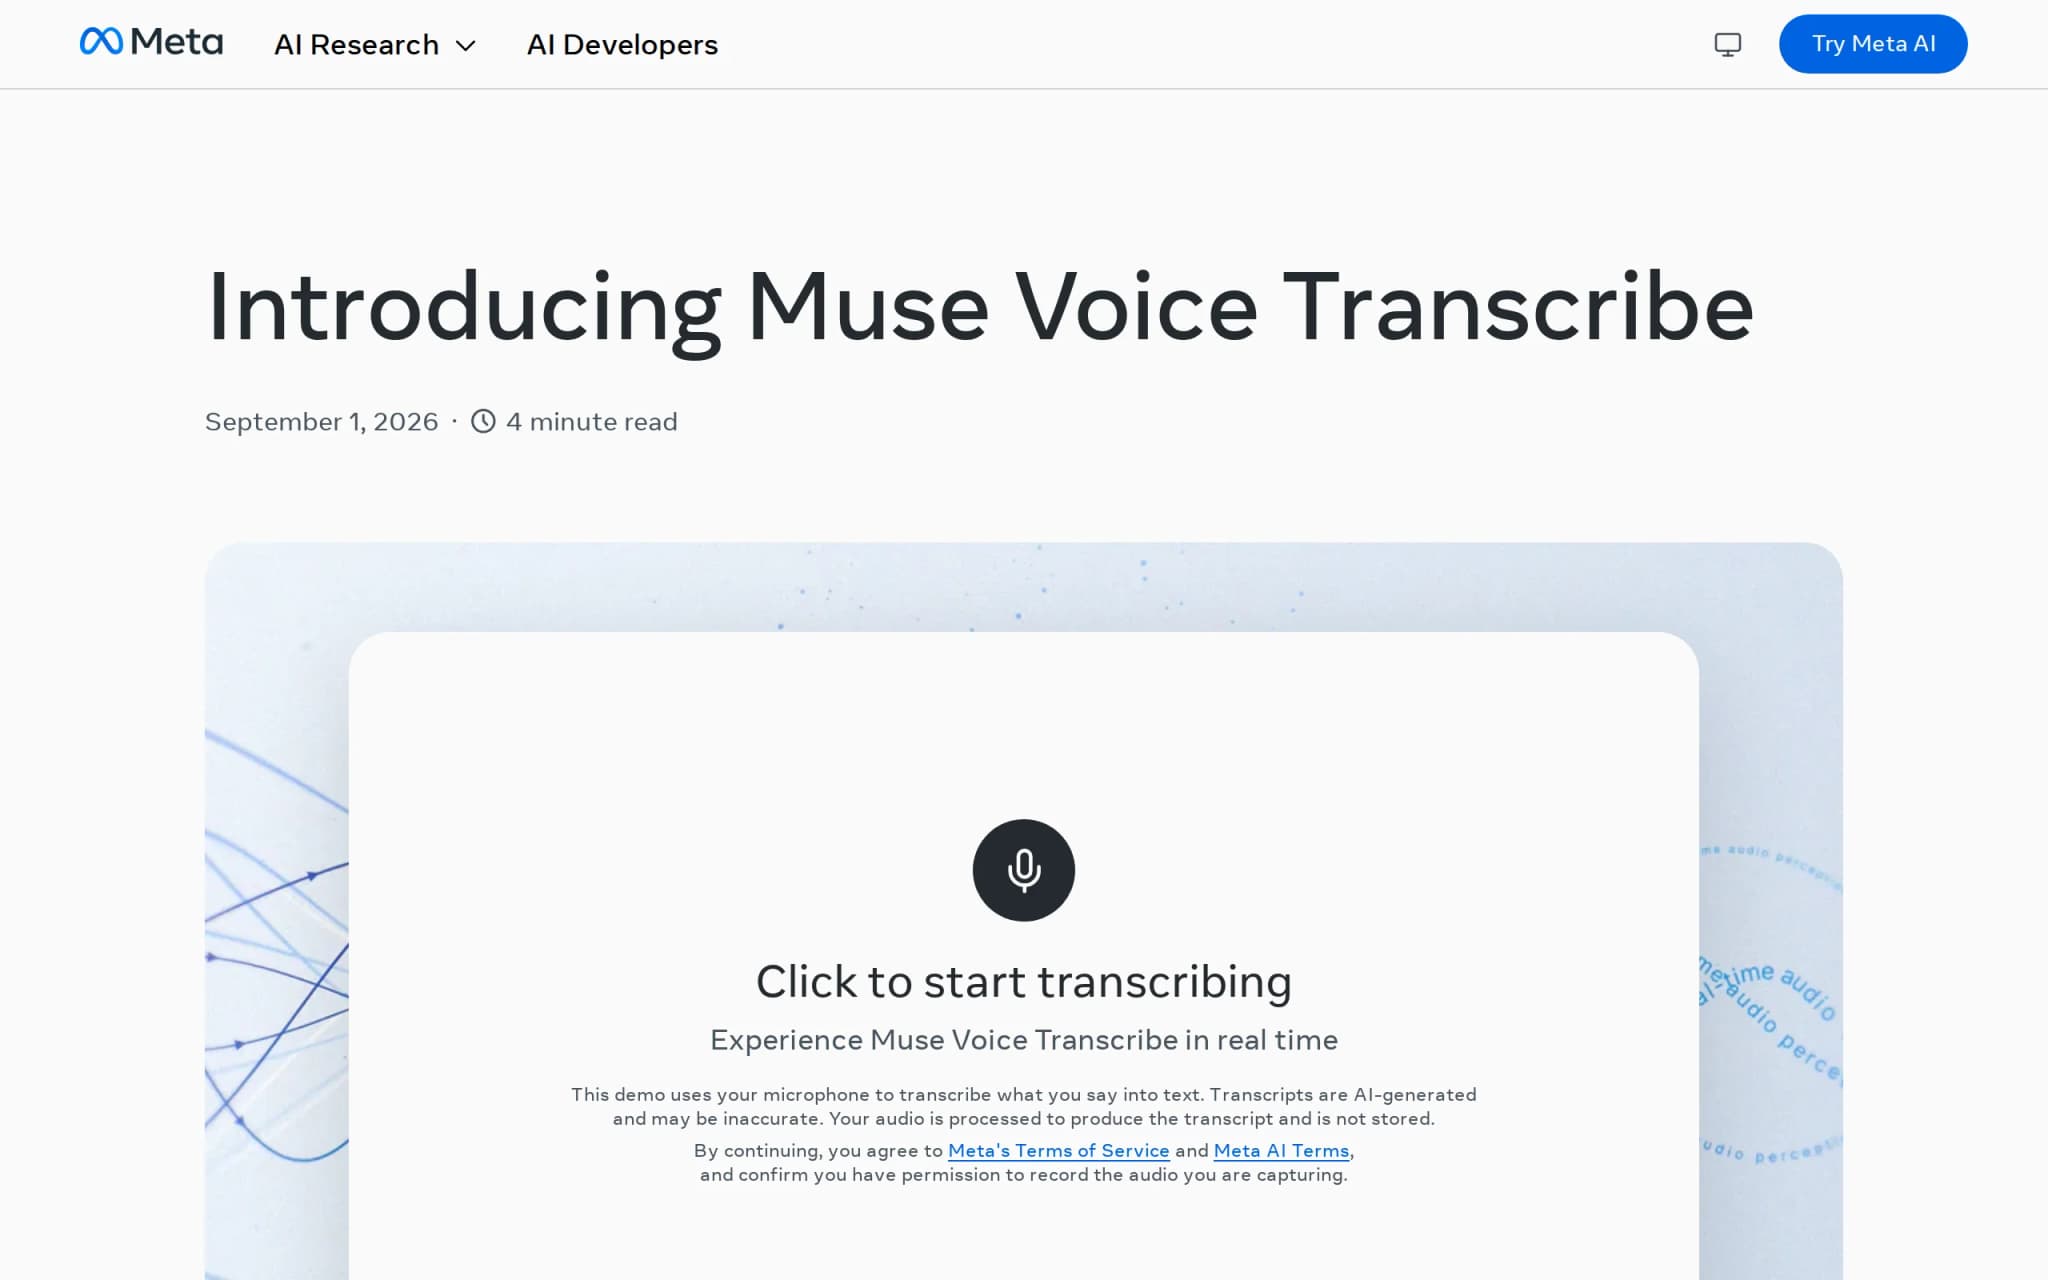
Muse Voice Transcribe – Meta's First Real-Time Audio Perception Model
Muse Voice Transcribe is Meta's first real-time audio perception model, integrating streaming automatic speech recognition (ASR), speaker segmentation, and voice endpoint detection. The model supports...
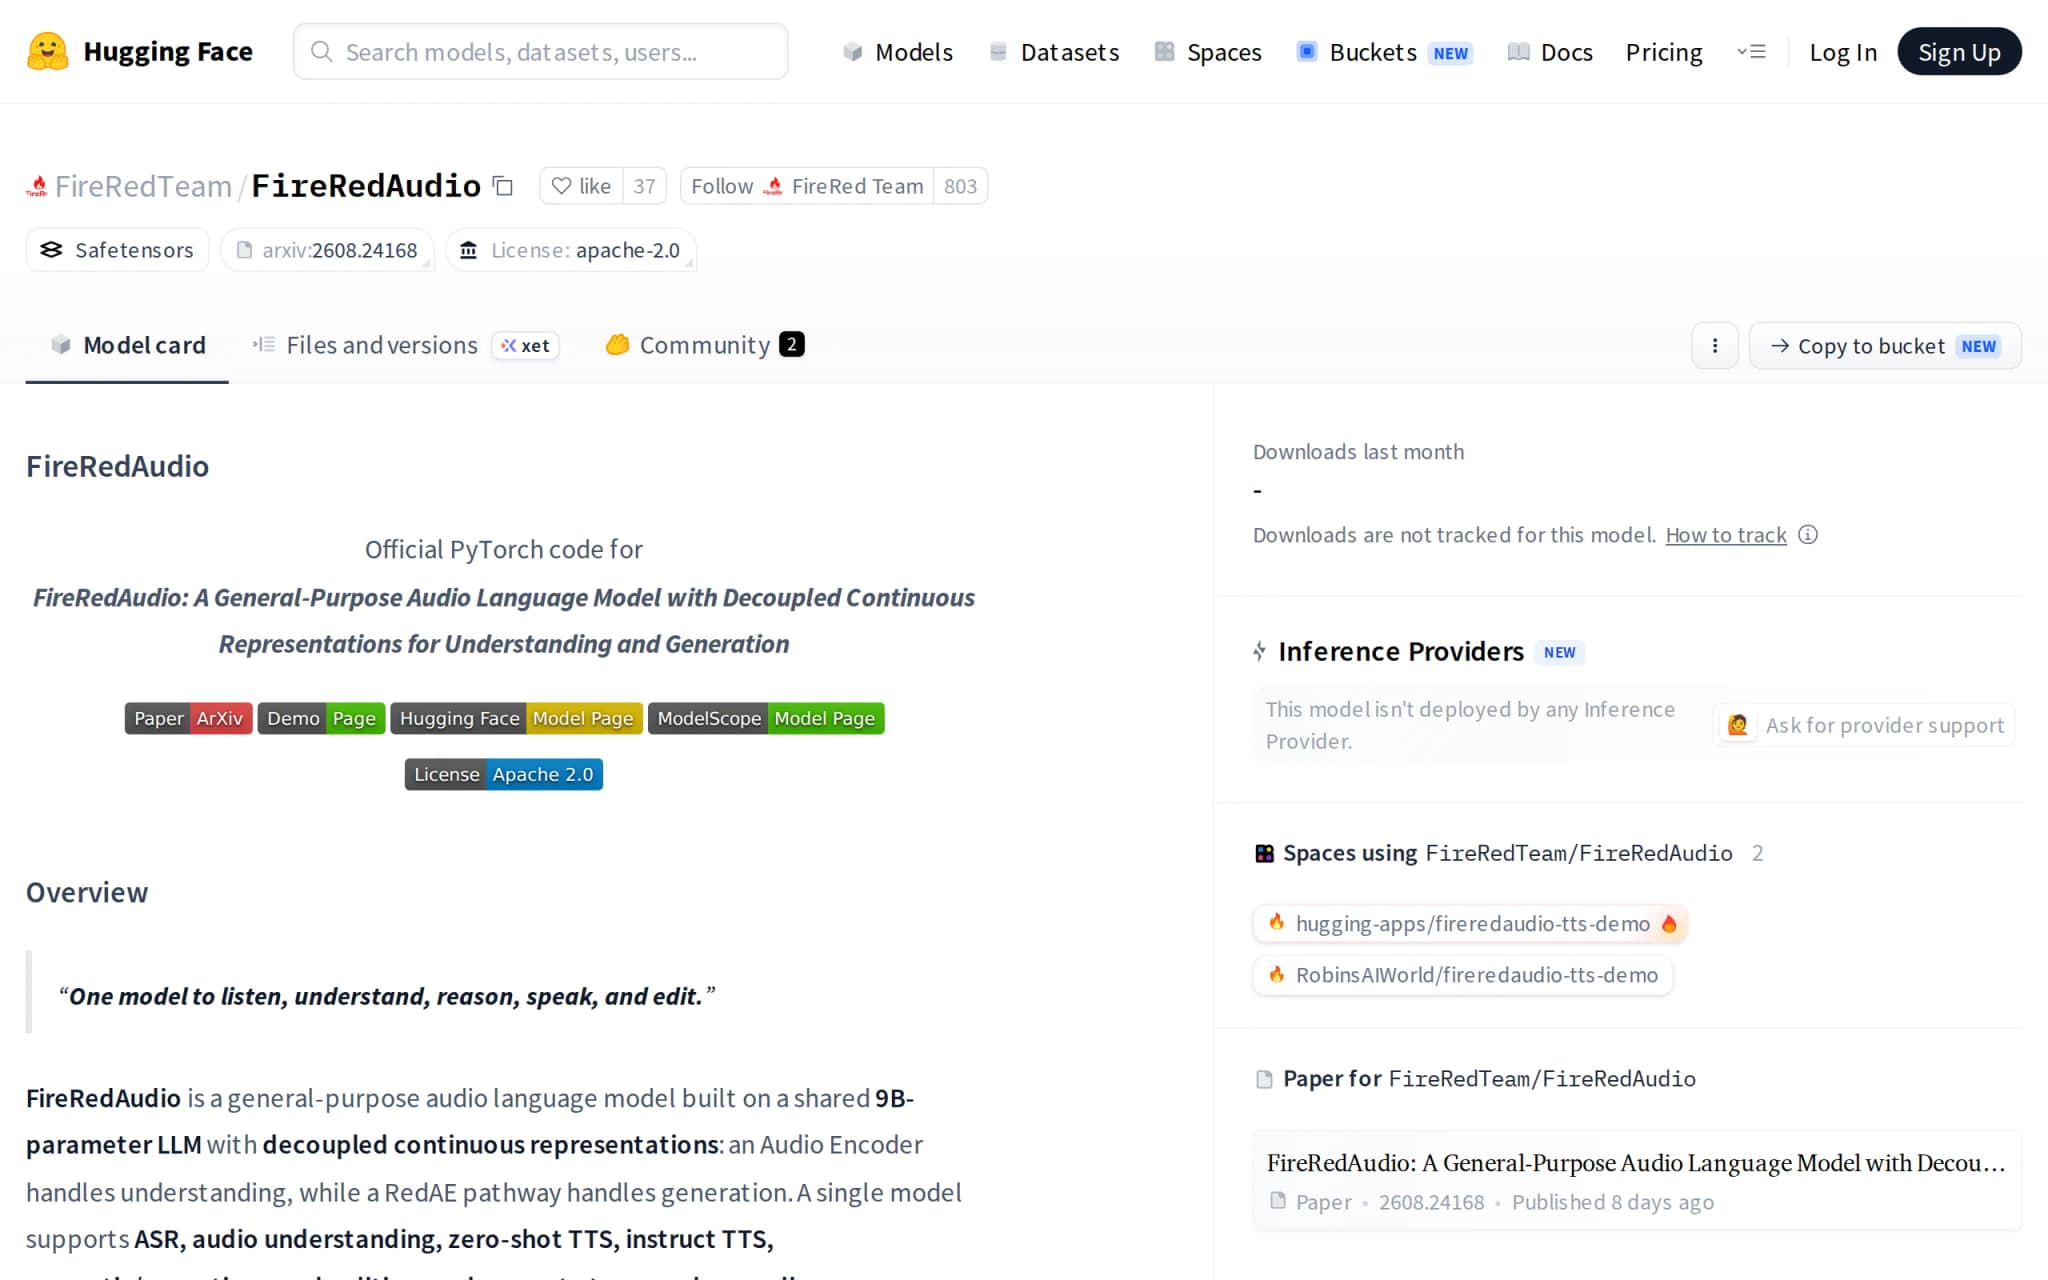
FireRedAudio – A General Audio Language Model from FireRedTeam
FireRedAudio is a general-purpose audio language model developed by FireRedTeam, with code, weights, and paper all publicly released. It uses a shared 9B autoregressive LLM as the inference backbone. ...
shuohao-skills – Open-Source AI Short Film Production Skill Collection, Featuring a Complete Workflow
shuohao-skills is an open-source collection of AI skills specifically designed for agents like Claude Code and Codex. The tool provides a complete workflow for short film production, ranging from nove...

In-Depth Review of Gemini 3.5 Transcribe: Technical Analysis and Application Outlook of Google's Next-Generation Speech-to-Text Model
Gemini 3.5 Transcribe is Google's latest Speech-to-Text model, built upon the Gemini 3.5 unified multimodal architecture. It supports two core modes: real-time streaming transcription and pre-recorded...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.