
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Speech AI
115 article(s) found · Clear tag
In-Depth Review of Breeze TTS 2 – BreezeBlue's Leading Text-to-Speech Model
Breeze TTS 2 is a next-generation text-to-speech (TTS) model launched by BreezeBlue. It supports zero-shot character voice design through natural language and precisely controls performance details su...
PixVerse R2 – A Real-Time Multimodal World Model from Aise Tech
PixVerse R2 is a real-time multimodal world model launched by Aise Tech, an upgraded version of PixVerse R1. The model supports multimodal inputs such as text, images, audio, and action signals, and c...
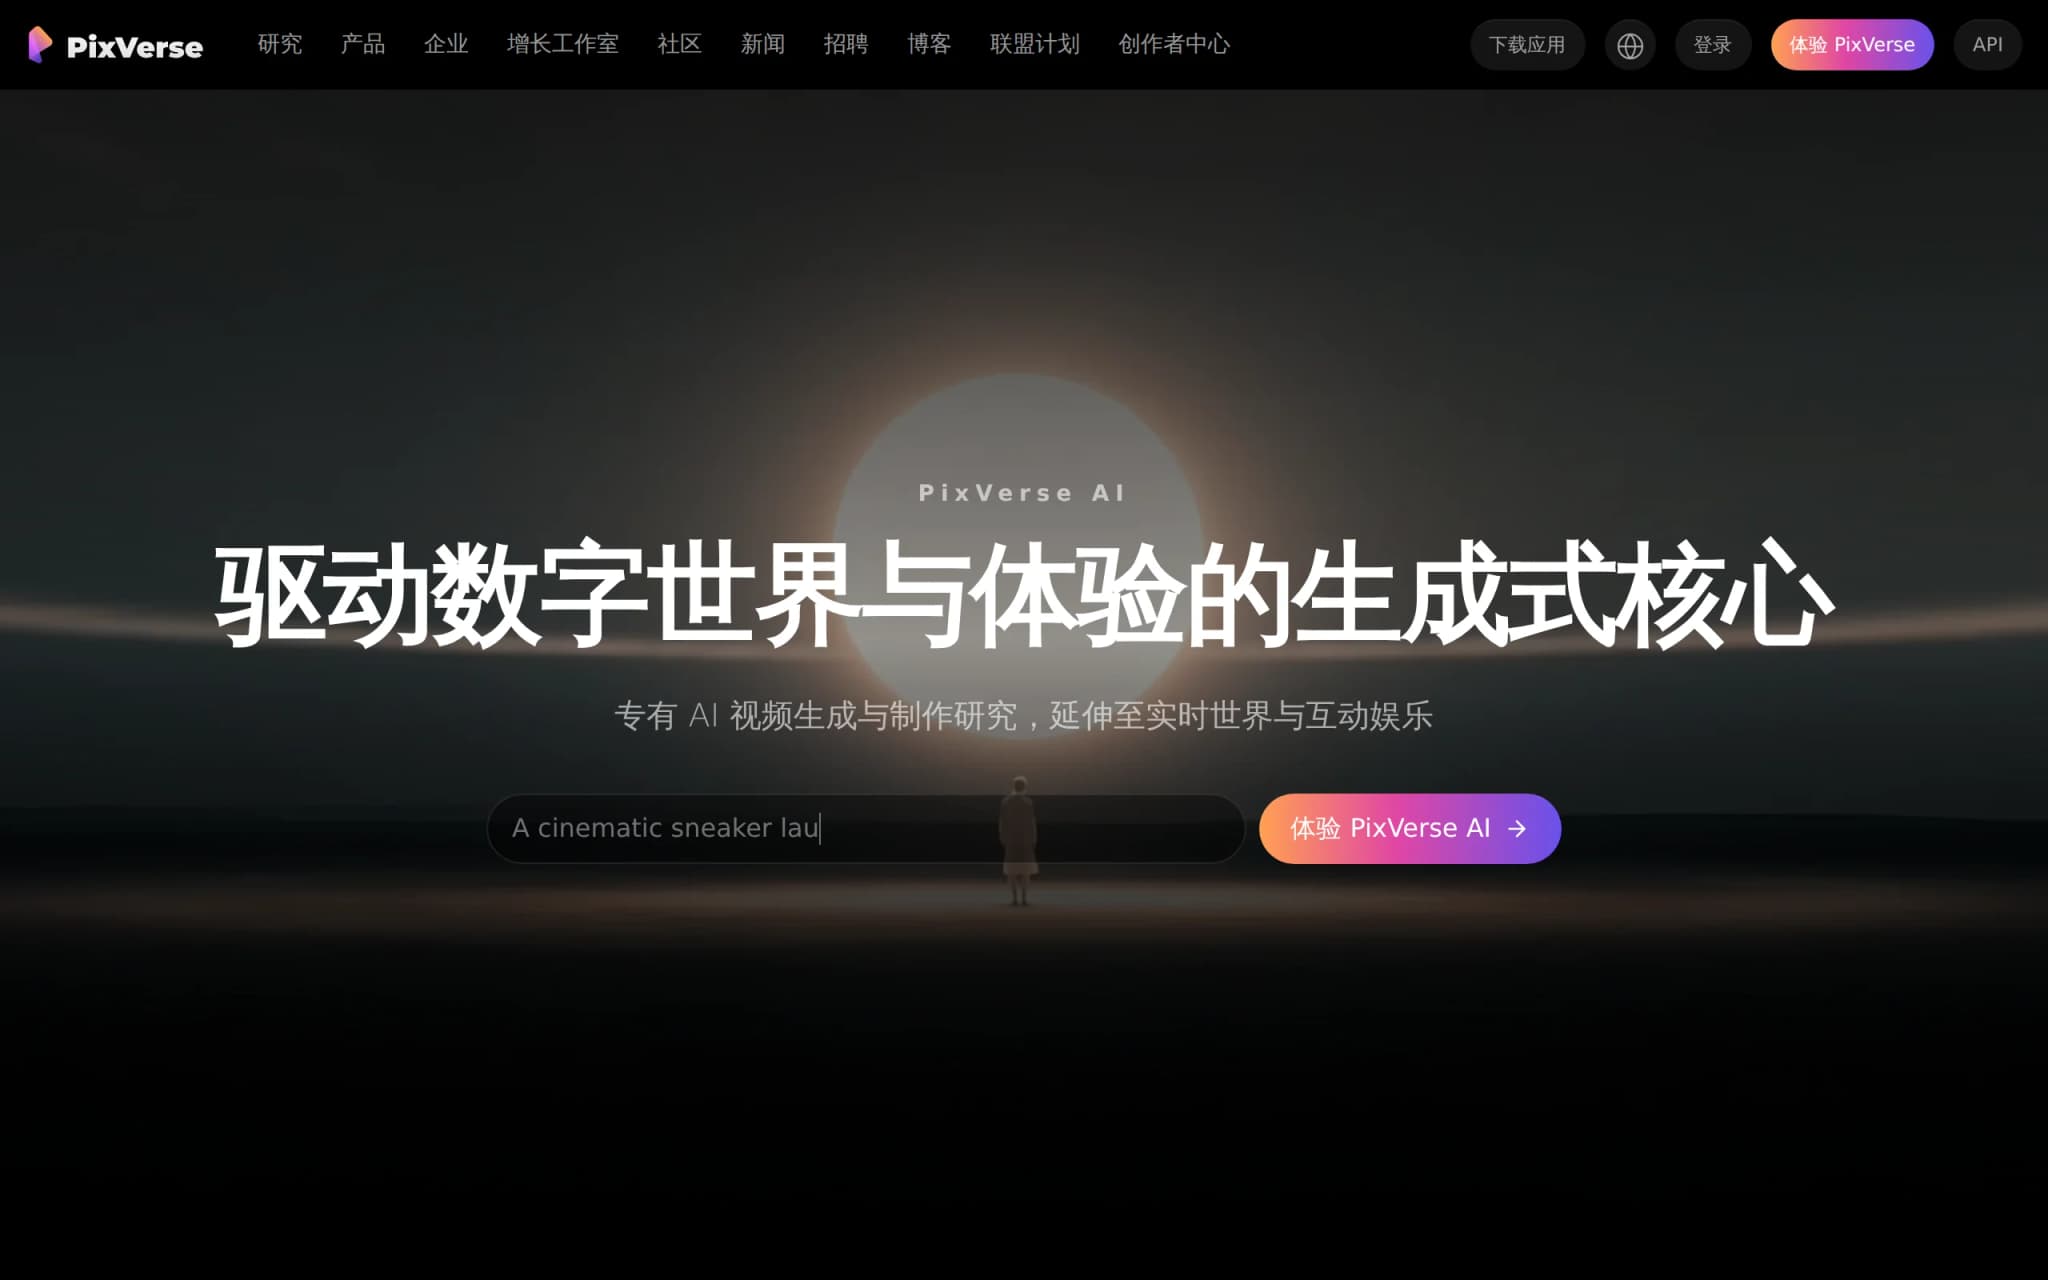
OpenStory: Open Source AI Video Production Platform, Generate Style-Consistent Short Drama Videos with One Click
OpenStory is an open-source AI video production platform that specializes in converting scripts into style-consistent short drama videos with a single click. The platform can automatically split scene...
FireRedTTS3 – Xiaohongshu's Open-Source Unified Speech Generation and Editing Model
FireRedTTS3 is an open-source unified speech generation and editing model developed by Xiaohongshu's FireRed team. Built upon the RedAE semantic-enhanced continuous representation and LLM-DiT architec...
Luna-TTS – A Text-to-Speech Large Model from VUI Labs
Luna-TTS is a text-to-speech large model independently developed by VUI Labs, a startup company affiliated with Shanghai Jiao Tong University. This model abandons the mainstream autoregressive generat...
Mureka V9.5 – A New Generation AI Music Generation Model from Kunlunwanwei
Mureka V9.5 is a new generation AI music generation model launched by Kunlunwanwei, built upon its self-developed MusiCoT music reasoning framework. It first constructs a global musical structure befo...
Qwen3.8-27B – A New Generation of Open-Source AI Large Model from the Qwen Team at Alibaba
Qwen3.8-27B is a new generation of large model open-sourced by the Qwen team at Alibaba. It employs an end-to-end native audio modeling architecture with 270 billion dense parameters, supports a nativ...
dots3-note preview – In-Depth Review of Xiaohongshu's Open-Source Multimodal MoE Model
dots3-note preview is an open-source multimodal MoE model developed by Xiaohongshu's dots model lab. As the first version of the dots3 series, it shares the same technical lineage as the IMO 2026 full...
MiniMax Music 3.0 – MiniMax's Open-Weight Music Generation Model
MiniMax Music 3.0 is the next-generation open-weight music generation model introduced by MiniMax. The model employs a hierarchical architecture combining an 8B Global LLM and a 0.6B Local LLM, and in...
dots.tts – Xiaohongshu and Shanghai Jiao Tong University Open-Source Base Model for Text-to-Speech
dots.tts is a 20-billion-parameter fully continuous autoregressive text-to-speech base model jointly open-sourced by Xiaohongshu's dots team and the X-LANCE Lab at Shanghai Jiao Tong University. The m...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.