
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Multimodal
121 article(s) found · Clear tag
Higgs Avatar v1 – Real-Time AI Digital Human for Voice Agents
Higgs Avatar v1 from BosonAI (founded by Mu Li) is a real-time AI digital human model for voice agents. From a single static photo it produces lip-synced faces with expressions and head motion for liv...
Qwen3.7 Preview – Alibaba Tongyi's Next-Generation Flagship LLM Preview
Qwen3.7 Preview is Alibaba Tongyi Qwen's next-generation flagship preview, with Qwen3.7-Max-Preview and Qwen3.7-Plus-Preview targeting extreme complex reasoning and balanced experience respectively. I...
Chronicles-OCR – Cross-Temporal Visual Perception Benchmark for Chinese Script Evolution
Chronicles-OCR is the first industry benchmark to cover the full evolutionary trajectory of Chinese script "seven-style transformation" (七体之变)—jointly released by Tencent Hunyuan, the Institute of Inf...
Qwen3.5-LiveTranslate – Alibaba Tongyi's Real-Time Simultaneous Interpretation Model
Qwen3.5-LiveTranslate is Alibaba Tongyi's next-generation real-time simultaneous interpretation model. It breaks the latency ceiling of traditional cascaded translation pipelines. Through an innovativ...
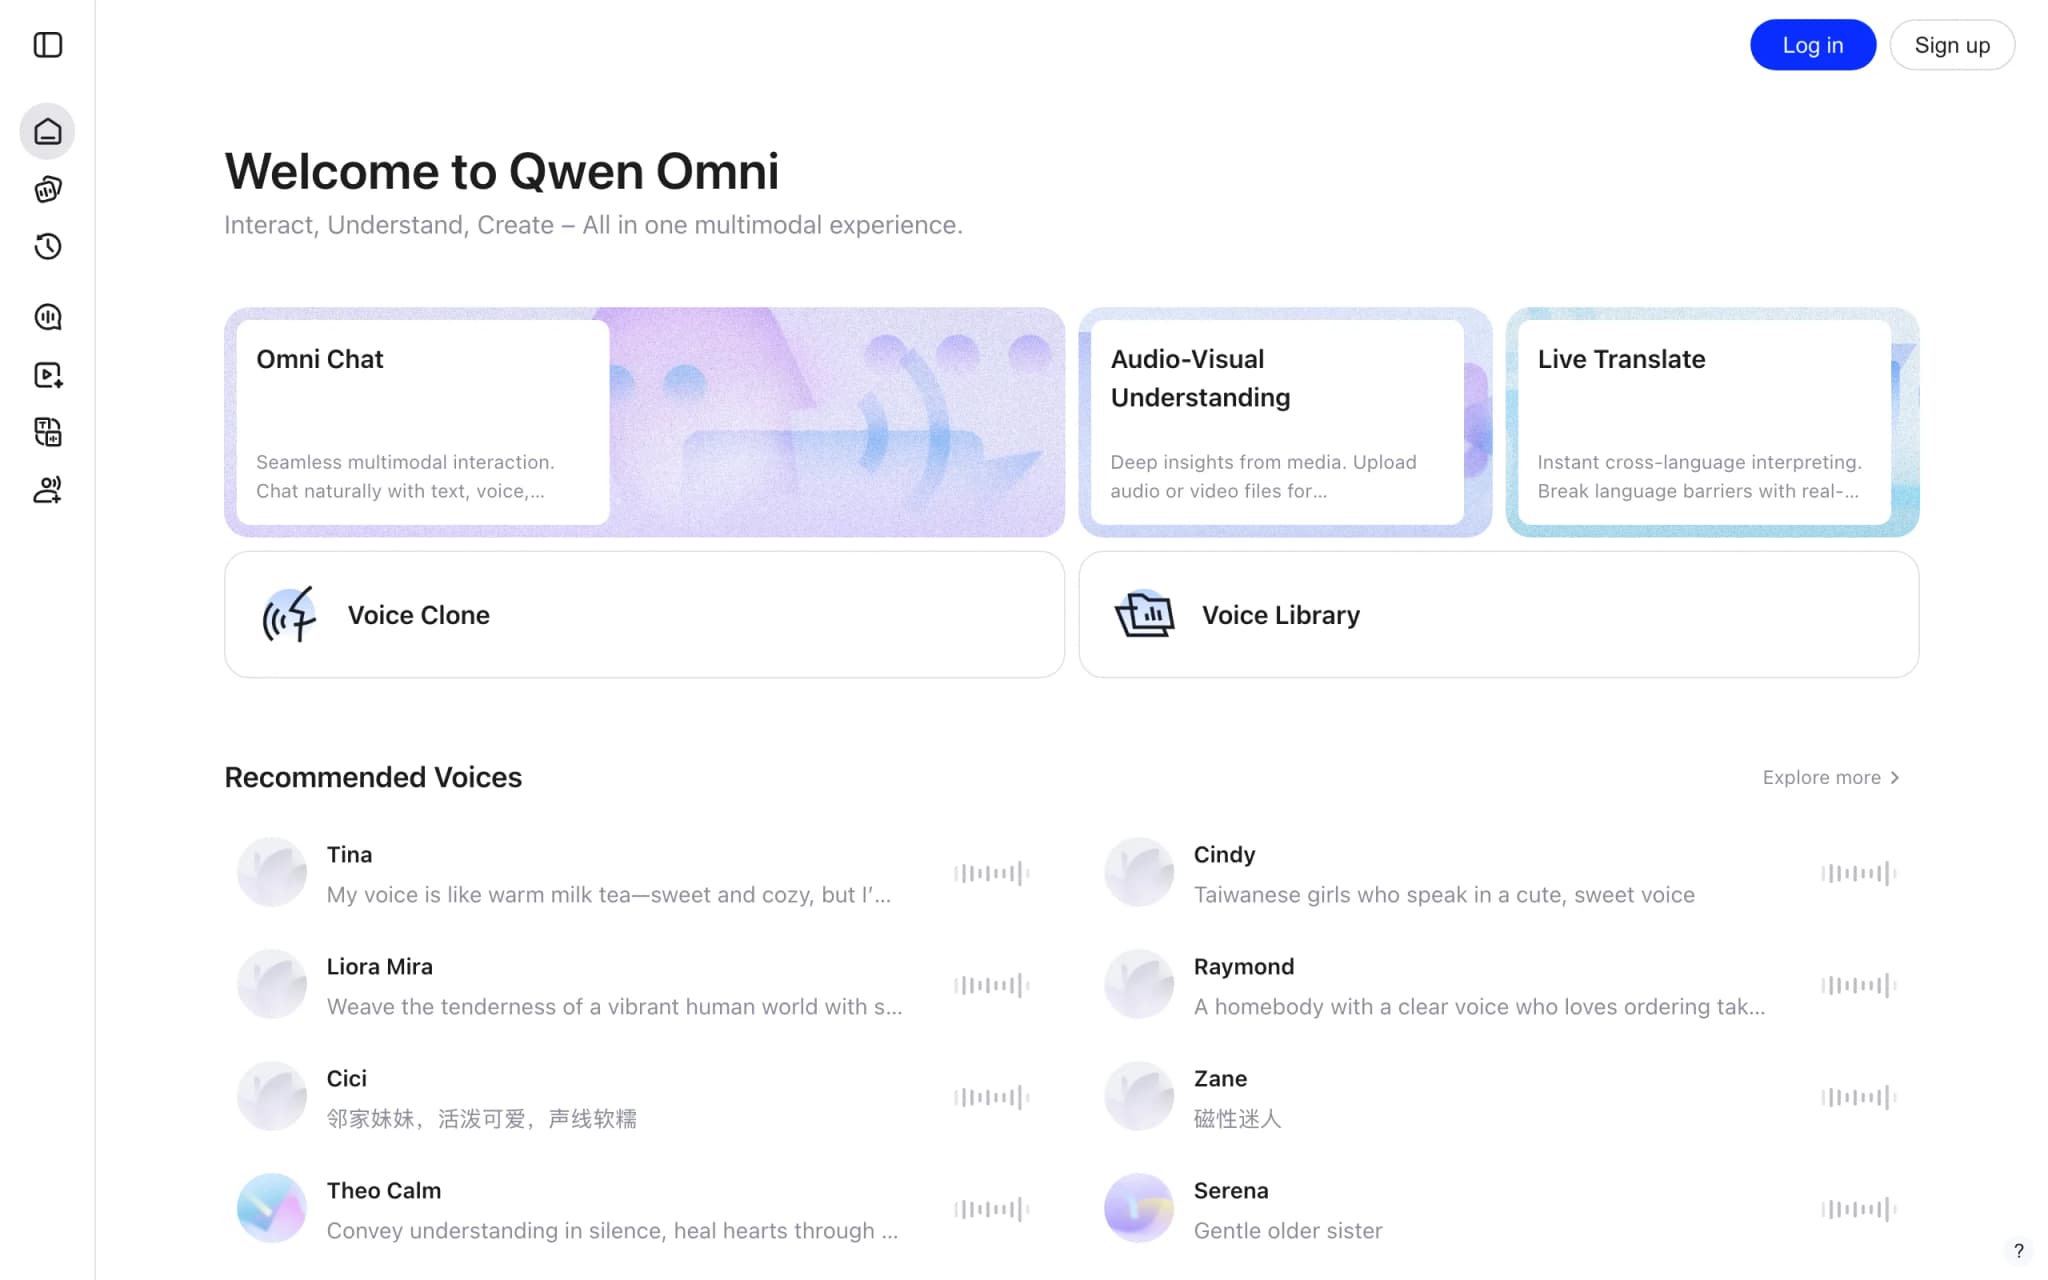
Gemini Omni Flash – Google's Multimodal Video Generation Model
Gemini Omni Flash is Google's unified multimodal world generation model unveiled at I/O, positioned to break traditional generative model modality barriers and enable any-input to any-output full-pipe...
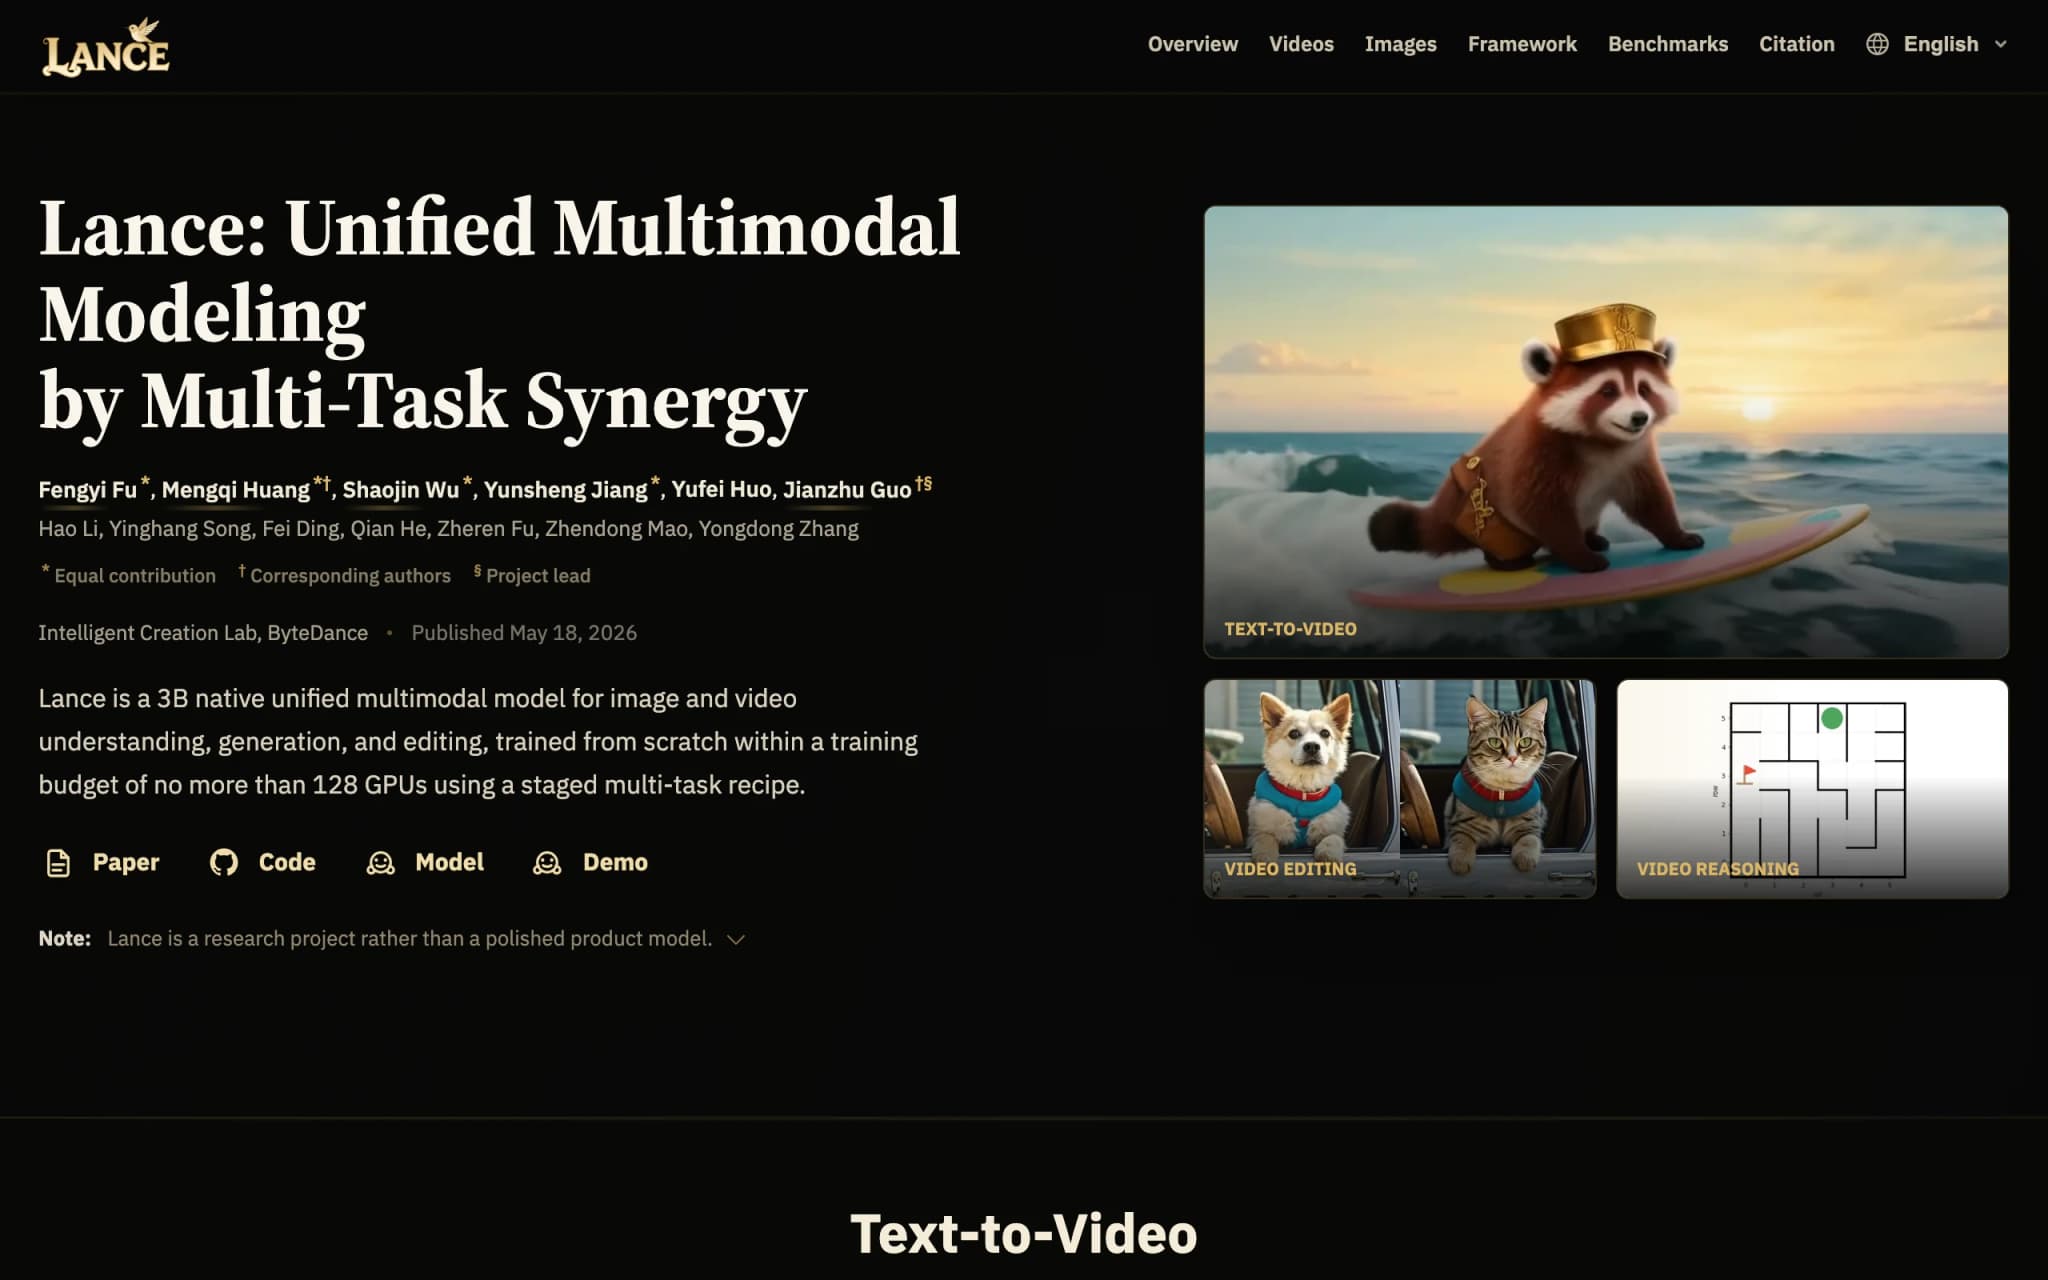
Lance – ByteDance's Lightweight Native Unified Multimodal Model
Lance is a lightweight native unified multimodal model open-sourced by ByteDance's Intelligent Creation team. With only 3B active parameters, it supports the full pipeline of image and video understan...
HiDream-O1-Image-Pro – HiDream.ai's Flagship Image Model
HiDream-O1-Image-Pro is HiDream.ai's flagship image generation model built on the native full-modal UiT (Unified Transformer) architecture with over 200B parameters. It sets new SOTA across text-to-im...
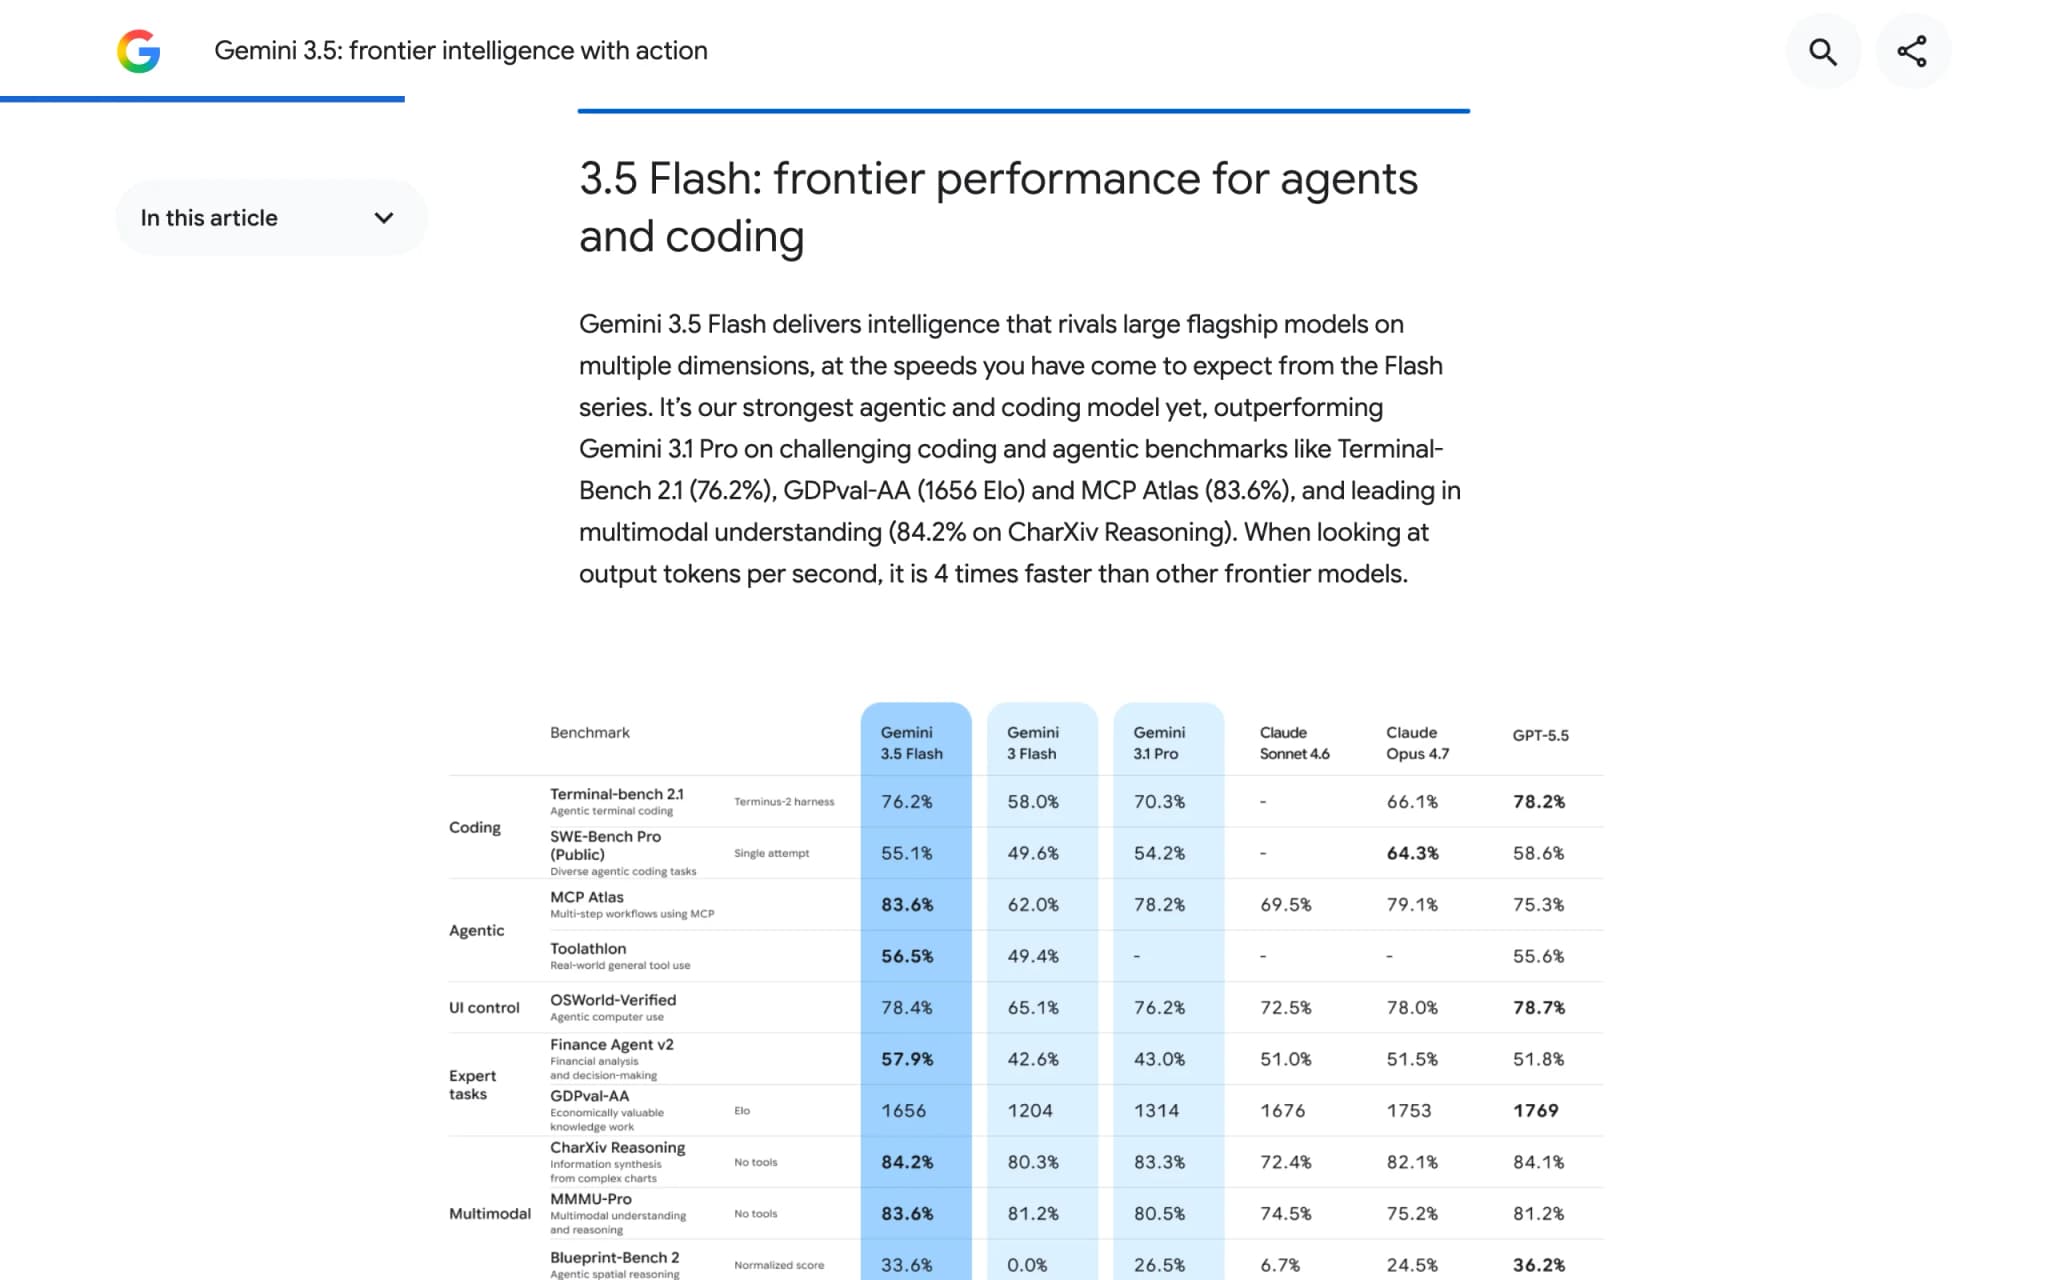
Gemini 3.5 Flash – Google's Next-Generation AI Foundation Model
Gemini 3.5 Flash is Google's next-generation AI foundation model, positioned around "frontier intelligence + action capability," marking a major breakthrough in efficient inference and Agent capabilit...
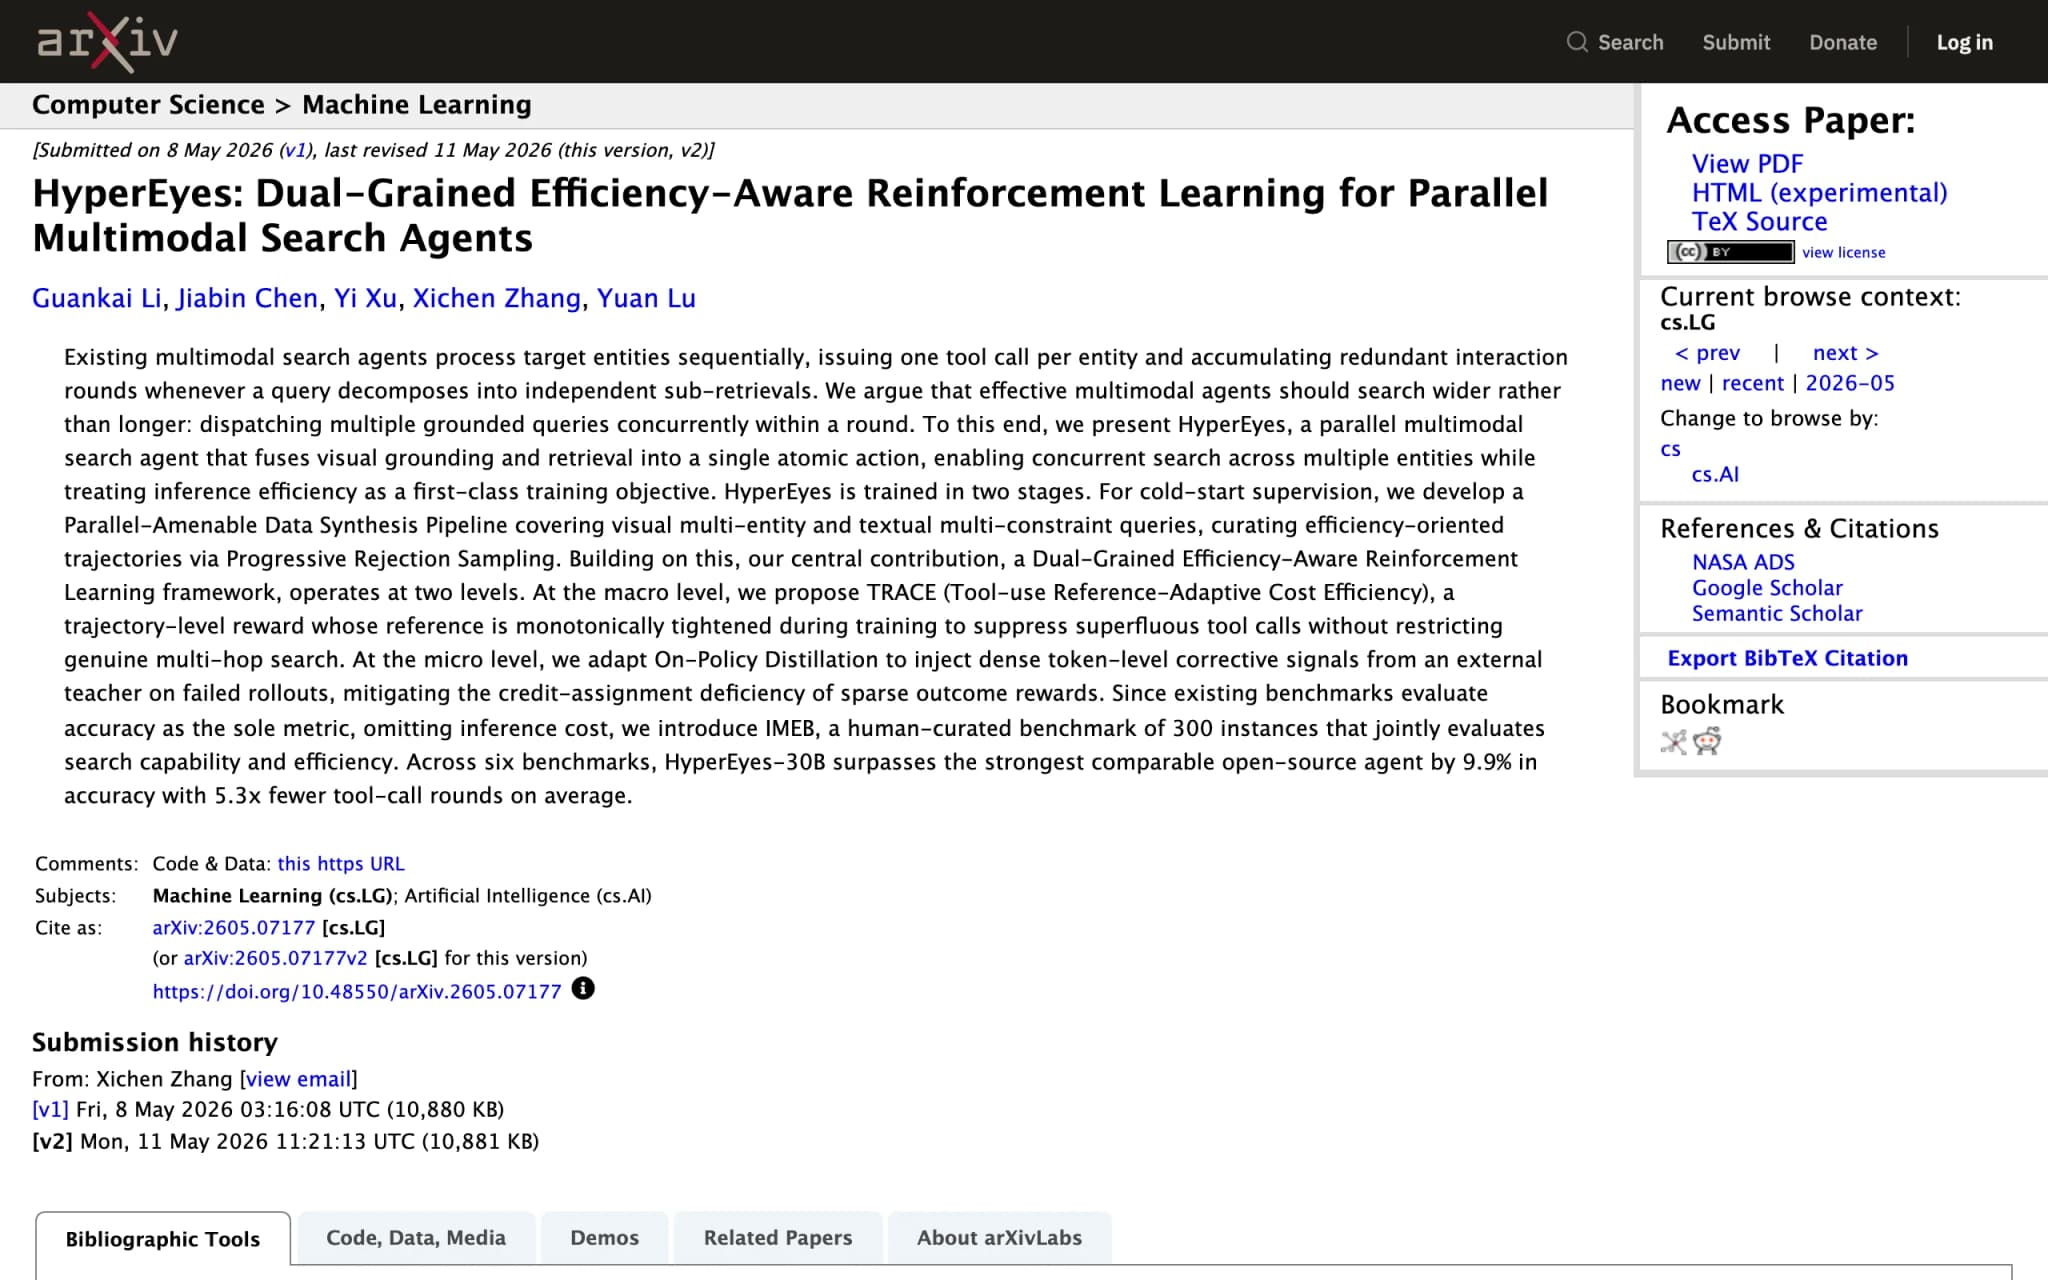
HyperEyes – Xiaohongshu and Cambridge's Parallel Multimodal Search Agent
HyperEyes is a parallel multimodal search agent jointly launched by Xiaohongshu and the University of Cambridge. It introduces the UGS (Unified Grounded Search) paradigm, fusing visual grounding and r...
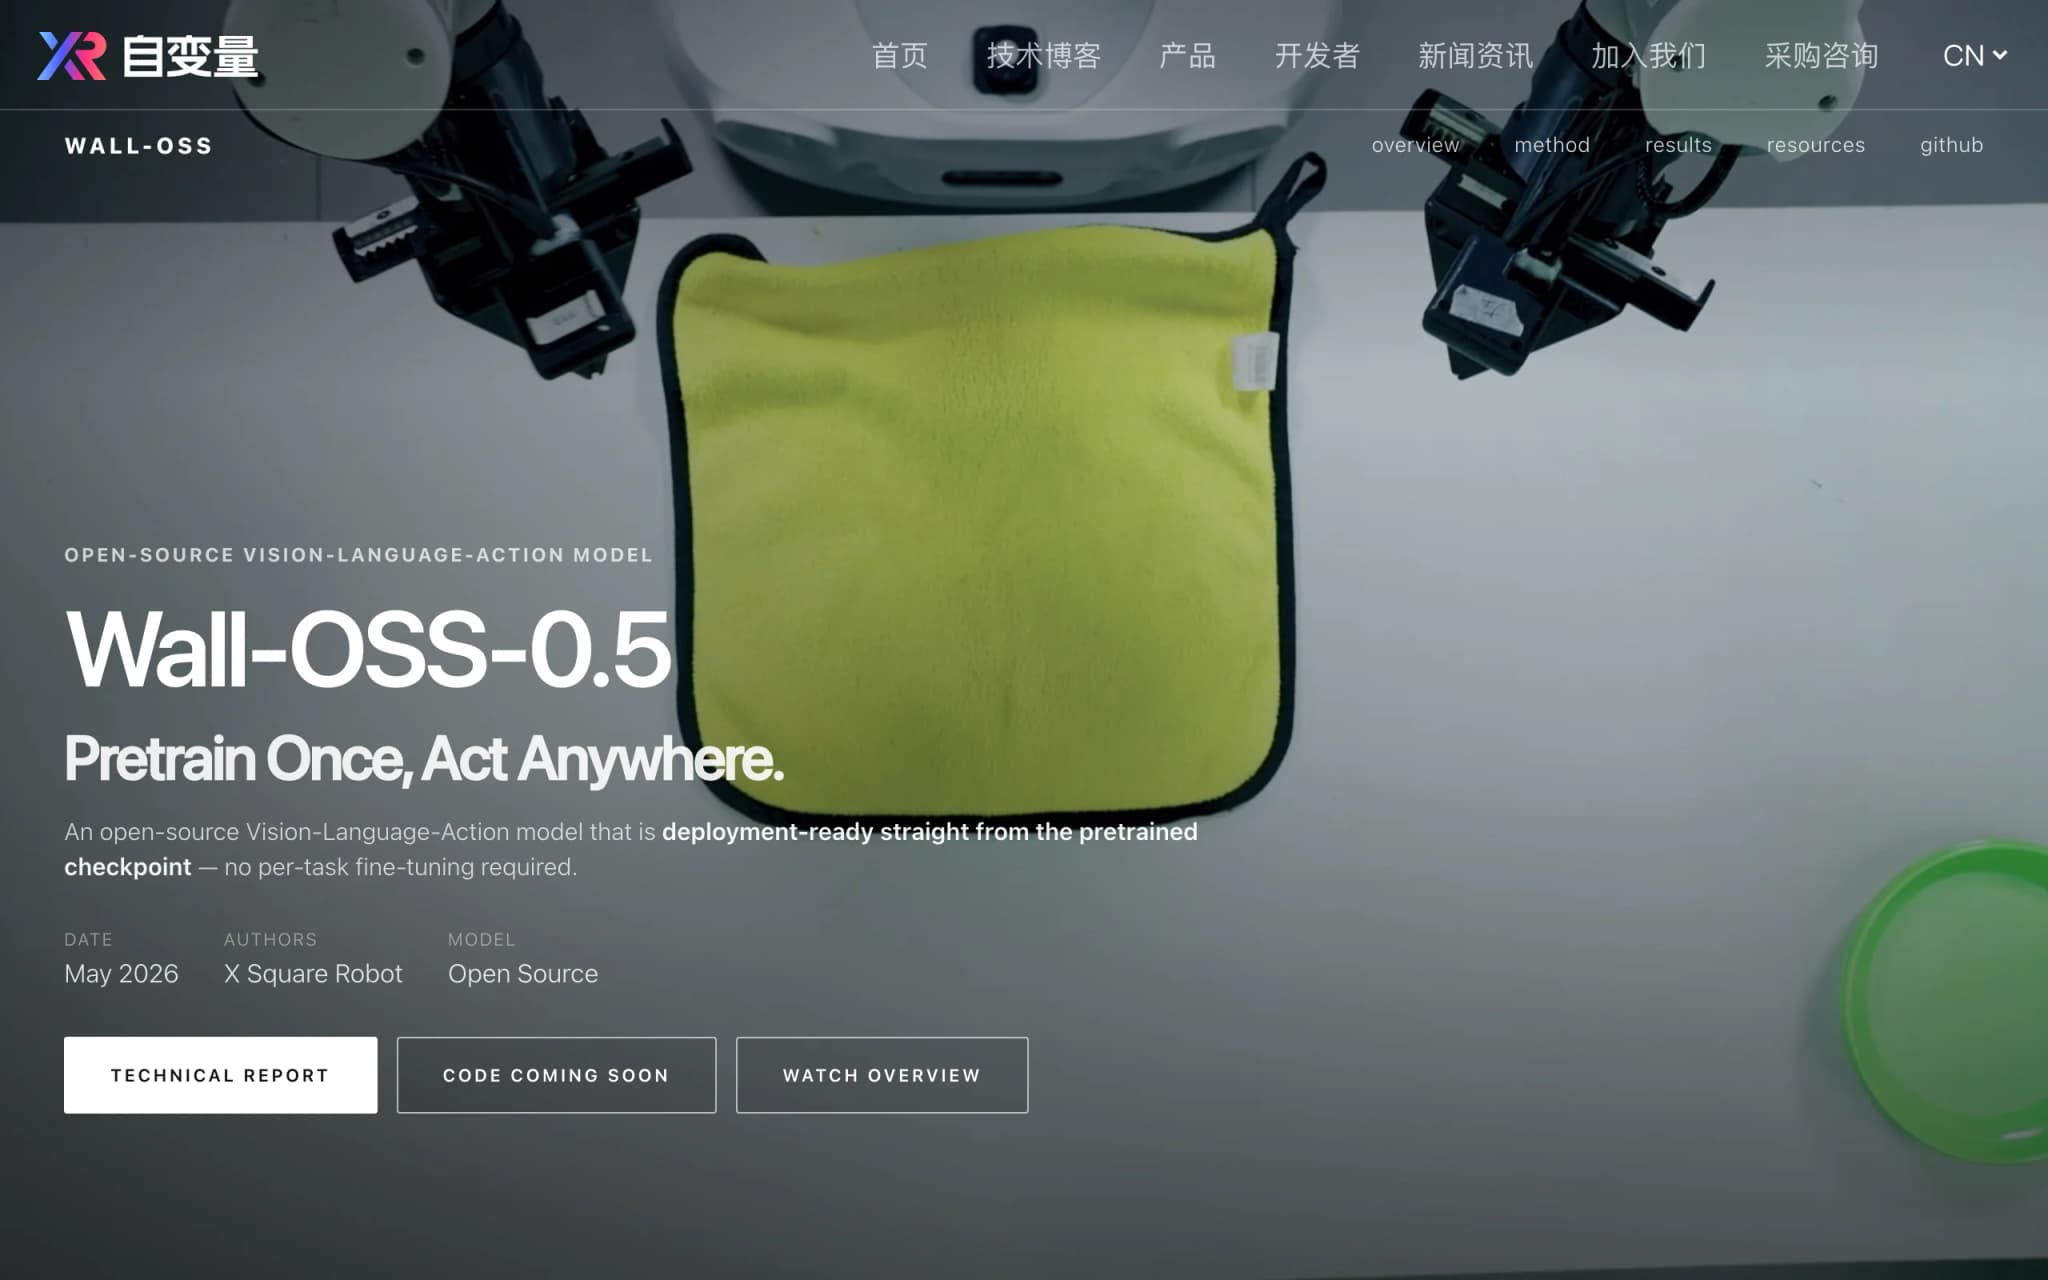
Wall-OSS-0.5 – X Square Robot’s Open Embodied Intelligence Model
Wall-OSS-0.5 is X Square Robot’s open vision-language-action (VLA) model—a 4B-parameter stack on a 3B Qwen2.5-VL backbone achieving zero-shot real-robot deployment without per-task fine-tuning. Gradie...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.