
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Multimodal
121 article(s) found · Clear tag
Step 3.7 Flash – StepFun's Open-Source Flash Model Generation
Step 3.7 Flash is StepFun's next-generation open-source Flash model for production-grade Agent deployment. Built on a sparse MoE architecture, it maintains high inference speed (up to 400 tokens/s) wh...
SpaceMind – iFLYTEK’s Agentic Smart-Space Architecture
SpaceMind is iFLYTEK’s agentic architecture for intelligent spaces. It upgrades traditional smart homes into L2.5 proactive agents with perception, understanding, memory, decision-making, and executio...
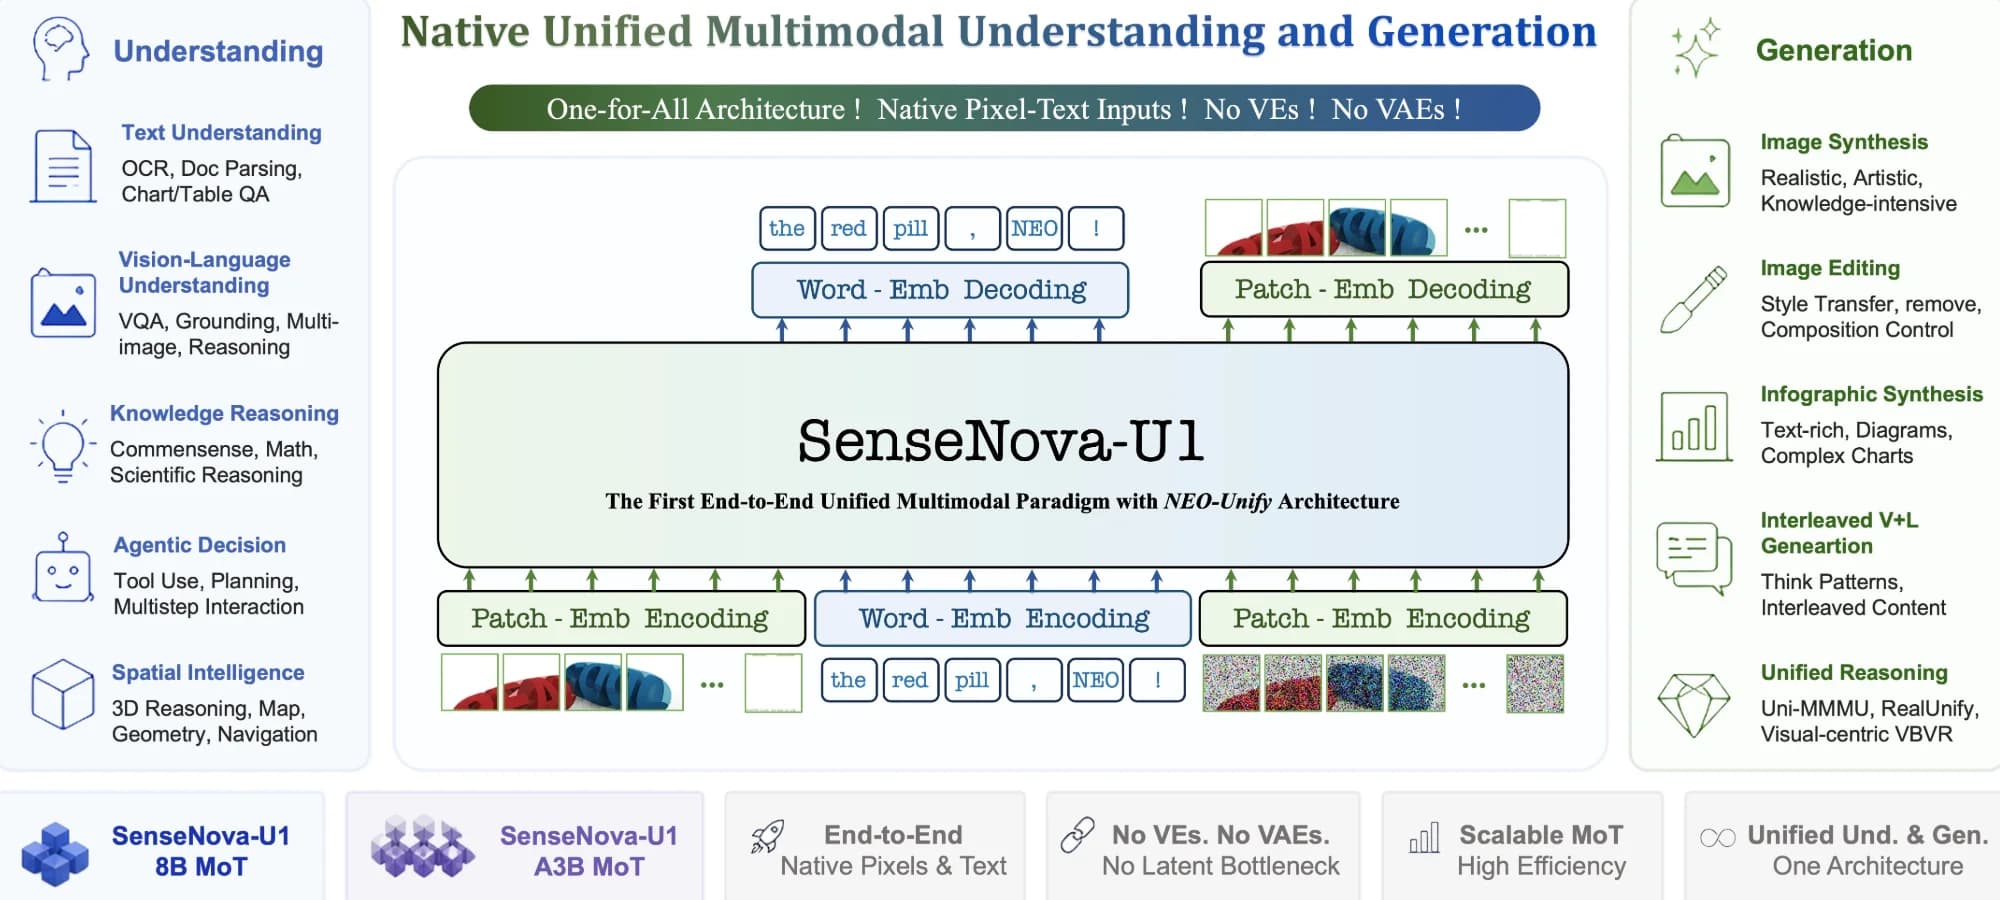
SenseNova-U1-8B-MoT-Infographic – SenseTime's Open-Source Infographic-Enhanced Model
SenseNova-U1-8B-MoT-Infographic is SenseTime's open-source infographic-enhanced model built on the unified SenseNova-U1-8B-MoT architecture at 8B parameters. Through targeted data training and reinfor...
SenseNova-Skills – SenseTime's Open-Source Modular AI Office Skills Library
SenseNova-Skills is an open-source modular AI office skills library from the OpenSenseNova (SenseTime) team, designed for Agent runtimes. It breaks down four core office capabilities—infographic gener...
Seedance 2.0 Mini – ByteDance's Lightweight Video Generation Model
Seedance 2.0 Mini is a cost-efficient lightweight video generation model from ByteDance Volcano Engine for high-frequency short-video production, marketing asset iteration, and early-stage drafts. It ...
Qwen3.7-Plus – Alibaba Tongyi's Agentic Multimodal Large Model
Qwen3.7-Plus is Alibaba Cloud Tongyi Qwen team's next-generation multimodal large model positioned as an "agent foundation," integrating visual perception, language understanding, code generation, and...
Qwen-VLA – Alibaba Tongyi's General Vision-Language-Action Model
Qwen-VLA is Tongyi Lab's general vision-language-action model: Qwen3.5-4B VLM backbone plus 1.15B DiT action decoder. A unified action trajectory prediction framework merges manipulation, navigation, ...
Qwen-Robot Suite – Alibaba Tongyi's Physical-World Foundation Model Suite
Qwen-Robot Suite is Alibaba Tongyi Lab's foundation model suite for physical-world intelligence, comprising Qwen-RobotNav (navigation), Qwen-RobotManip (manipulation), and Qwen-RobotWorld (world model...
Qwen-Image-Bench – Qwen Team's Text-to-Image Model Evaluation Benchmark
Qwen-Image-Bench is a standardized benchmark dataset from Alibaba's Qwen team (Tongyi Qianwen) for evaluating text-to-image models—1,000 carefully designed test samples covering Chinese and English pr...
PaddleOCR-VL-1.6 – Baidu's Document Parsing Vision-Language Model
PaddleOCR-VL-1.6 is a vision-language model (VLM) for document parsing from Baidu's PaddlePaddle team. With only 0.9B parameters, it achieves a new SOTA of 96.33% on the OmniDocBench v1.6 benchmark, s...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.