
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Speech AI
115 article(s) found · Clear tag
Inkling – A Multimodal Foundation Model from Thinking Machines Lab
Inkling is an open-weight multimodal foundation model developed by Thinking Machines Lab, utilizing a Mixture-of-Experts (MoE) architecture and natively supporting unified reasoning across text, image...
Wan-Streamer v0.2 – A Full-Modal Understanding and Generation Model from Alibaba Tongyi
Wan-Streamer v0.2 is an end-to-end full-modal understanding and generation model introduced by Alibaba Tongyi Lab, designed for real-time full-duplex interaction. This model processes real-time unders...
MuScriptor – An Open-Source Multi-Instrument Music Transcription Model Jointly Released by Kyutai and Mirelo
MuScriptor is an open-source multi-instrument music transcription model jointly developed by Kyutai and Mirelo. It can automatically transcribe audio of music from various genres in the real world int...

Tempolor v4.7 – QwenTech's Flagship AI Music Generation Model
Tempolor v4.7 is QwenTech's flagship AI music generation model, built on a fourth-generation hierarchical progressive architecture, supporting high-quality 48kHz stereo output. This model focuses on c...
SayIt – Open-Source AI Voice Input Tool, Automatically Converts Speech into Written Text
SayIt is an open-source AI voice input tool built with Rust, focused on the Windows desktop platform. Users simply hold down a shortcut key to speak, and their speech is converted in real-time into re...
AudioX-Turbo – A Unified and Efficient Audio Generation Framework Jointly Released by Noiz AI and Tsinghua University
AudioX-Turbo is a unified and efficient audio generation framework jointly developed by Noiz AI, the Hong Kong University of Science and Technology, and Tsinghua University. Based on a multimodal diff...
Fun-ASR-Realtime – Alibaba Qwen's Streaming Real-Time Speech Recognition Model
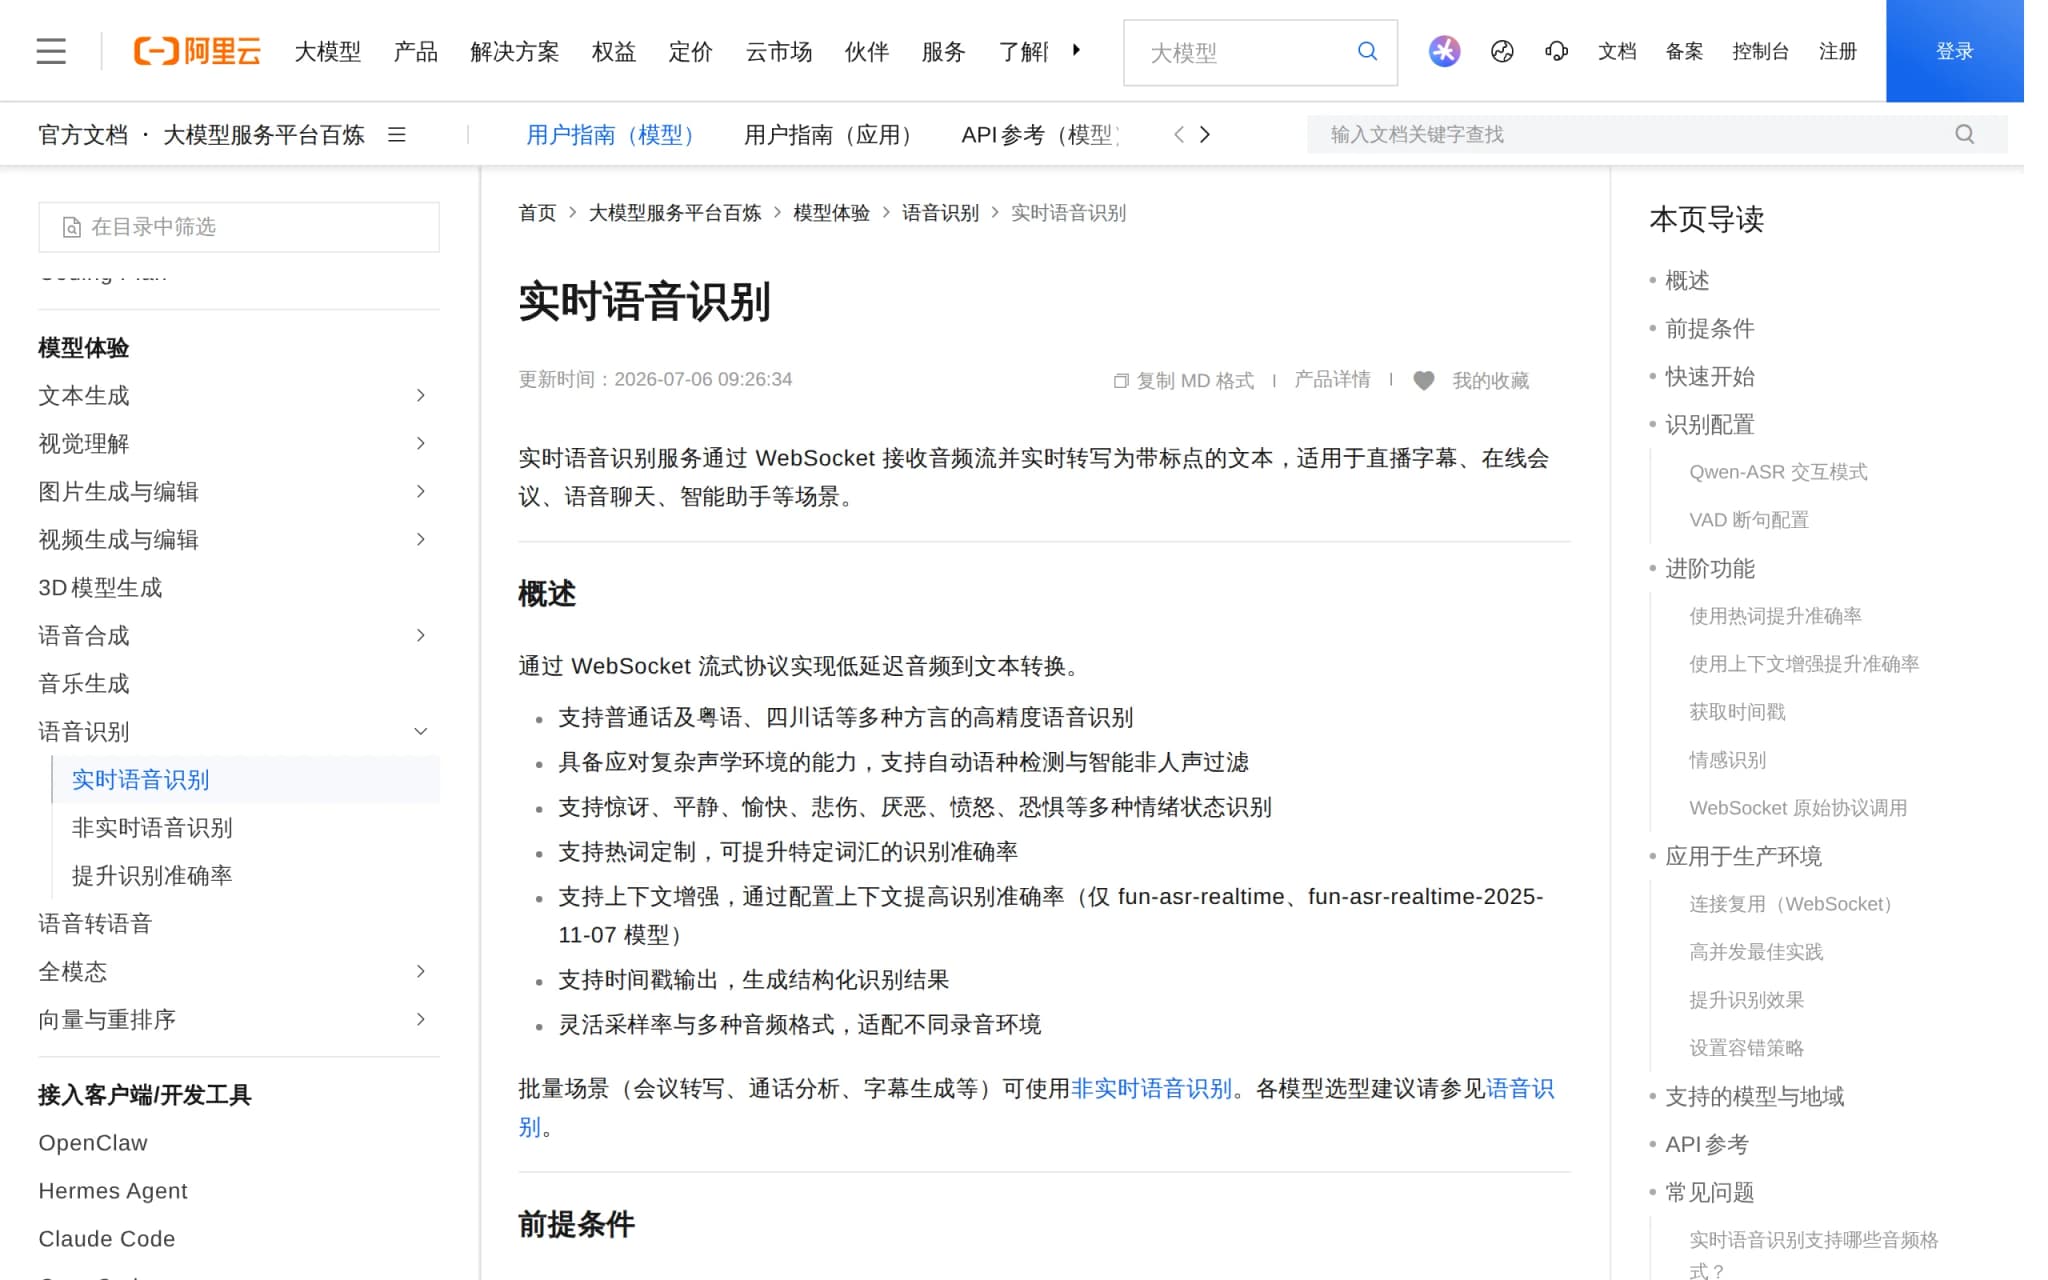
Fun-ASR-Realtime is a streaming real-time speech recognition large model launched by Alibaba Qwen, designed for low-latency, high-precision speech-to-text scenarios. The model uses the WebSocket strea...
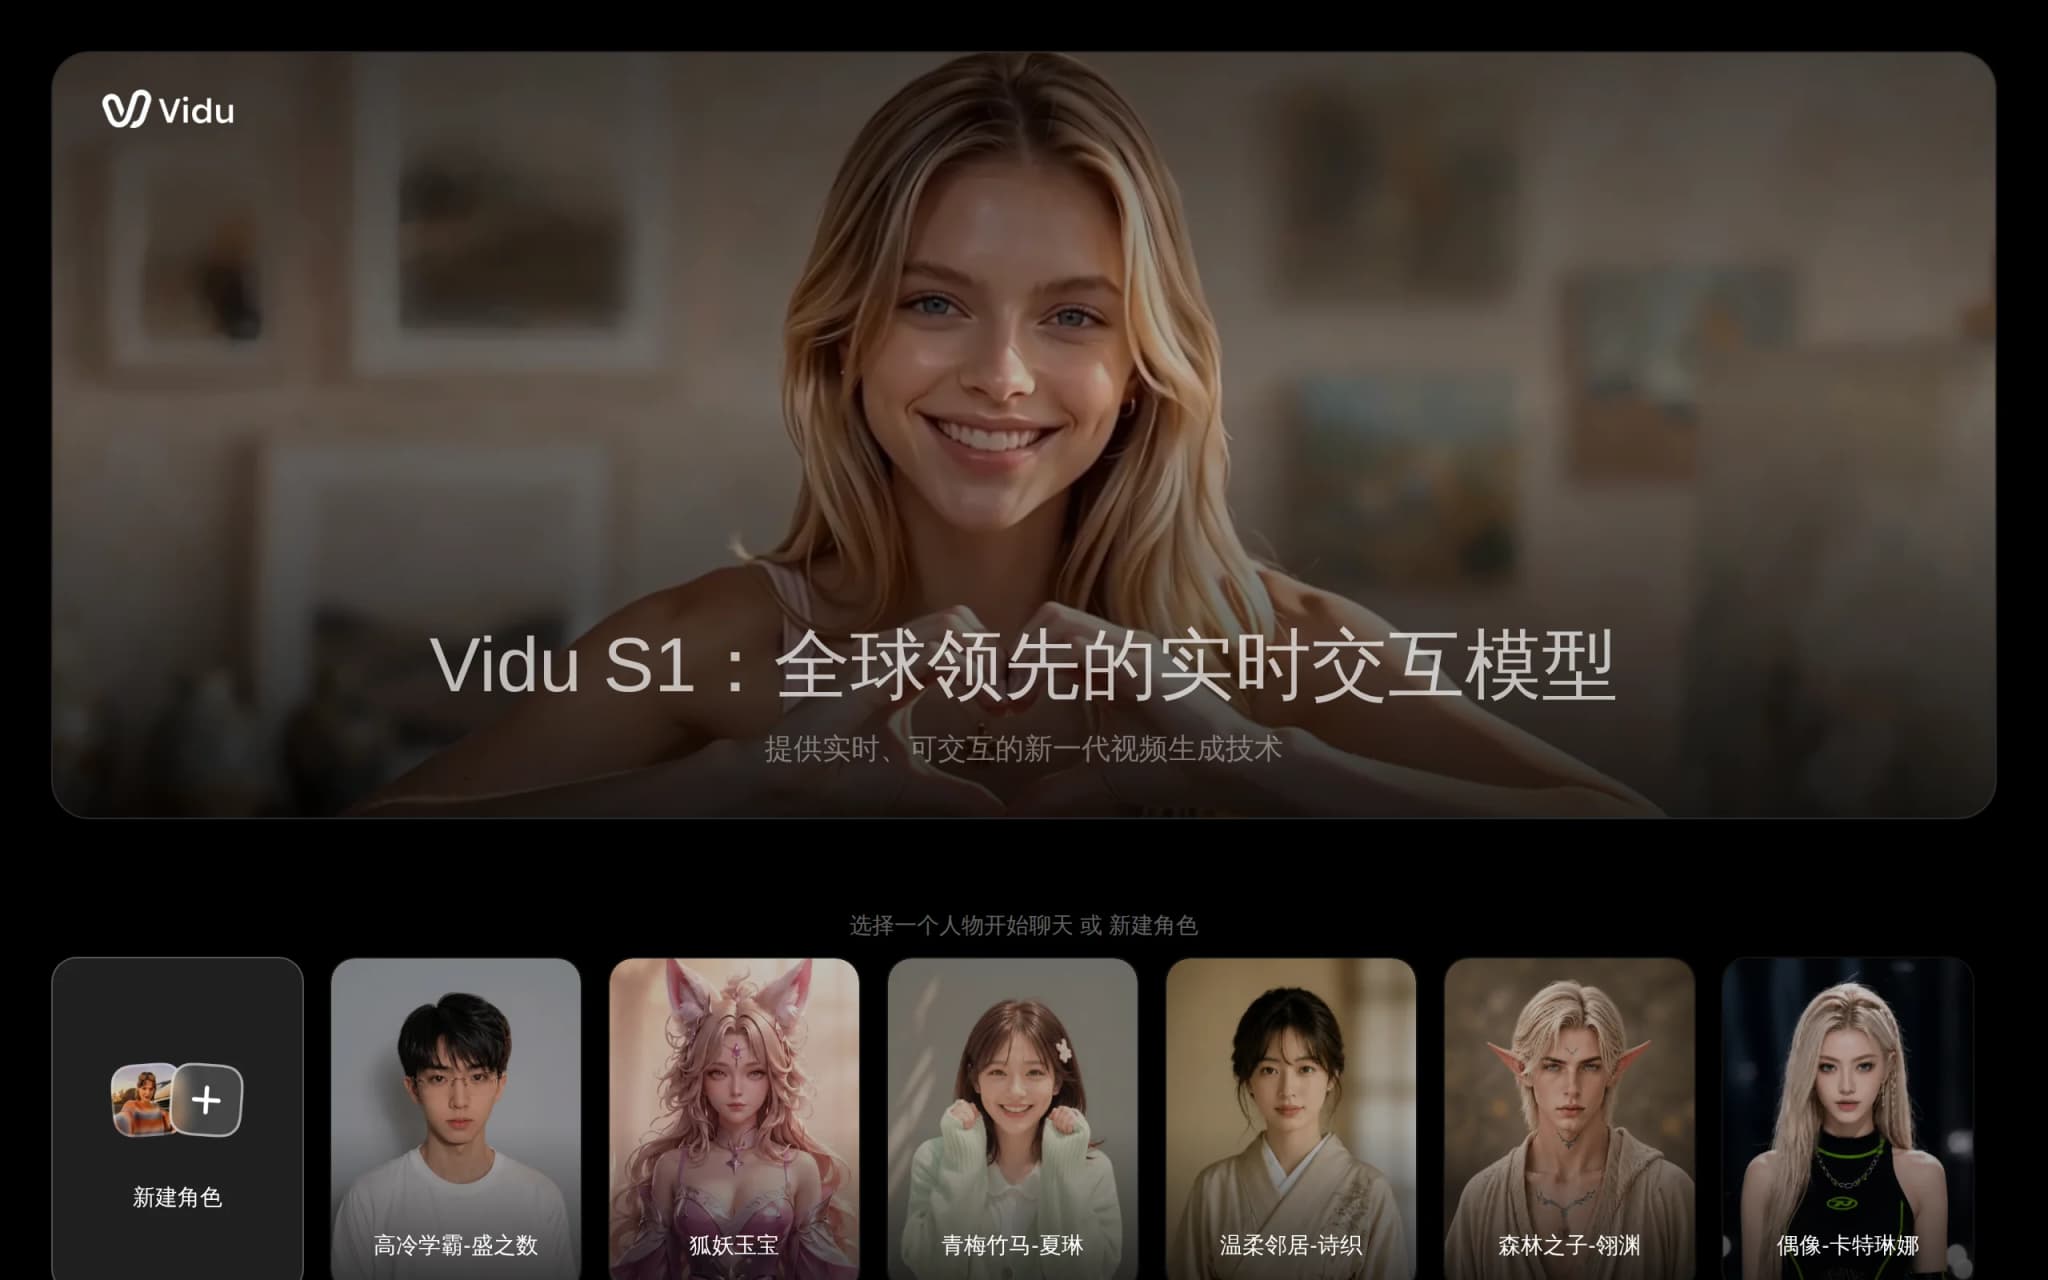
Vidu S1 – Real-Time Interactive Video Foundation Model by Shengshu Technology
Vidu S1 is a globally leading real-time interactive video foundation model launched by Shengshu Technology, marking the transition of AI video generation from offline batch rendering to real-time bidi...
WorldCupVoice – Open-Source AI Real-Time Sports Commentary System
WorldCupVoice is an AI real-time sports commentary system built on open-source principles. By integrating with Agora RTC live streams, it uses vision models to analyze match footage in real time, gene...
Wan-Streamer – Alibaba's Open-Source Real-Time Full-Duplex Multimodal Foundation Model
Wan-Streamer is an end-to-end real-time full-duplex multimodal foundation model open-sourced by Alibaba DAMO Academy. It unifies text, audio, and video input/output tokens into a single causal sequenc...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.