
Space Bunny – Anonymous Free Multimodal Large Language Model Tops Daily Usage on OpenRouter
Executive Summary:
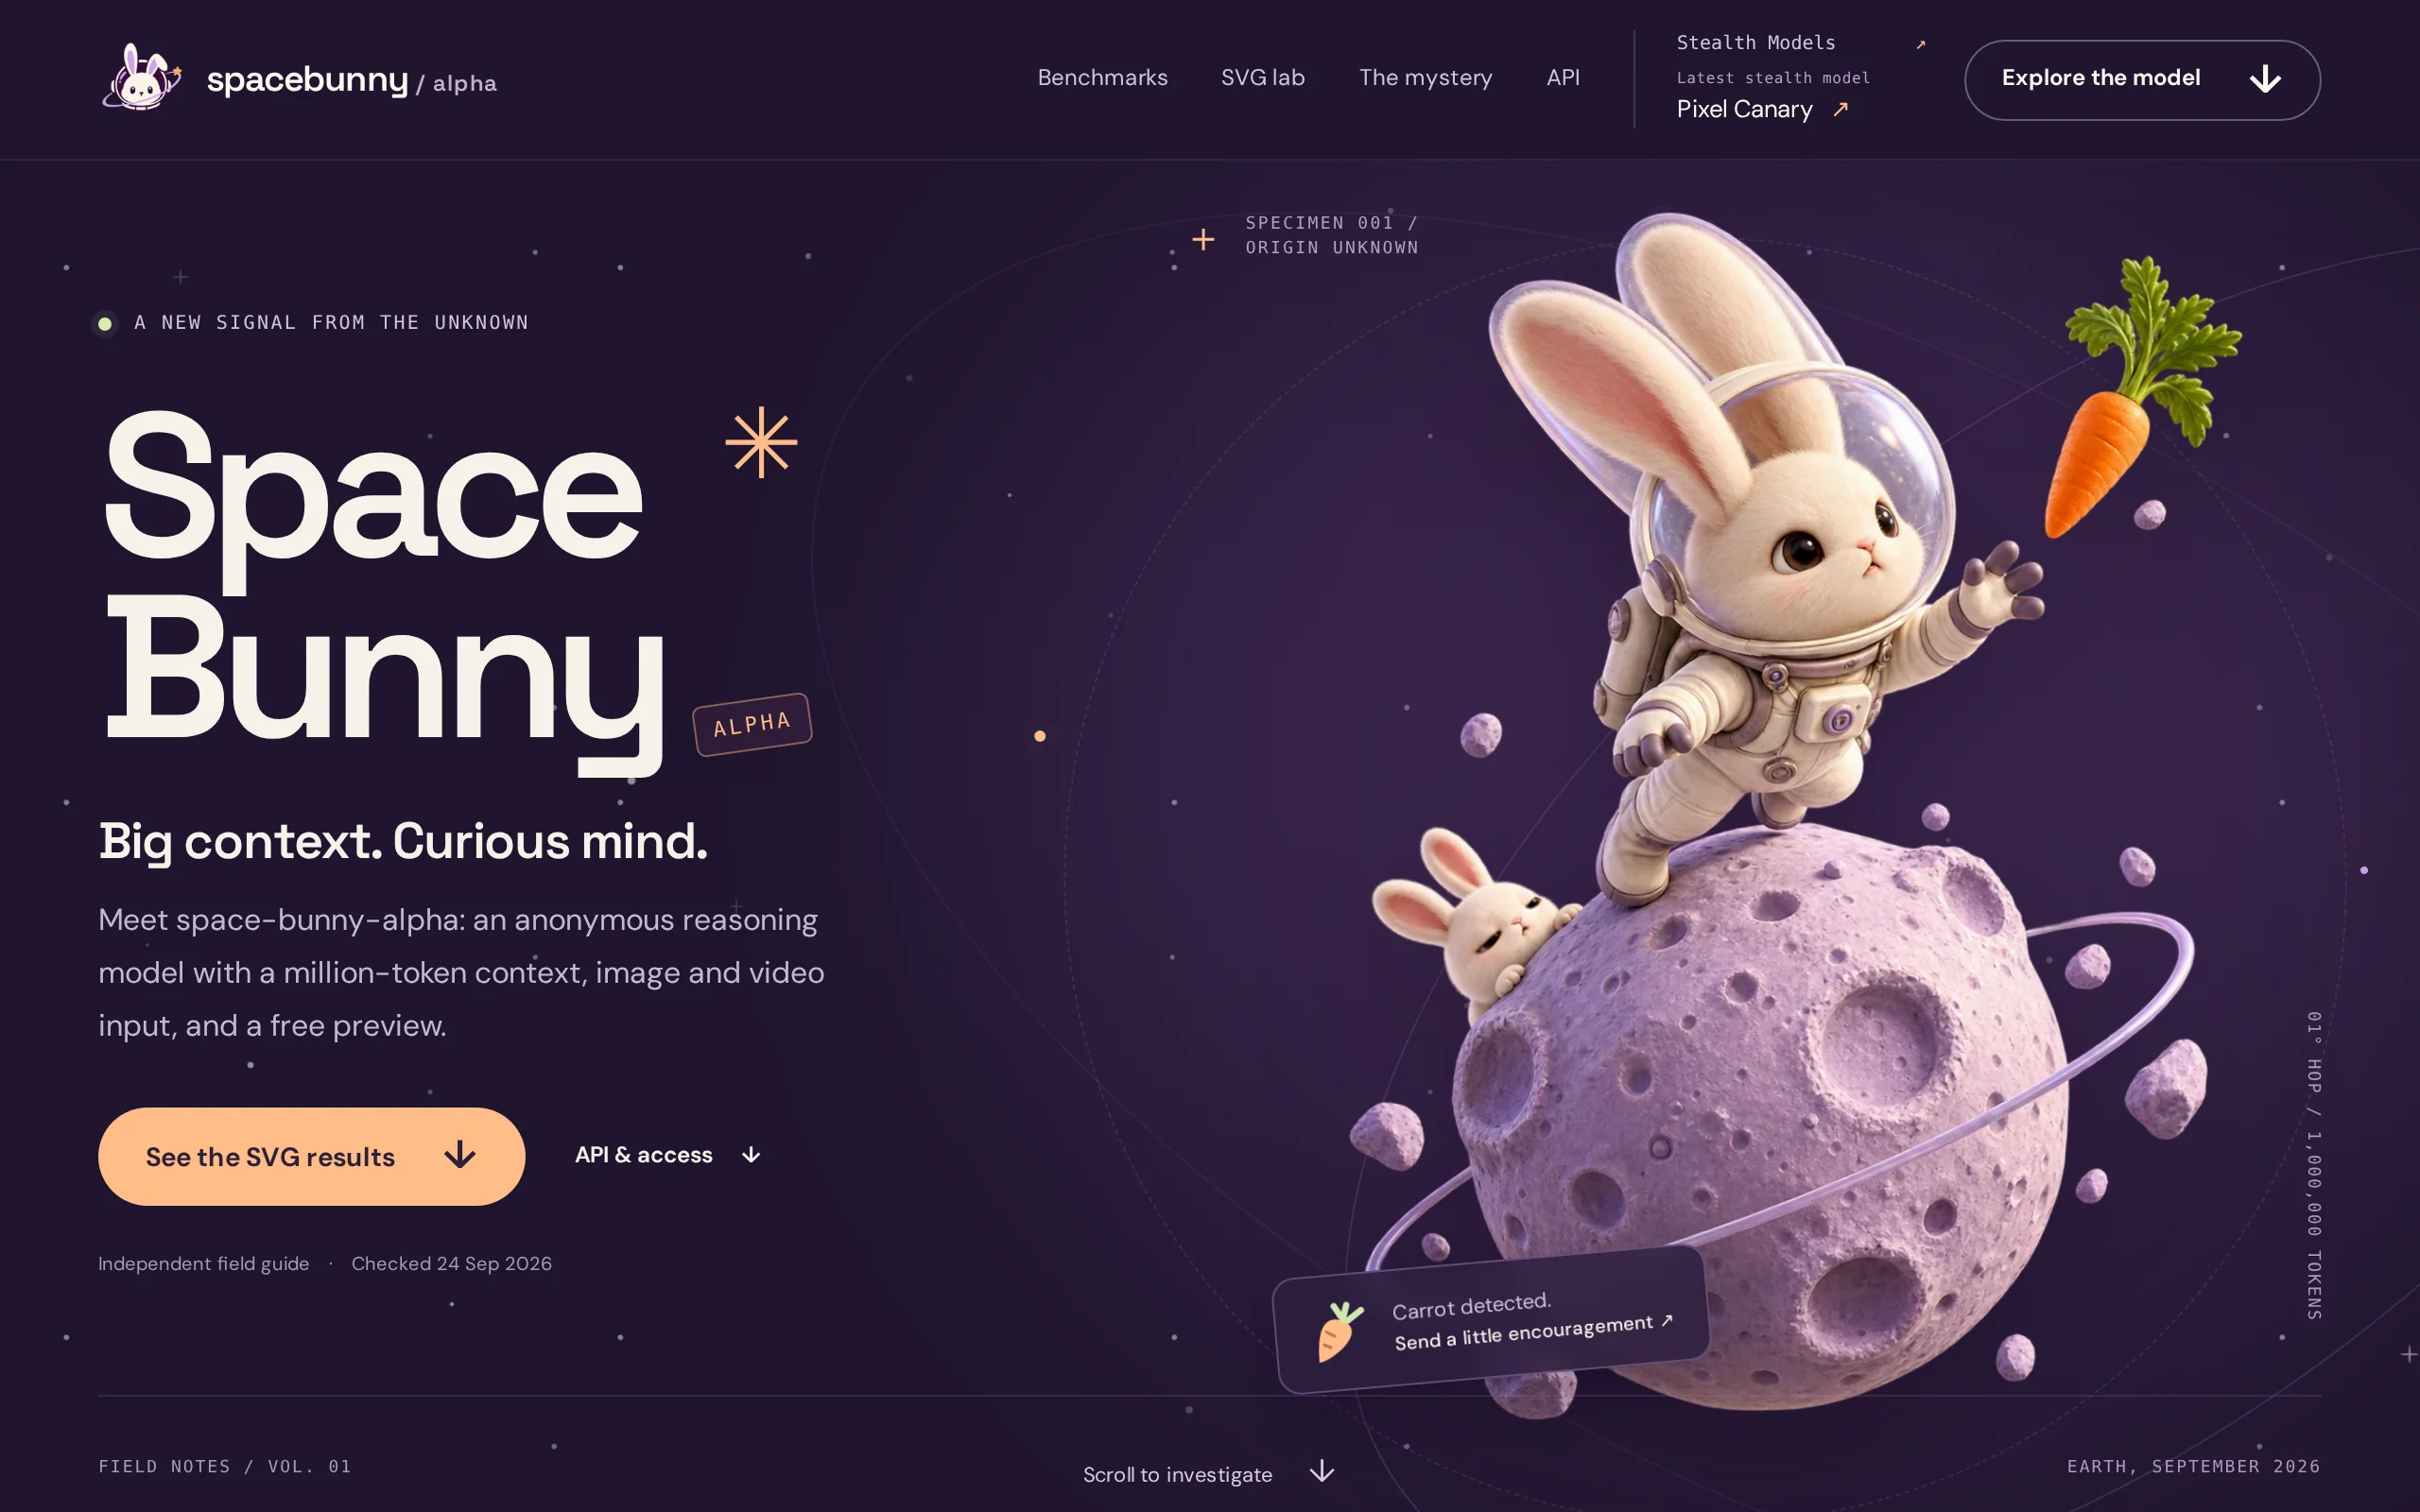
Space Bunny (Space Bunny) is a free large language model that was anonymously launched on the OpenRouter and OpenCode platforms. Within just 3 days of its release, it climbed to the top of the daily u...
1. What is Space Bunny
Space Bunny (Space Bunny) is a free large language model that was anonymously launched on the OpenRouter and OpenCode platforms. Within just 3 days of its release, it climbed to the top of the daily usage rankings on both platforms, thanks to its fast inference speed, strong programming capabilities, and native multimodal input support. The model features a context window of 1 million Tokens, with a maximum single output of 524,288 Tokens, and supports three input formats: text, image, and video. Community developers have praised its inference speed as "approximately equivalent to GLM 5.3 Flash but even faster," and it excels in generating complete websites, game prototypes, and visual works. It also provides multiple inference intensity levels – low, high, and max – to accommodate a wide range of needs, from quick Q&A to complex Agent tasks.
Technical positioning and domain: It belongs to the intersection of natural language processing and multimodal understanding. It is positioned as a high-performance general-purpose large model aimed at developers and creative professionals, emphasizing inference speed, programming efficiency, and native multimodal input capabilities. The model was released anonymously, aiming to gain market recognition through its actual performance rather than brand endorsement.
Development background: As of now, the development team of Space Bunny has not disclosed any identity information. Core technical details such as parameter count, whether it uses MoE (Mixture of Experts) architecture, and attention mechanisms remain confidential. This anonymous release strategy has sparked significant attention within the AI community, with speculation that it may be backed by strong technical expertise and computational resources.
Core value: This model addresses efficiency bottlenecks faced by developers in rapid prototype validation, long document understanding, multimodal content analysis, and Agent automation workflows. Its free open strategy lowers the barrier to entry, and its 1 million Token context window and 524K maximum output capacity provide significant advantages when processing entire books, large codebases, and long-form video content.
Technical features: The core capabilities are centered around high-speed inference, native multimodal input, and ultra-long context processing. The model supports Function Calling, Tool Choice, and structured output via JSON Schema, enabling deep integration with tool calling and automated workflow scenarios. It demonstrates high completion levels in programming generation and frontend development tasks.
2. Key Features
High-speed Inference Capability: Community developers have tested and evaluated its response speed as "approximately equivalent to GLM 5.3 Flash but faster," enabling it to generate large segments of code or produce complex text outputs in an extremely short time. This feature is particularly suitable for programming scenarios requiring rapid iteration and real-time interactive applications, significantly reducing waiting time.
Ultra-long Context Window: Supports up to 1 million Tokens of context input, with a maximum single output of 524,288 Tokens. It can process entire books, large code repositories, or long video content in one go. This capability allows the model to excel in tasks such as long document analysis, global code understanding, and cross-chapter information retrieval.
Native Multimodal Input: Supports three input formats—text, image, and video—with output in text. It can handle multimodal content such as images, screenshots, and video frames, making it applicable to scenarios like UI design draft comprehension, visual question answering, and video content analysis, thereby expanding the model's application boundaries.
Adjustable Inference Strength: Offers three inference levels—low, high, and max—allowing users to flexibly balance speed and performance. For simple tasks, using the low level provides extremely fast responses, while for complex inference tasks, switching to the max level ensures high-quality outputs, achieving a dynamic balance between cost and performance.
Programming and Frontend Generation Ability: Community tests have shown that it can generate complete websites, game prototypes, and visual projects within minutes. A GPU fluid simulation demo generated as a single file reached 1,564 lines of code. In benchmark tests such as the Coding Index and AA Intelligence Index, its programming performance has been evaluated as "slightly better than GLM-5.3 Flash."
Tool Calling and Structured Output: Supports Function Calling, Tool Choice, and JSON Schema structured output, enabling seamless integration with development toolchains and automation workflows. This feature allows the model to perform multi-step Agent tasks, making it suitable for building complex automated workflows.
3. How to Use
Register for an OpenRouter account: Visit the OpenRouter official website and complete registration and login using an email or Google account. OpenRouter is an API platform that aggregates multiple large models, providing a unified interface for model calls.
Find the target model: Search for
stealth/space-bunny-alphain the model list and go to the model details page to view basic information such as context length, input modality, and pricing. This model is marked with thestealthprefix, indicating its anonymous release nature.Create an API Key: Generate a dedicated API Key on the Keys page in your account settings, which will be used for authentication in subsequent API calls. The API Key is a necessary credential for accessing model services and should be properly safeguarded to prevent leaks.
Choose the calling method: You can directly use the free chat trial in the Chat window on the OpenRouter website without writing any code. For scenarios requiring integration into an application, configure the OpenRouter API endpoint and API Key in your code, and set the model name to
stealth/space-bunny-alphato initiate requests.Adjust parameters for use: Set the inference level (low / high / max) based on the complexity of the task, and enable tool calling, multimodal input, or JSON Schema structured output as needed. It is recommended to use the low level for simple Q&A scenarios and to switch to the max level for complex programming or reasoning tasks.
4. Pros and Cons Analysis
| Pros |
|---|
| Ultra-fast Inference Response: Community testing shows that the invocation speed is comparable to GLM 5.3 Flash but even faster, significantly reducing task waiting time and making it suitable for high-frequency interaction and real-time generation scenarios. |
| Free Open Policy: Full functionality is available at no cost, and with high Token efficiency, a large number of tasks can be completed under zero-cost conditions, significantly lowering the barriers for development and experimentation. |
| Million-level Context Handling: A context window of up to 1 million Tokens and a maximum output capacity of 524K allows for the processing of entire books or large codebases in one go, giving it a clear advantage in long-text tasks. |
| Multimodal and Agent Compatibility: Native support for text, image, and video input, along with Function Calling and structured JSON Schema output capabilities, makes it well-suited for building complex tool calling and automation workflows. |
5. Comparative Analysis with Similar Tools
| Dimension | Space Bunny (Space Bunny) |
|---|---|
| Core Architecture | Suspected to be MoE, with approximately 428B total parameters / 23B activated (not officially confirmed) |
| Context Window | 1 million Tokens, maximum output 524K |
| Input Modalities | Text, image, video |
| Inference Modes | Three adjustable modes: low / high / max |
| Measured Speed | Community feedback: "Comparable to GLM 5.3 Flash but faster" |
| Programming Performance | Community testing completion rate: "Slightly better than GLM 5.3 Flash" |
| Open Source Policy | Anonymously released, team unknown, completely free |
Selection Recommendations: For developers seeking ultimate response speed and low-cost experimentation, Space Bunny's free policy and high Token efficiency are appealing, making it suitable for scenarios such as rapid prototype validation, front-end page generation, and creative visualization. However, attention should be paid to the stability risks associated with its anonymous nature. If the project has strict supply chain security requirements, it is recommended to evaluate and use it accordingly. For enterprise-level applications requiring full technical documentation, commercial support, and long-term stability guarantees, GLM-5.3-Flash remains a more reliable choice, with its performance on standardized benchmarks like the Coding Index officially validated. Developers are advised to weigh the task characteristics and risk preferences in actual projects and, if necessary, conduct parallel testing of both models' performance.
6. Editor's Summary
Space Bunny achieved the top spot in daily usage on OpenRouter and OpenCode within just three days under an anonymous identity. This phenomenon reflects the market's urgent demand for high-performance free models. From a technical perspective, its 1 million Token context window, 524K maximum output, and native multimodal input capabilities form a differentiated technical combination, particularly demonstrating competitiveness in code generation and long-text processing. Community testing data indicates that its response speed and code completion quality have reached or exceeded those of some well-known commercial models, indirectly validating its technical strength.
However, the anonymous release strategy is a double-edged sword. On one hand, it allows the model to speak solely through its performance, avoiding interference from brand influence. On the other hand, the lack of transparency regarding core architectural information makes technical evaluation subjective and raises doubts about the project's long-term sustainability. For technical selection, this means users must weigh the performance advantages against the risks of stability.
Overall, Space Bunny is suitable for developers, independent creators, and research institutions seeking rapid iteration and zero-cost experimentation, especially in practical scenarios such as front-end prototyping, creative visualization, and long-document analysis. Its tool calling and structured output capabilities also provide a solid foundation for Agent development. In the future, if the team chooses to disclose technical details and establish a robust maintenance mechanism, the model has the potential to gain broader influence within the open-source community. For now, it is advisable for users to exercise caution in critical business scenarios while closely monitoring its development progress.
7. Application Scenarios
Rapid Programming Development and Prototype Validation: Developers can generate complete websites, game prototypes, and visual projects using Space Bunny within minutes. Community-tested cases include generating a portfolio website and reproducing a Minecraft-style prototype in 15 minutes. It is suitable for front-end development, UI design validation, and interactive prototype testing.
Creative Visual Content Creation: The model can generate high-completion interactive visual content, such as a GPU fluid simulation demo with 1,564 lines of code, from a single file without requiring manual coding. It is applicable for data visualization, artistic creation, teaching demonstrations, and product presentations, significantly reducing the technical barriers to creative implementation.
Long Document and Large Codebase Analysis: With a 1 million Token context window, the model can process entire books or large project codes in one go, combined with multimodal input understanding of screenshots and design drafts. It is ideal for code reviews, document summarization, cross-file logical analysis, and knowledge base construction.
Agent-Based Automated Workflow Construction: Supports Function Calling, Tool Choice, and structured JSON Schema output, enabling integration with a toolchain to perform multi-step tasks. It is suitable for automated data processing, information retrieval, report generation, and business process orchestration, achieving end-to-end intelligent workflows.
Multimodal Content Understanding: Supports three input formats: text, image, and video, applicable for video content analysis, UI screenshot interpretation, and visual question answering. It helps users quickly extract key information from images and videos, assisting with content moderation, interface design, and educational research.
8. FAQ
Q: Is Space Bunny free to use?
A: Yes, Space Bunny is fully open and free on the OpenRouter and OpenCode platforms, and API calls do not require payment. Users only need to register for an OpenRouter account and create an API Key to use all features for free via the web-based Chat window or through code interfaces. This free strategy makes it an ideal choice for low-cost development and experimentation.
Q: What input types does Space Bunny support?
A: Space Bunny natively supports three input types: text, image, and video, with output being text. It can process multimodal content such as images, screenshots, and video frames, making it suitable for scenarios like UI design draft understanding, visual question answering, and video content analysis. The model does not support image or video generation as output.
Q: How can I adjust the inference strength of Space Bunny?
A: The model provides three inference levels: low, high, and max. Users can flexibly choose based on the complexity of the task. For simple Q&A or quick generation scenarios, the low level is suitable to achieve extremely fast response times. For complex reasoning, code generation, or long-text tasks, it is recommended to switch to the high or max levels to ensure output quality. It should be noted that inference levels cannot be completely turned off.
Q: What is the context window size of Space Bunny?
A: Space Bunny has a context window of 1 million Tokens, with a maximum single output of 524,288 Tokens. This configuration allows it to process entire books, large codebases, or long video content in one go, giving it a significant advantage in tasks involving ultra-long text understanding and generation.
Q: Is the core architecture of Space Bunny publicly available?
A: Not currently. Core information such as the model's parameter count, whether it uses a MoE (Mixture of Experts) architecture, and its attention mechanism has not been disclosed. The identity of the development team is also anonymous. The community speculates that it may use a MoE architecture with approximately 428B total parameters and 23B activated, but this information has not been officially confirmed.
Q: How does Space Bunny perform in programming tasks?
A: Community testing feedback indicates that Space Bunny can generate complete websites, game prototypes, and visual projects within minutes. Its programming completion level has been evaluated as "slightly better than GLM-5.3 Flash." The model supports Function Calling, Tool Choice, and JSON Schema structured output, enabling deep integration with programming toolchains and Agent automation scenarios.
9. Project Links
- Official Information Station for Space Bunny Alpha: https://spacebunnyalpha.com/
- OpenRouter Model Calling Entry: https://openrouter.ai/ (search for
stealth/space-bunny-alphawithin the platform) - Official Trial and API Entry for Space Bunny: https://spacebunnymodel.com/
- GitHub Discussion Organization: https://github.com/space-bunny
- GitHub Community Build Examples: https://github.com/network-tocoder/space-bunny-real-world-builds
Related AI Model Articles
Mistral Large 4 – Mistral AI's Most Flagship Open-Source Large Model
Mistral Large 4 is the latest flagship open-source large model launched by Mistral AI, a French artificial intelligence company, and is nicknamed "Le Chonk" (the chubby cat). This model employs a fine...
EmbeddingGemma 2 – Review of Google's Open-Source Native Multimodal Embedding Model
EmbeddingGemma 2 is an open-source native multimodal Embedding model developed by Google, built upon the Gemma 4 architecture. It unifies five modalities—text, code, images, video, and audio—into a si...
Nano Banana 2.1: In-Depth Review of Google DeepMind's Image Generation and Conversational Editing Model
Nano Banana 2.1 (Model ID: gemini-nano-banana-2.1) is the second-generation image generation and conversational editing model officially released by Google DeepMind on October 6, 2026. It belongs to t...
Kling 4.0 – A New Generation AI Video Generation Model Launched by Kuaishou
Kling 4.0 is the latest generation video generation model introduced by Kuaishou's Keling AI. The lightweight version, Kling 4.0 Flash, is now open for early access, with the full version expected to ...
© All Rights Reserved. Some content on this site is partially generated by AI with human review.