
BlenderWorld – Qwen's Open-Source 3D Creation Agent Evaluation Benchmark
Executive Summary:
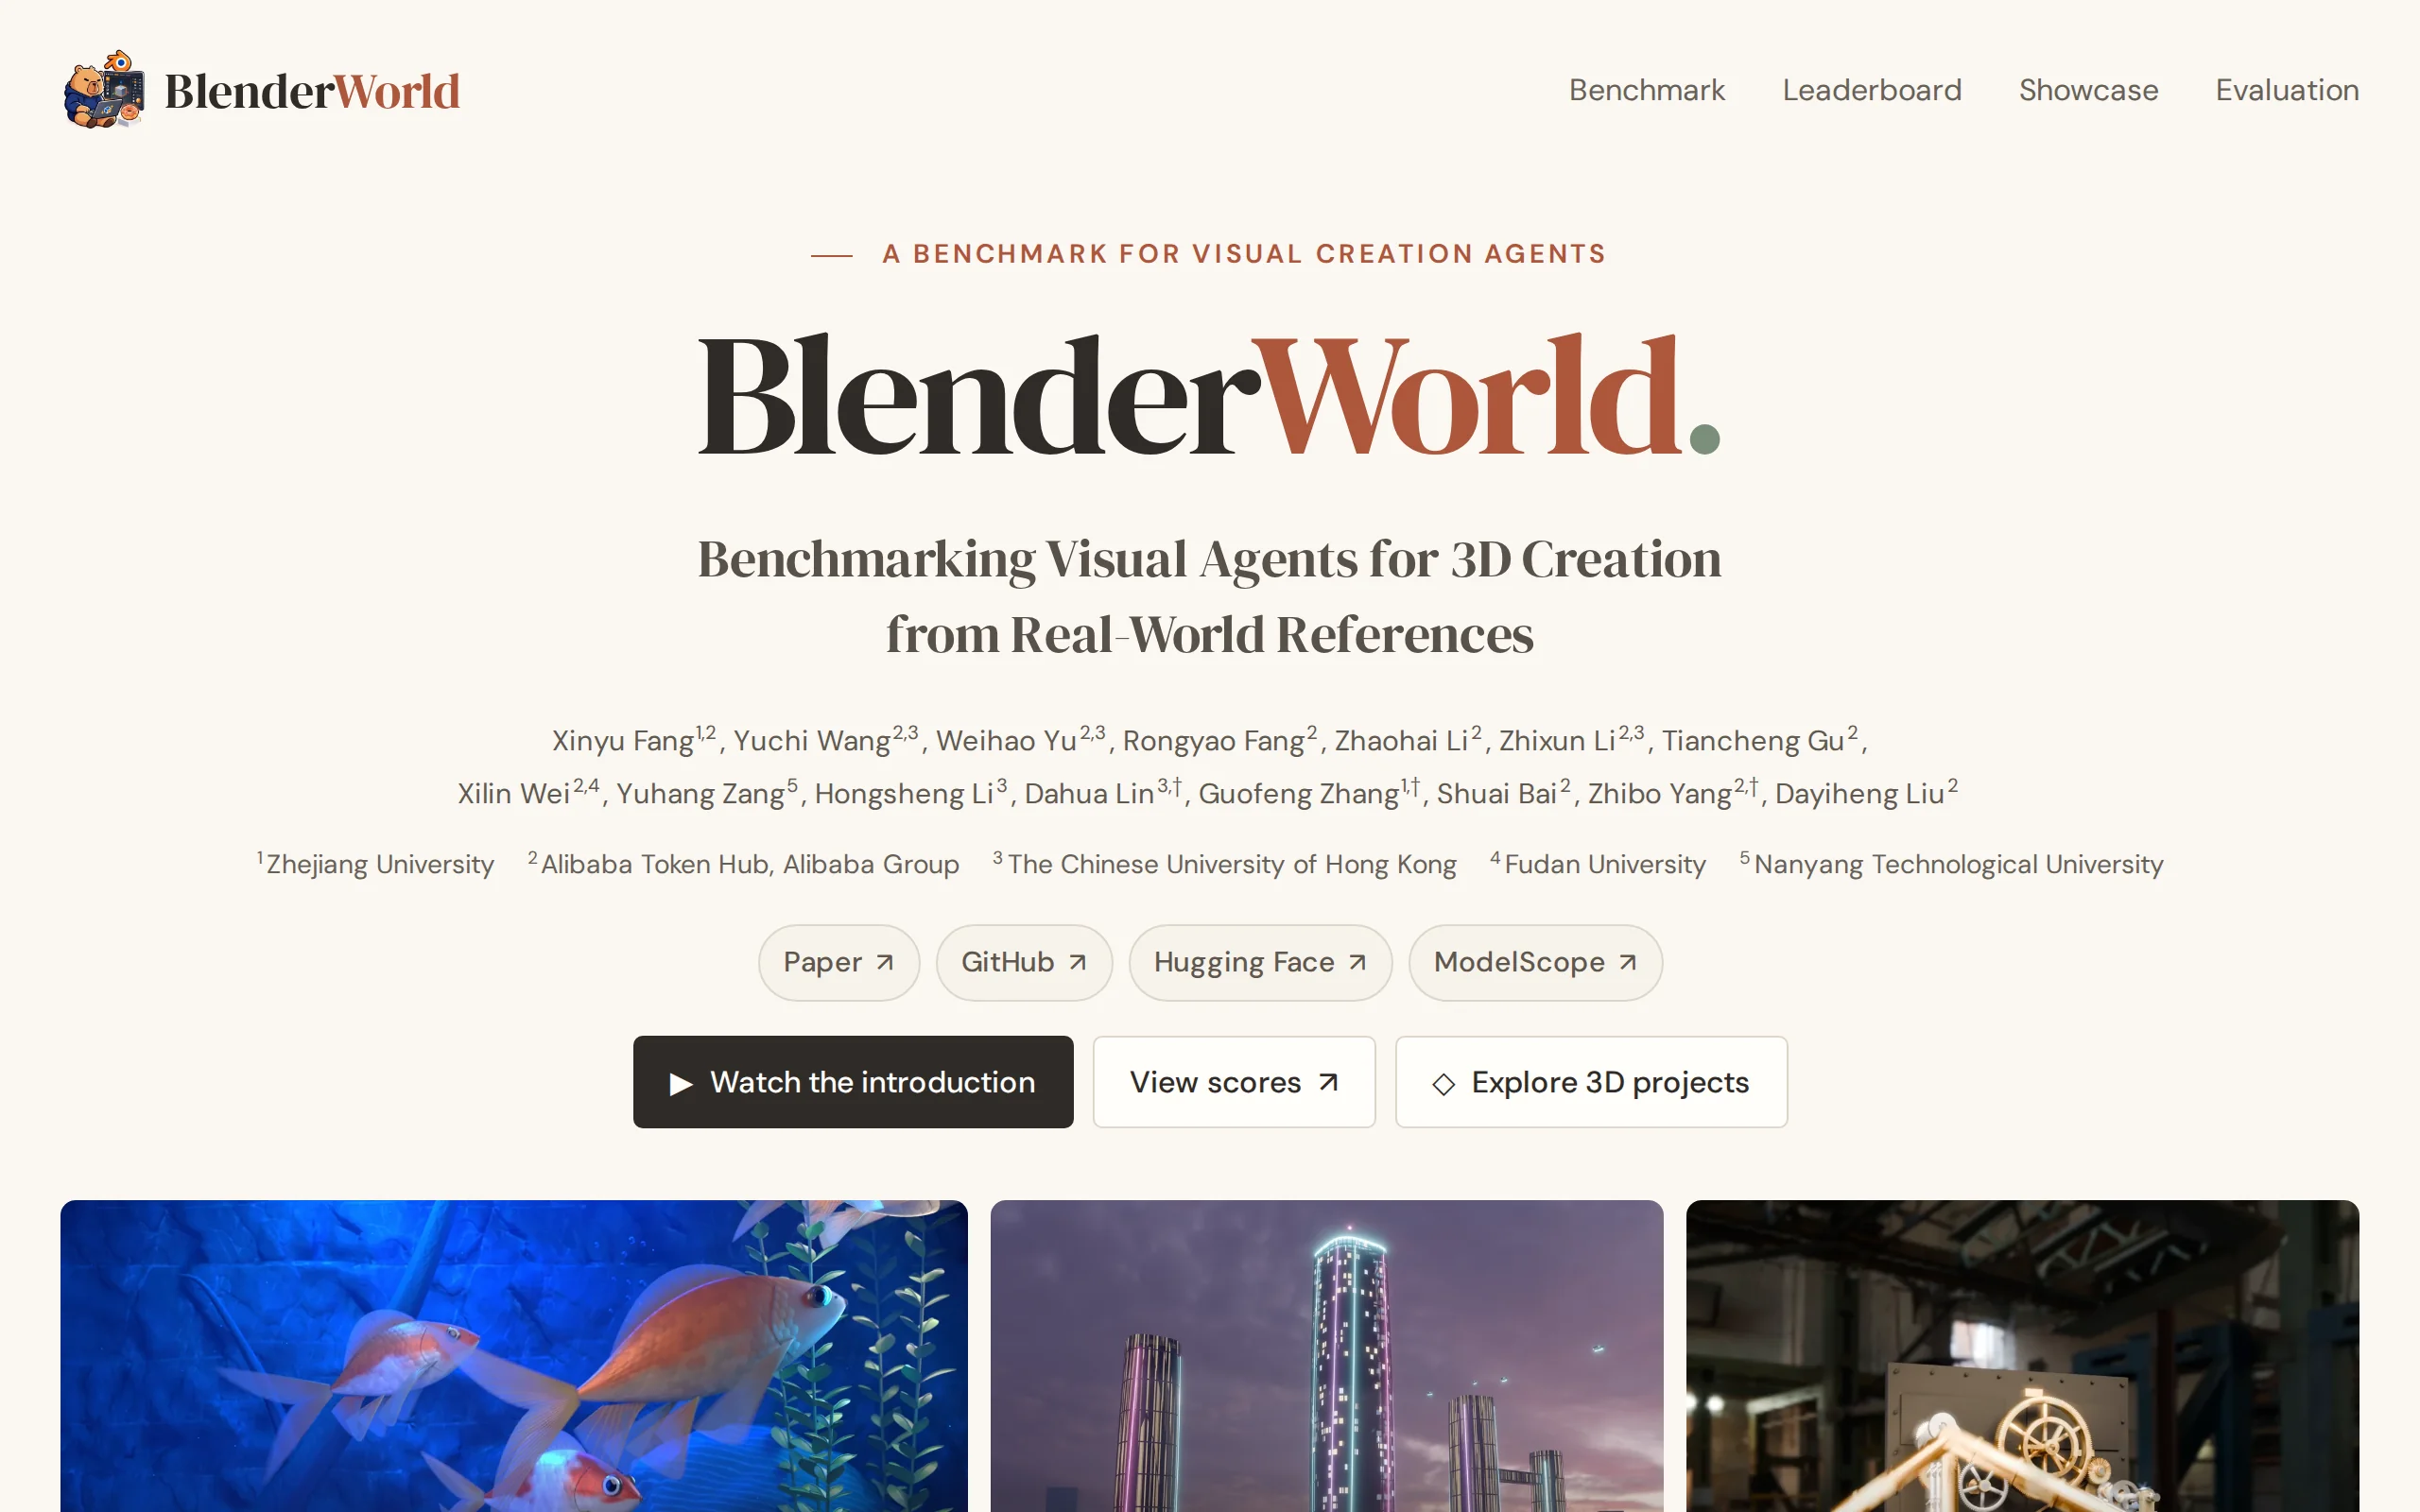
BlenderWorld is an evaluation benchmark for 3D creation agents, jointly developed by the Qwen team with Zhejiang University, The Chinese University of Hong Kong, Fudan University, and National Univers...
1. What is BlenderWorld
BlenderWorld is an evaluation benchmark for 3D creation agents, jointly developed by the Qwen team with Zhejiang University, The Chinese University of Hong Kong, Fudan University, and National University of Singapore. It includes 223 real-world production tasks, used to test whether AI systems can generate editable 3D engineering files within the Blender environment based on photos, videos, or design specifications. This benchmark employs a dual-track review mechanism combining multi-view rendering and native engineering structure checks, using 2,651 acceptance criteria to comprehensively evaluate task completion and visual quality. In practical tests with 13 mainstream systems, the top-performing GPT-6-Astra achieved only 42.2% full compliance with tasks, highlighting the significant shortcomings in the reliability of current visual agents for 3D engineering delivery.
Technical Positioning and Domain: BlenderWorld falls within the interdisciplinary research area of 3D content generation and agent evaluation, focusing on the engineering evaluation of visual language models driving Blender to complete the full 3D production workflow. Unlike traditional text-to-3D or image-to-3D models that assess asset quality, this benchmark explicitly requires the delivery of editable .blend engineering files, upgrading the evaluation target from "model generation capability" to "agent end-to-end task execution capability," thus filling the gap in standardized evaluation for 3D creation agents.
Development Background: Initiated by the Qwen team and completed in collaboration with academic institutions such as Zhejiang University, The Chinese University of Hong Kong, Fudan University, and National University of Singapore, this benchmark was created in response to the observation that although multimodal large models show potential in the 3D content generation field, the industry lacks an objective evaluation system to measure the reliability of agents in delivering engineering files within real production toolchains. Existing benchmarks often focus on texture quality or geometric accuracy, neglecting complete production stages such as modeling, materials, lighting, and animation. Therefore, the team developed this evaluation framework tailored to real-world workflows.
Core Value: BlenderWorld addresses the pain point of "lack of standards" in the field of 3D creation agents. Its 2,651 acceptance criteria were finalized after multiple rounds of model reviews and manual verification, and are not visible to the tested agents, significantly reducing opportunities for targeted optimization or gaming the system. In the dual-track review mechanism, visual language models assess the appearance of rendered images and videos, while engineering inspection agents verify hard metrics such as precise dimensions, node structures, and animation configurations within the .blend files, which are not exposed by rendered images. This creates a comprehensive, three-dimensional evaluation system that complements visual and engineering dimensions.
Technical Features: BlenderWorld pioneers the "review first, deliver later" evaluation paradigm, requiring agents to complete a full closed-loop process from requirement parsing to engineering output within the Blender environment. Its task design covers 9 major categories and 22 subcategories of scenarios, supporting three types of reference inputs: images, videos, and pure specification files. It automatically generates 8 complementary perspective Cycles renderings as evidence, providing traceable diagnostic information for each failed task path.
2. Key Features
Complete 3D Production Workflow Evaluation: The evaluation task requires the Agent to start from a demand description and reference materials, independently complete all production stages including modeling, material design, lighting setup, camera configuration, and animation settings, and finally deliver an editable .blend project file. Unlike benchmarks that only require the generation of static assets, BlenderWorld treats "project usability" as a core acceptance criterion. Any work that does not submit a project file is directly scored zero. This mechanism ensures that the evaluation results genuinely reflect the Agent's practical value rather than just its presentation capabilities.
Support for Multiple Reference Materials and Multimodal Inputs: The task system includes 130 image reference tasks, 15 video reference tasks, and 78 pure specification file tasks. Image tasks assess the Agent's visual understanding and 3D reconstruction capabilities. Video tasks further test its ability to capture motion patterns and temporal information. Pure specification tasks evaluate the Agent's reasoning and design capabilities based on abstract textual constraints. These three types of input collectively form a comprehensive capability assessment matrix.
Broad Task Coverage Across Domains: The evaluation content spans nine major categories, including architectural interior design, product manufacturing, vehicle mechanics, character and animal modeling, natural environments, animation simulation, and scientific visualization, further subdivided into 22 sub-scenarios. The wide coverage ensures that the evaluation results have strong generalizability and representativeness, allowing developers to precisely identify the model's strengths and weaknesses in specific domains based on sub-category scores.
Dual-Track Automated Review System: The system employs a dual-track review strategy, combining a Visual Language Model (VLM) with an engineering inspection Agent. The VLM is responsible for analyzing rendered images and video sequences to assess visual appearance, spatial layout, and motion plausibility. The engineering inspection Agent directly reads the native structure, attribute parameters, and node connection relationships of the .blend file using tools, verifying precise dimensions, internal structures, and animation configuration information that cannot be captured by rendered images, referencing visual evidence only when necessary for judgment.
Automatically Generated Multi-Perspective Evidence: The evaluation environment reads the Agent's submitted project in an isolated sandbox. Based on the task type and acceptance criteria, the Automatic Agent Render tool selects 8 complementary perspectives, rendering visual evidence at a resolution of 1024×1024 with 64 samples using the Cycles renderer. For video tasks, an ordered frame sequence is additionally captured as motion evidence, ensuring that the review materials comprehensively cover all dimensions and dynamic performances of the object.
Dual-Dimensional Comprehensive Scoring Mechanism: The scoring system uses a weighted composite score, with Rubric acceptance scores and Dimension aesthetic scores each accounting for 50%. It also separately reports the Perfect pass rate (the percentage of tasks that meet all acceptance criteria). This mechanism quantifies the degree to which requirements are met while also considering the subjective dimension of visual quality, providing developers with a multidimensional model capability profile and avoiding evaluation bias caused by a single metric.
3. How to Use
Install ModelScope SDK: First, execute
pip install -U modelscopein your Python environment to install the ModelScope data download tool. It is recommended to use Python 3.8 or higher, and ensure that your network environment can access the ModelScope open-source community normally.Download the Benchmark Dataset: Run the command
dataset_snapshot_download(dataset_id="Qwen/BlenderWorld", local_dir="./BlenderWorld-data")to download the complete dataset containing 223 task requirements, reference materials, and evaluation criteria to your local machine. The dataset includes three types of reference inputs: images, videos, and specification files, with a total data size of several gigabytes.Integrate Your Own 3D Agent: Connect the Agent to be evaluated with the Blender environment, enabling it to read the task requirement documents and reference materials, and autonomously complete the modeling, material, lighting, camera, and animation production processes. Finally, the Agent should output a
.blendproject file and corresponding rendered media files. When integrating, ensure the Agent has the necessary permissions to operate the Blender Python API.Submit the Work and Undergo Dual-Track Evaluation: Submit the generated project file to an independent evaluation environment. The system will automatically perform multi-view rendering verification, with the VLM evaluating the rendered images and videos, and the engineering inspection Agent checking the internal structure of the
.blendfile. This entire process requires no human intervention. Note that the evaluation environment does not allow the Agent to fix the project content; the original exported media must be preserved as the benchmark.View Multi-Dimensional Scoring Results: After evaluation, obtain four metrics: Rubric acceptance score, Dimension aesthetic score, overall score, and Perfect pass rate. Use the failure trajectory report to identify the Agent's weak points during task execution, providing data support for subsequent iterative optimization.
4. Pros and Cons Analysis
| Pros |
|---|
| Evaluation targets closely align with real-world production needs: Requires the Agent to deliver editable .blend projects rather than single image renders. Projects not submitted receive zero points, making the evaluation results highly relevant to actual productivity. |
| Strict acceptance criteria prevent cheating: The 2,651 binary criteria were finalized after trial evaluations and cross-checked by at least two independent review models, and are invisible to the generating Agent, significantly reducing opportunities for exploitation. |
| Dual-track review addresses visual blind spots: Combining multi-view rendering with native project inspection allows the detection of internal structure, precise dimensions, and animation configurations—defects that single-view main perspective renders cannot reveal. |
| Scoring system balances completion and aesthetics: Rubric and Dimension each account for 50% of the weighted score, with a separate Perfect metric distinguishing between "high requirement coverage" and "complete and reliable delivery," offering a multi-dimensional perspective for detailed assessment. |
| Broad task coverage and diverse reference formats: The 223 tasks span 9 major categories and 22 subcategories, supporting three types of input: images, videos, and pure specification files, giving the evaluation results strong generalizability and representativeness. |
5. Comparative Analysis with Similar Tools
| Comparison Dimension | BlenderWorld | 3DGen-Bench |
|---|---|---|
| Benchmark Focus | Engineering delivery capability benchmark for 3D creation agents | Asset quality benchmark for 3D generation models |
| Evaluated Objects | Visual agents driving Blender (e.g., GPT-6-Astra) | Text-to-image-to-3D generation models (including the Hunyuan 3D series) |
| Deliverable Requirements | Complete editable .blend project + supporting media; no project means zero points | 3D mesh and texture assets only; no requirement for editable projects |
| Task Types and Scale | 223 real-world tasks: reconstruction / modification / reference-based design | 1,020 text + image prompts, single-asset generation |
| Task Coverage | 9 major categories and 22 subcategories: architecture, product, vehicle, character, animation, simulation, etc. | Generation quality of single objects, characters, or scene assets |
| Evaluation Method | Dual-track evaluation: VLM rendering review + Agent inspection of native project structure | Multi-view scoring model aligned with human preferences (CLIP + MLLM) |
| Scoring Nature | 2,651 binary hard acceptance criteria, clearly determining pass/fail | 5-dimensional soft preference scoring, no strict pass threshold |
| Core Metrics | Overall score, Perfect pass rate (percentage of fully compliant tasks) | Preference scores per dimension |
| Input Modalities | Image (130) / Video (15) / Specification files (78) | Text + image prompts |
| Empirical Findings | Only 42.2% of tasks are fully compliant by the strongest agent, showing significant reliability gaps | Existing generation models exhibit systematic human preference bias |
| Open Source Status | Fully open-sourced on ModelScope, GitHub, and project homepage | Dataset and evaluation model are publicly available |
Selection recommendations for different scenarios: For teams developing Blender automation pipelines or 3D content generation agents, BlenderWorld is the only benchmark that quantifies the ability to deliver complete engineering projects. Its dual-track evaluation mechanism and anti-cheating design make it particularly suitable as a regression testing tool for model iteration. Researchers can use the detailed task labels of the 223 tasks to identify the model's capability boundaries in specific areas such as modeling, animation, and simulation, thereby formulating targeted optimization strategies.
For teams focused on asset production efficiency, 3DGen-Bench's large-scale prompt library and soft scoring system are more suitable for quickly assessing the quality of batch generation. However, it does not evaluate the editability of engineering projects, and the evaluation results are somewhat distant from the actual needs of industrial production. If a balance is needed between the two, it is recommended to use BlenderWorld's core metrics as the long-term capability benchmark and to use the subjective preference scores from 3DGen-Bench as supplementary references, forming a complementary dual-track evaluation strategy.
6. Editor's Summary
The launch of BlenderWorld has established the first evaluation standard in the 3D creation Agent field centered on "engineering delivery reliability." Its technical value is primarily reflected in three aspects. First, the methodology for constructing 2,651 binary hard acceptance criteria is highly significant as a reference. The team's process—generating requirements using multimodal models, manual verification, multi-round cross-review, and freezing the standards—greatly reduces ambiguity and the potential for exploitation within the evaluation rules themselves. Second, the dual-track review mechanism demonstrates technical foresight. While a visual language model evaluates rendered images, an engineering Agent inspects the internal structure of .blend files, effectively covering precise dimensions, node connections, and animation configurations that optical rendering cannot display. This paradigm provides methodological inspiration for future Agent evaluations in other domains. Third, the 223 tasks cover nine major categories and 22 subcategories of scenarios, supporting three types of input: images, videos, and pure specification files. The evaluation dimensions include both static elements such as modeling, materials, and lighting, as well as dynamic aspects like animation and simulation, offering strong representativeness in terms of evaluation breadth.
From a practical value perspective, BlenderWorld's core metrics provide direct guidance for selection in the industry. Measured data shows that even the currently top-performing GPT-6-Astra achieves only a 42.2% Perfect pass rate. This quantitative conclusion clearly defines the overall baseline of current visual Agents in 3D creation capabilities, offering a measurable target for future technological development. This benchmark is aimed at three core user groups: engineering teams developing 3D automation tools can use it for regression testing and capability diagnosis; large model vendors can compare the delivery reliability of their proprietary systems under a unified acceptance standard; and academia can use this benchmark as a standard evaluation tool to support quantitative arguments in related papers and the development of community leaderboards.
In terms of future development potential, BlenderWorld's evaluation philosophy has the potential to extend to more industry software. Currently, the task set includes 223 items, and with the participation of more research institutions and continuous expansion of the task library, its statistical discriminability and fine-grained coverage capabilities will further improve. If future updates can provide tiered scoring reports for different modal inputs and expand verification of complex capabilities such as rigid body simulation and particle systems in the engineering inspection dimension, this benchmark has the potential to become the de facto industry standard in the field of 3D creation agents.
7. Application Scenarios
3D Agent Capability Evaluation: Provides a standardized testing environment for teams focused on developing automation tools for Blender. Developers can integrate their custom-built Agent into the benchmark environment and quantitatively evaluate its performance in three categories of creative tasks—reconstruction, modification, and reference-based design—through a system of 223 tasks, obtaining a capability profile that allows for cross-comparison.
Large Model Selection and Comparison: Enterprises and research institutions can conduct horizontal comparisons of the 3D delivery reliability of different closed-source and open-source multimodal models under the same set of 2,651 evaluation criteria. The two metrics—comprehensive score and Perfect pass rate—provide clear quantitative basis for technical selection decisions, reducing bias from subjective assessments.
Model Iteration Regression Testing: Run the BlenderWorld benchmark after each version upgrade of the Agent or base model. By observing changes in the Perfect score and failure trajectories, specific areas of capability degradation or improvement can be precisely identified. This scenario is particularly suitable for product teams to embed automated evaluation into their continuous integration workflows.
Failure Analysis and Capability Enhancement: Utilize the multi-perspective rendered evidence and execution trajectory reports automatically generated by the evaluation system to deeply diagnose typical defects in the Agent under specific scenarios (such as incorrect material parameter settings, animation timing deviations, or insufficient dimensional accuracy). Based on this, the model's self-checking logic and repair strategies can be optimized.
Research Benchmark and Community Leaderboards: BlenderWorld is released as open source and can serve as a standard evaluation tool in the field of 3D visual Agent research, supporting experimental validation in academic papers. It also enables the construction of community leaderboards, providing a unified performance reference for result comparisons and academic exchanges within the field.
8. FAQ
Q: What is the fundamental difference between BlenderWorld and common 3D generation model evaluation benchmarks?
A: Traditional 3D generation benchmarks (such as 3DGen-Bench, T3Bench) focus on the quality of the mesh and textures output by the model, which falls under asset quality assessment. In contrast, BlenderWorld evaluates the engineering delivery capability of an Agent throughout the complete production workflow. It requires the output of editable .blend engineering files, covering all aspects such as modeling, materials, lighting, and animation. Its core metric, "zero points for unsubmitted engineering files," directly anchors the evaluation logic toward practical application.
Q: What hardware requirements are needed to use BlenderWorld?
A: The hardware requirements for training and evaluation depend on the scale of the Agent being tested. Dataset downloading and engineering reviews can be completed with standard workstation CPU power, but Cycles multi-view rendering (1024×1024, 64 samples) requires significant GPU computing resources. It is recommended to equip with an NVIDIA GPU that supports CUDA (at least 8GB VRAM) to accelerate the evaluation process. For specific hardware requirements, please refer to the latest documentation in the project's GitHub repository.
Q: Can the Agent modify the engineering files during the evaluation process?
A: No. The Automatic Agent Render in the evaluation environment can adjust the camera and rendering parameters, but any operations that modify or repair the engineering content are strictly prohibited. The original exported media files serve as the baseline for evaluation, and this constraint ensures that the evaluation results reflect the true output quality of the Agent, preventing engineering flaws from being masked by post-rendering processing.
Q: How does BlenderWorld ensure the objectivity of its acceptance criteria?
A: The acceptance criteria undergo multiple quality checks: first, they are generated and rewritten by a multimodal model, then manually verified for consistency with reference materials and textual-visual alignment. Next, the criteria are extracted from the task requirements, reference materials, and attachments, and then frozen as 6–22 binary standards after trial evaluations and cross-checking by at least two independent review models. Each standard is weighted based on its importance (3/2/1), and the criteria are not visible to the tested Agent throughout the process.
Q: How should we understand the difference between the composite score and the Perfect pass rate?
A: The composite score is calculated by weighting 0.5 × Rubric acceptance score and 0.5 × Dimension visual score, reflecting dual attention to task completion and visual quality. The Perfect pass rate, on the other hand, counts the proportion of tasks that meet all acceptance criteria, serving as a stricter reliability metric. It distinguishes between two levels of model capability: "partial task coverage" and "complete and reliable delivery."
Q: Does BlenderWorld support evaluation of closed-source commercial models?
A: Yes. This benchmark provides task datasets and evaluation protocols, and does not impose any open-source restrictions on the tested Agent. Closed-source commercial models can be integrated into the Blender environment for evaluation via API or local deployment. This is also the reason why systems like GPT-6-Astra are included in practical evaluations.
9. Project Links
- Project Website: https://blenderworld.github.io/
- GitHub Repository: https://github.com/QwenLM/BlenderWorld
- Technical Paper: https://github.com/QwenLM/BlenderWorld/blob/main/docs/BlenderWorld__Benchmarking_Visual_Agents_for_3D_Creation_from_Real_World_References.pdf
- HuggingFace Dataset: https://huggingface.co/datasets/Qwen/BlenderWorld
Related

MiniMax M3.1 Flash – The Latest Flash Series Model from MiniMax
MiniMax M3.1 Flash is the new generation of the Flash series model launched by MiniMax in 2026. It made its debut under the anonymous name "Space Bunny" across major evaluation benchmarks, with a trai...
Hy Memory 2.0 – Tencent HunYuan's Open-Source Agent Memory Framework
Hy Memory 2.0 is an open-source agent memory framework developed by Tencent HunYuan, featuring a three-tier architecture: "model + framework + application." It includes the Hy-Memory-30A3B model speci...
Muse Spark Open – In-Depth Review of Meta's Open-Source Multimodal Large Model
Muse Spark Open is Meta's latest open-source multimodal large model, built using a sparse Mixture-of-Experts (MoE) architecture. It has a total parameter count of 816 billion, with only 420 billion pa...
Review of Matrix-Game 4.0: Kunlunwanwei Brings Video Large Model Games to Consumer-Level GPUs for the First Time
Matrix-Game 4.0 is the world's first open-source video large model game that can run in real-time on a single consumer-grade GPU. This system employs an innovative "Harness" architectural paradigm, de...
© All Rights Reserved. Some content on this site is partially generated by AI with human review.