
AI Model Library: LLMs, Agents & Dev Tools
Curated reviews of mainstream AI models, agents, and dev tools — capabilities, use cases, and how they compare.
Tag: Speech AI
115 article(s) found · Clear tag
TalkLikeYou — In-Depth Review of the Open-Source Real-Time Digital Human Framework from the Institute of Automation, Chinese Academy of Sciences
TalkLikeYou is an open-source real-time digital human (talking head) generation framework developed by the Institute of Automation, Chinese Academy of Sciences. Its core capability lies in generating ...
Vidu Q4 Preview: A Masterful Demonstration of Expressive Performance and Multi-Subject Consistency in ShengShu Technology's Flagship Video Generation Model
Vidu Q4 Preview is the first publicly available preview version of ShengShu Technology's next-generation flagship video generation model, launched on October 7, 2026. It emphasizes "expressive perform...
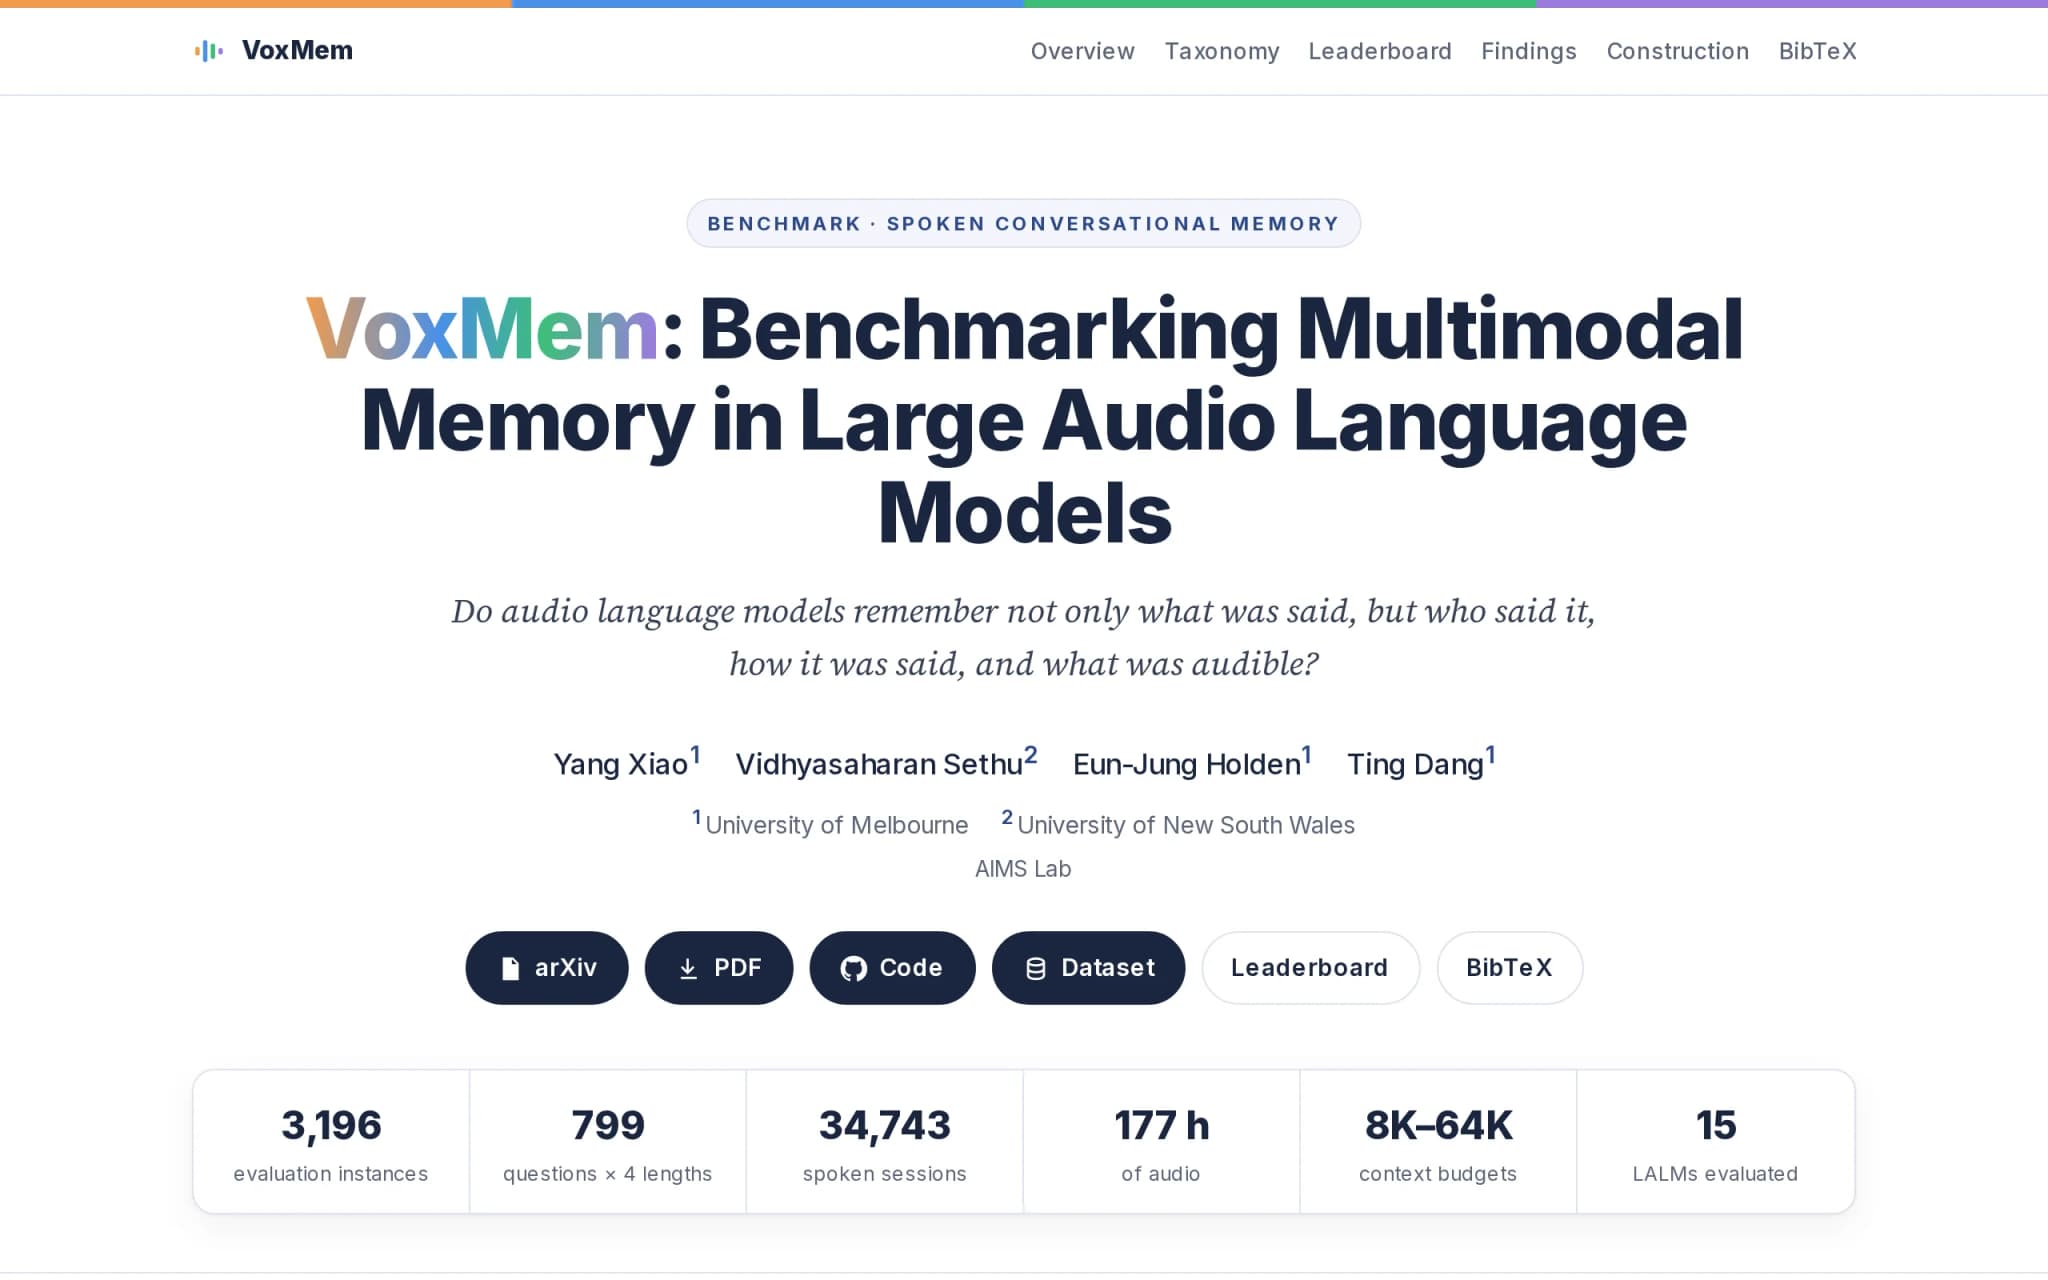
VoxMem – An Open-Source Audio Large Model Memory Benchmark from the University of Melbourne and Others
VoxMem is an audio large model memory benchmark introduced jointly by the research team from the University of Melbourne and the University of New South Wales. This benchmark pioneers a two-dimensiona...
EmbeddingGemma 2 – Review of Google's Open-Source Native Multimodal Embedding Model
EmbeddingGemma 2 is an open-source native multimodal Embedding model developed by Google, built upon the Gemma 4 architecture. It unifies five modalities—text, code, images, video, and audio—into a si...
MAI-Transcribe-2-Streaming: In-Depth Evaluation of Microsoft's Real-Time Streaming Speech-to-Text Model
MAI-Transcribe-2-Streaming is Microsoft's first real-time streaming speech-to-text model, capable of continuously outputting text while speech is being delivered. It supports 60 languages and automati...
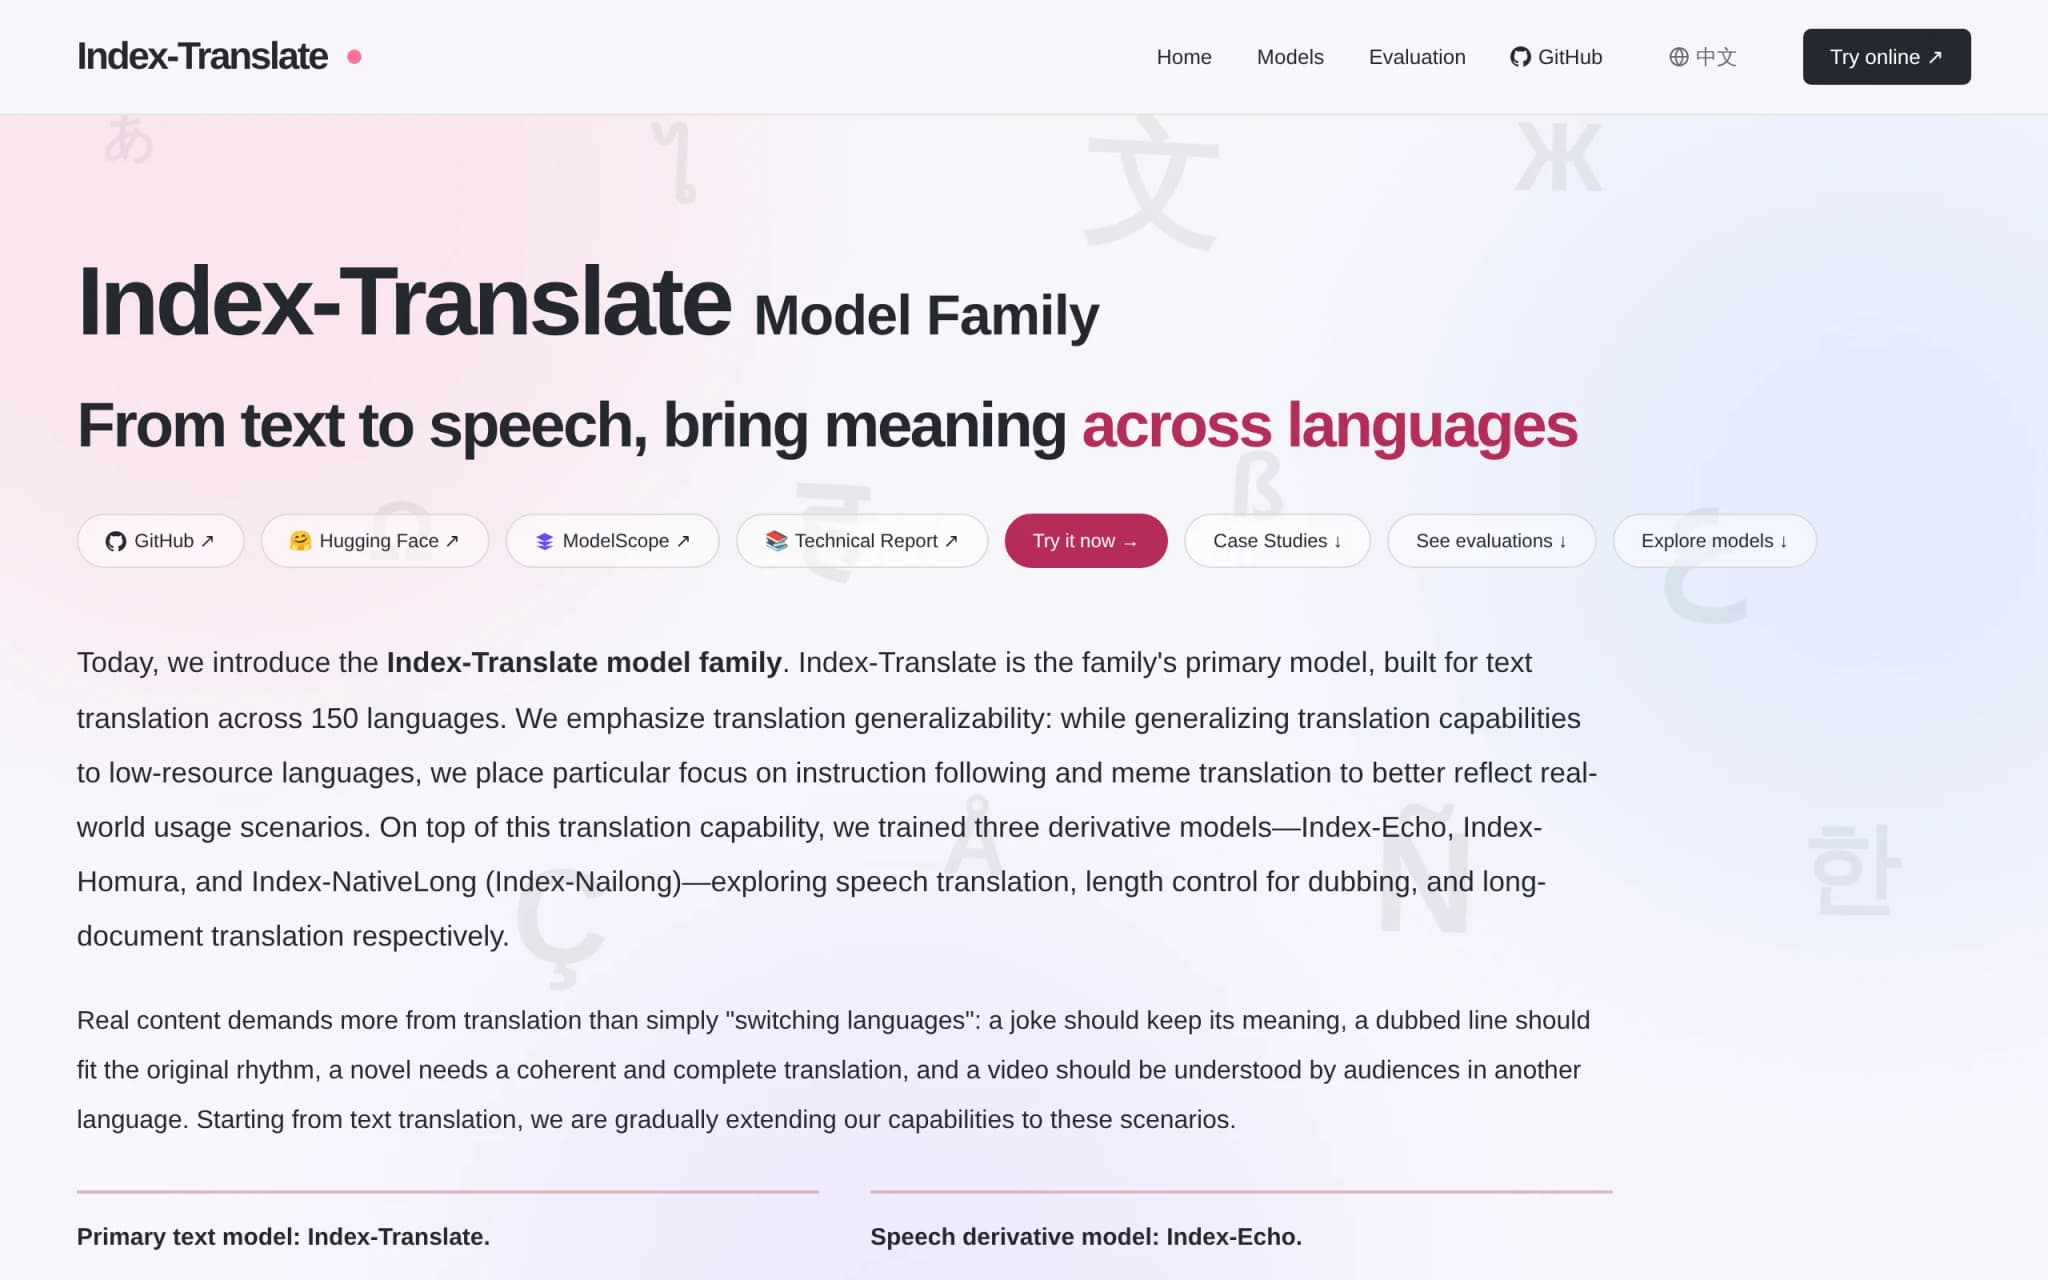
Index-Translate – Bilibili's Open-Source Multilingual Translation Model Family
Index-Translate is an open-source multilingual translation model family developed by Bilibili's Index LLM team. It is built upon the Qwen3.5 foundation and opens its weights under the Apache-2.0 licen...
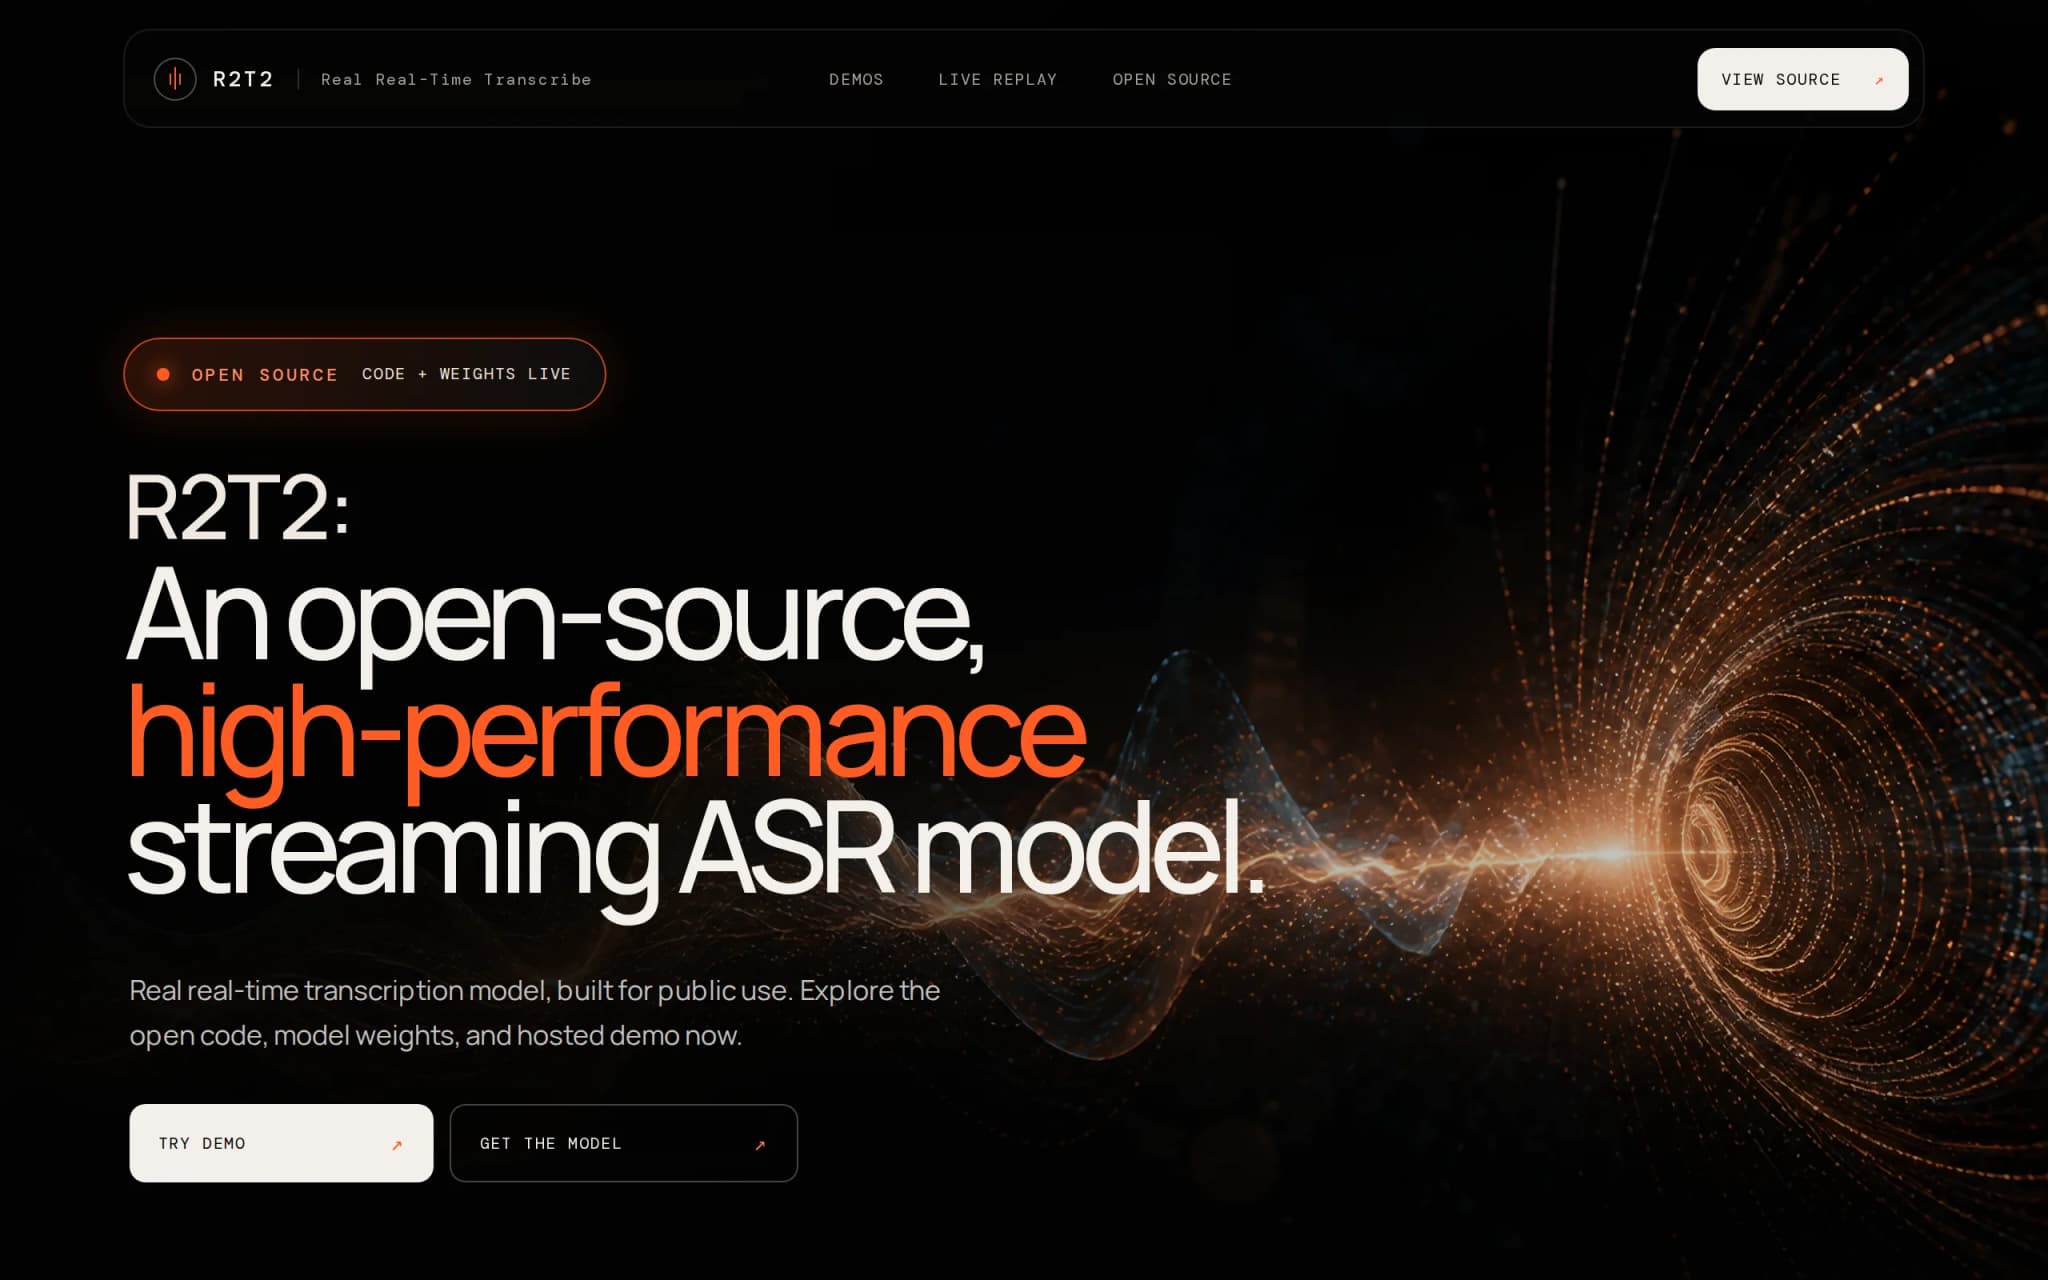
R2T2 – In-Depth Review of NetEase Youdao's Open-Source Low-Latency True Streaming Speech Recognition Model
R2T2 (Real Real-Time Transcription) is a low-latency true streaming speech recognition model open-sourced by NetEase Youdao, built upon the Qwen3-ASR architecture. It employs an append-only mechanism ...
Review of DeepSeek Harness Desktop: How the Official GUI Client Lowers the Bar for Agent Usage
DeepSeek Harness Desktop is the official graphical client launched by DeepSeek, designed to provide a visual interface for the originally command-line-based DeepSeek Harness framework. After users log...
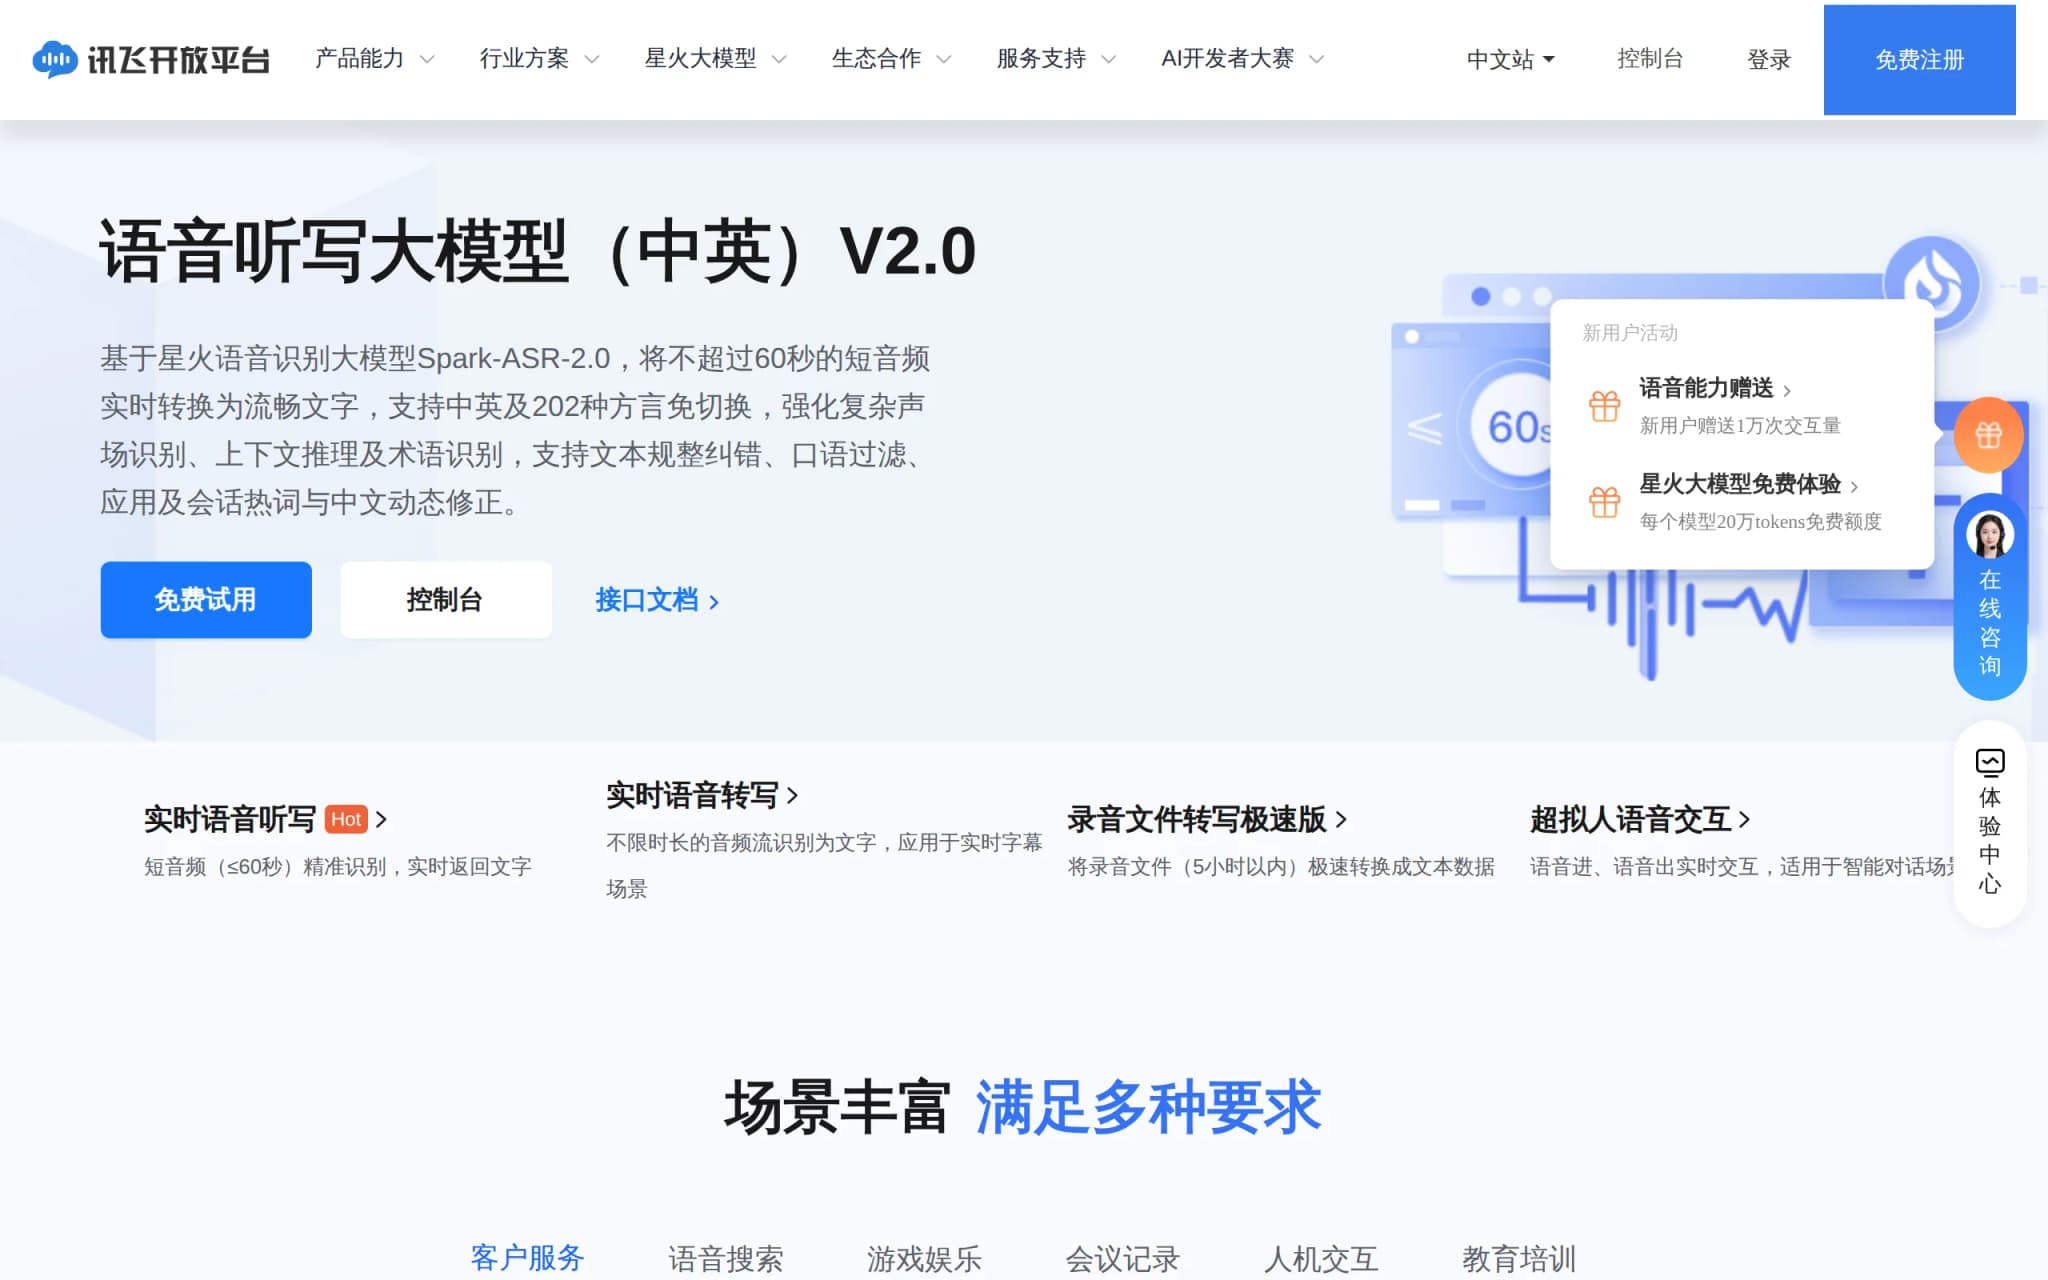
In-Depth Review of Spark-ASR-2.0: A New Paradigm in Speech Recognition with Non-Autoregressive Architecture
Spark-ASR-2.0 is the latest generation speech recognition large model launched by iFLYTEK based on its proprietary Spark-Audio speech foundation model. This model continues the non-autoregressive para...
Qwen-Audio-3.1: A Full-Stack Evaluation of the Qwen Audio Large Model Series
Qwen-Audio-3.1 is a series of large audio models launched by Alibaba's Qwen. It consists of five models: ASR speech recognition, ASR-Next audio understanding, TTS speech synthesis, TTS-Next audio crea...
Subscribe to AI Model Reviews
Get in-depth reviews the moment a new AI model drops. Know its capabilities and use cases.
We never share your email. Unsubscribe anytime.